Heart Disease Risk Predictor | End-to-End Machine Learning Project
تفاصيل العمل
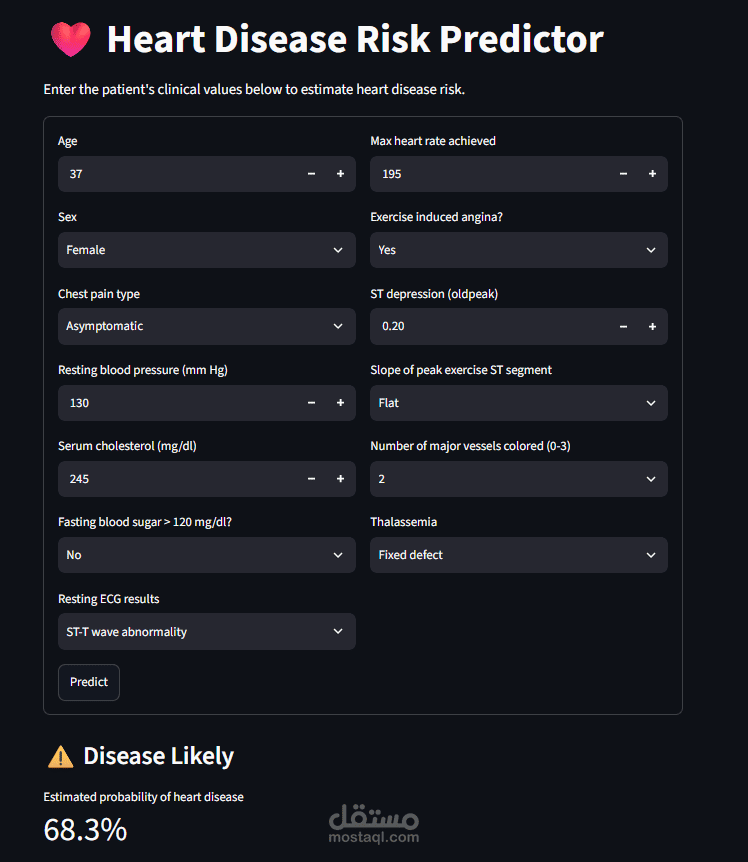
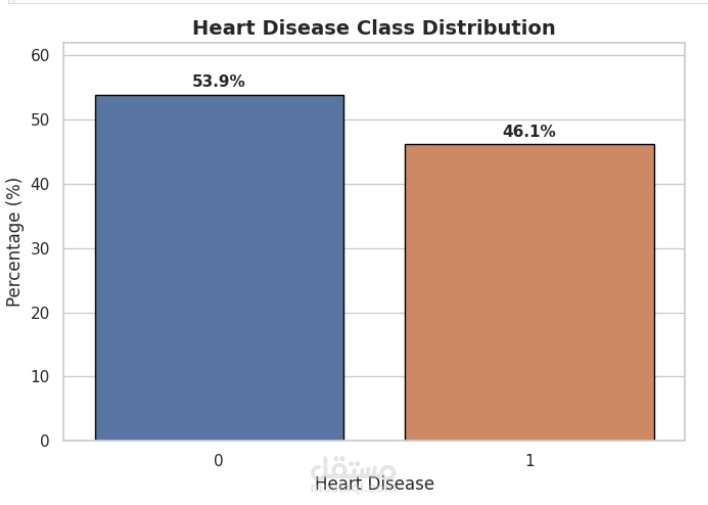
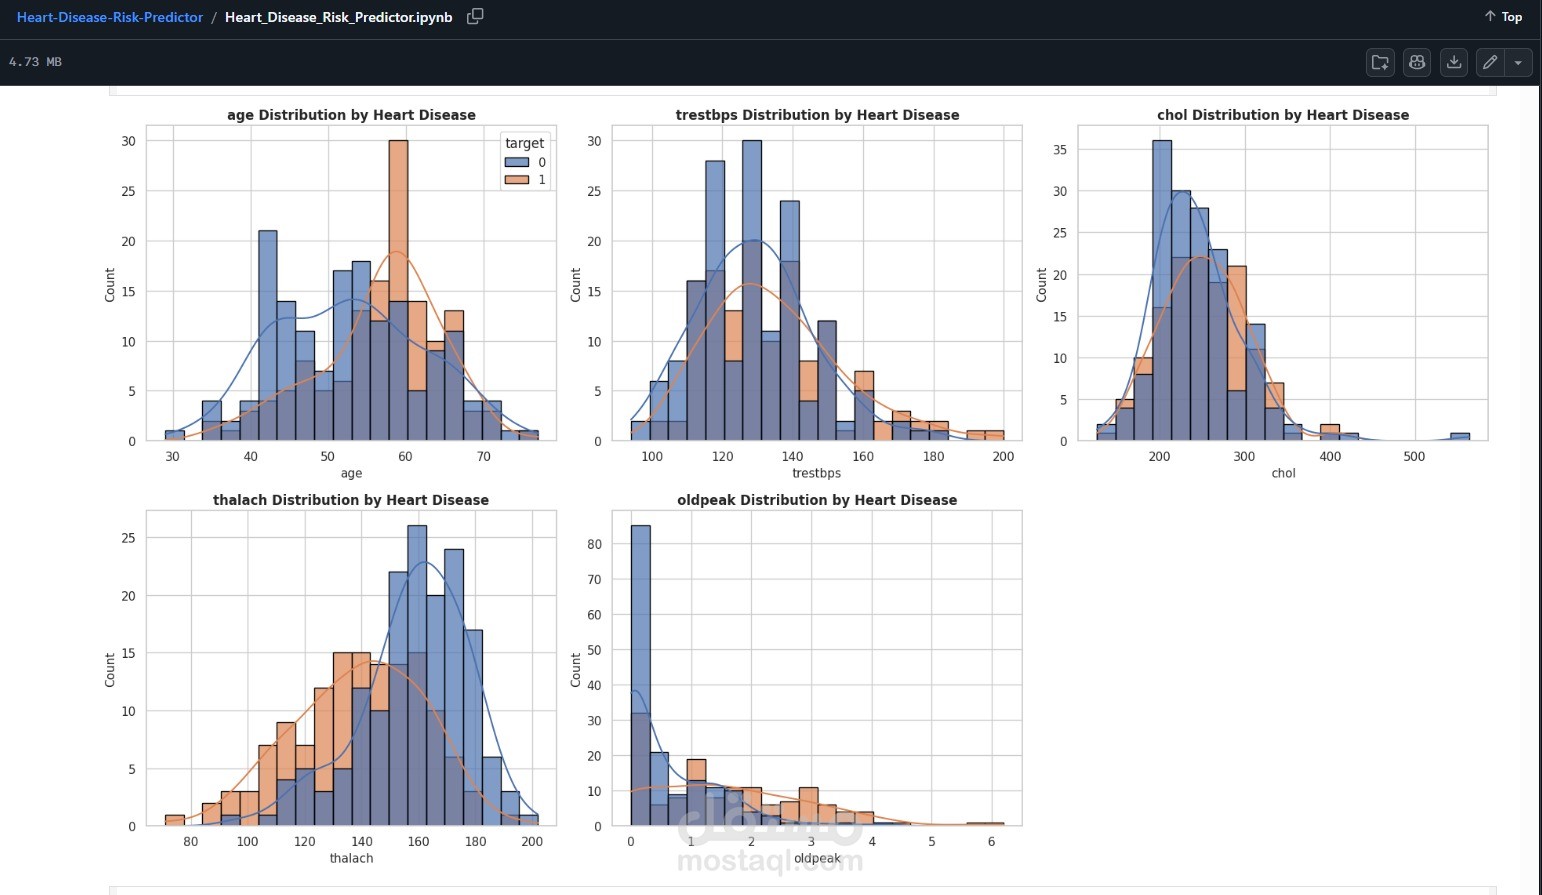
Developed an end-to-end Machine Learning solution for predicting heart disease risk using clinical data from the Cleveland Heart Disease dataset.
The project includes exploratory data analysis, statistical hypothesis testing, feature engineering, and custom Scikit-learn transformers designed to prevent data leakage. I trained and compared four tree-based classification models, applied 5-fold Stratified Cross-Validation and hyperparameter optimization using RandomizedSearchCV, and selected the best-performing model based on evaluation results.
The final Random Forest model achieved approximately 0.93 ROC-AUC on the held-out test set. I also used SHAP to interpret model predictions and identify influential features.
Finally, I integrated the trained pipeline into an interactive Streamlit web application that generates predictions and estimated probabilities from user-provided clinical inputs.