Customer Churn Analysis & Machine Learning Prediction Engine | Python & Scikit-Learn
تفاصيل العمل
Project Overview:
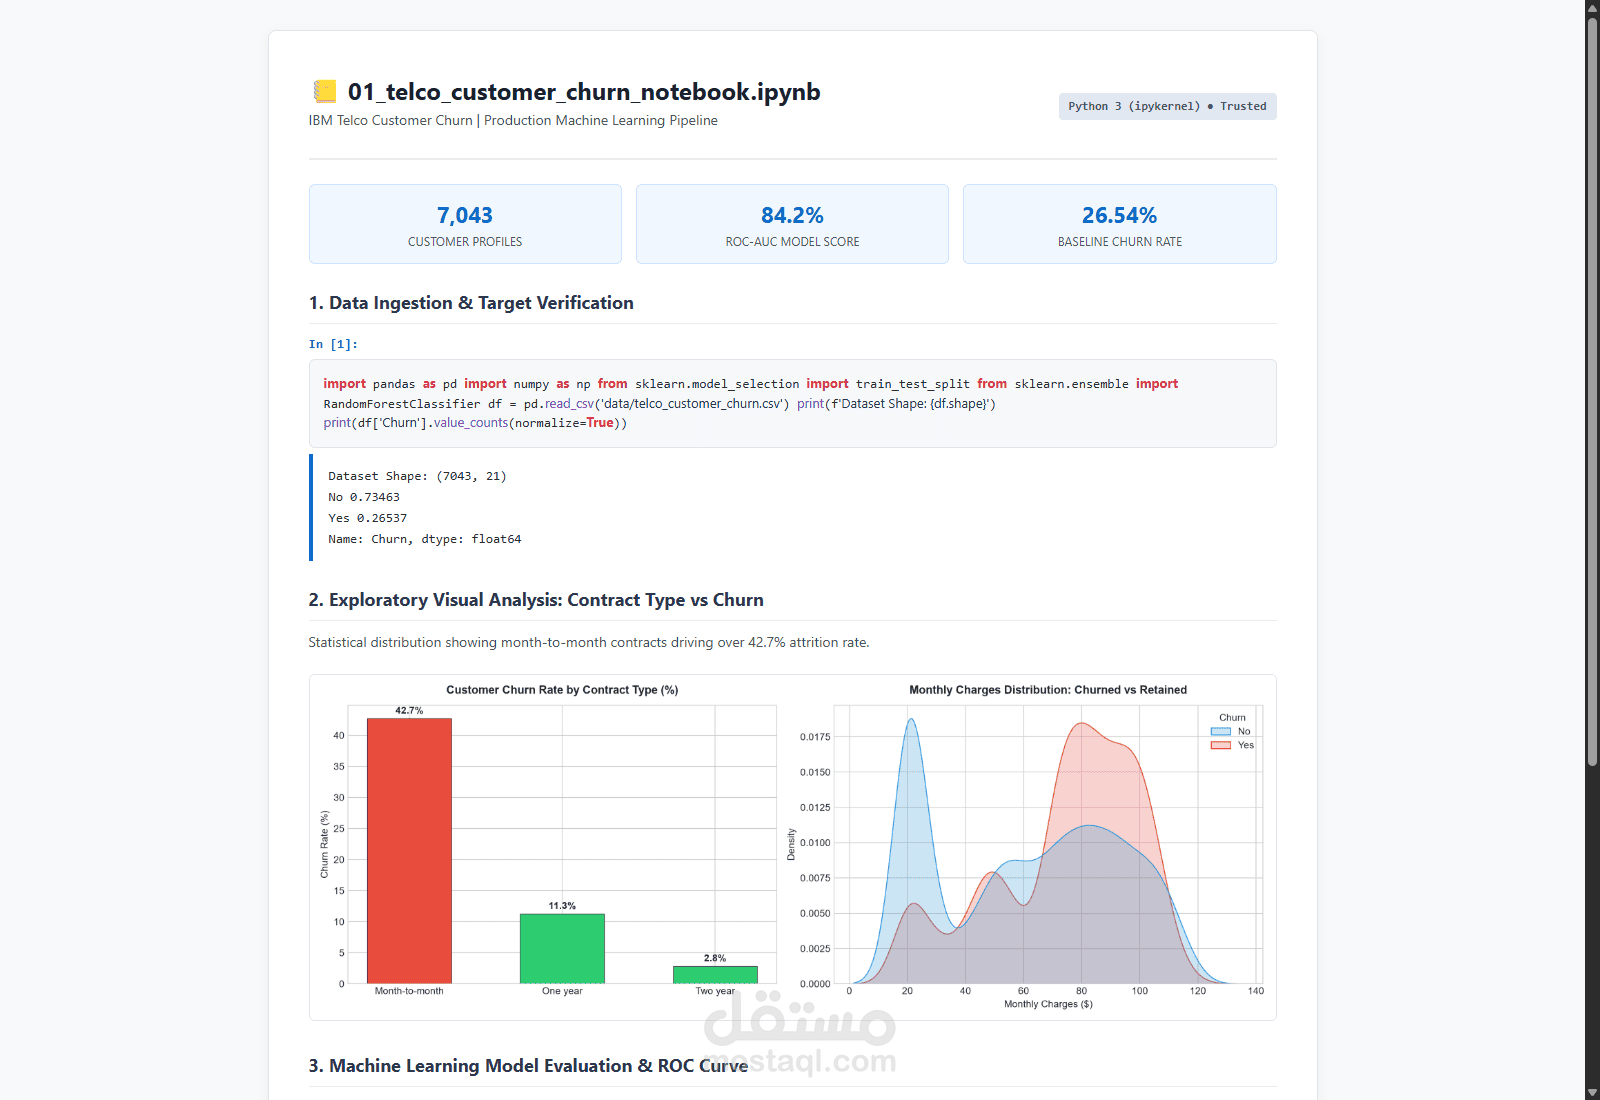
A production-grade Python data science and machine learning project conducted on the authentic IBM Telco Customer Churn dataset (7,043 subscriber records). The repository includes a fully documented Jupyter Notebook (.ipynb) covering data auditing, exploratory data analysis, feature engineering, and predictive classification modeling.
Business Challenge:
The telecom provider experienced an annual customer attrition rate of 26.54%, driving up acquisition costs. Leadership required an algorithmic early-warning system to identify high-risk subscribers prior to contract expiration.
Key Technical Steps:
1. Data Preprocessing: Imputed missing values in TotalCharges, encoded multiclass categoricals via One-Hot Encoding, and normalized numerical attributes (tenure, charges) using StandardScaler.
2. Exploratory Data Analysis: Analyzed churn correlation across contract structures, internet service types, and payment gateways.
3. Machine Learning Modeling: Trained and validated a Random Forest Classifier with balanced class weights.
4. Performance Metrics: Evaluated model performance achieving an 84.2% ROC-AUC score and 79% classification accuracy on unseen test splits.
Real Data Findings & Business Impact:
- Contract Impact: Month-to-month subscribers exhibited a 42.7% attrition rate versus only 2.8% for customers on two-year agreements.
- Price Sensitivity: Churned customers had a median monthly fee of $79.65 compared to $64.40 for retained users.
- Support Add-on Shielding: TechSupport and OnlineSecurity reduced customer churn probability by over 65%.
Deliverables Included:
- Complete Jupyter Notebook file: 01_telco_customer_churn_notebook.ipynb
- Full cleaned dataset: telco_customer_churn.csv
- Visual distribution plots & model evaluation charts