Anime Web Scraper (MyAnimeList)
تفاصيل العمل
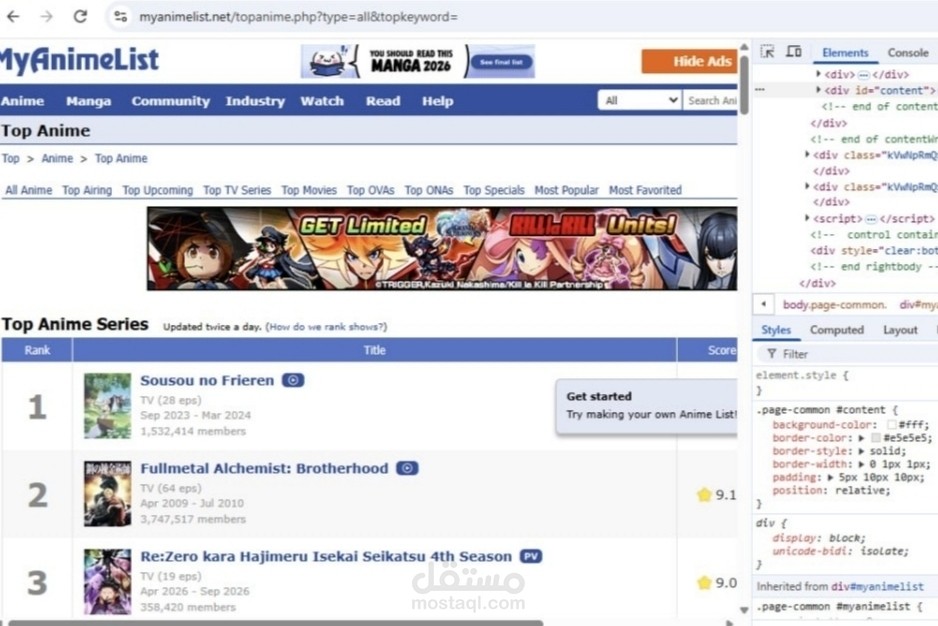
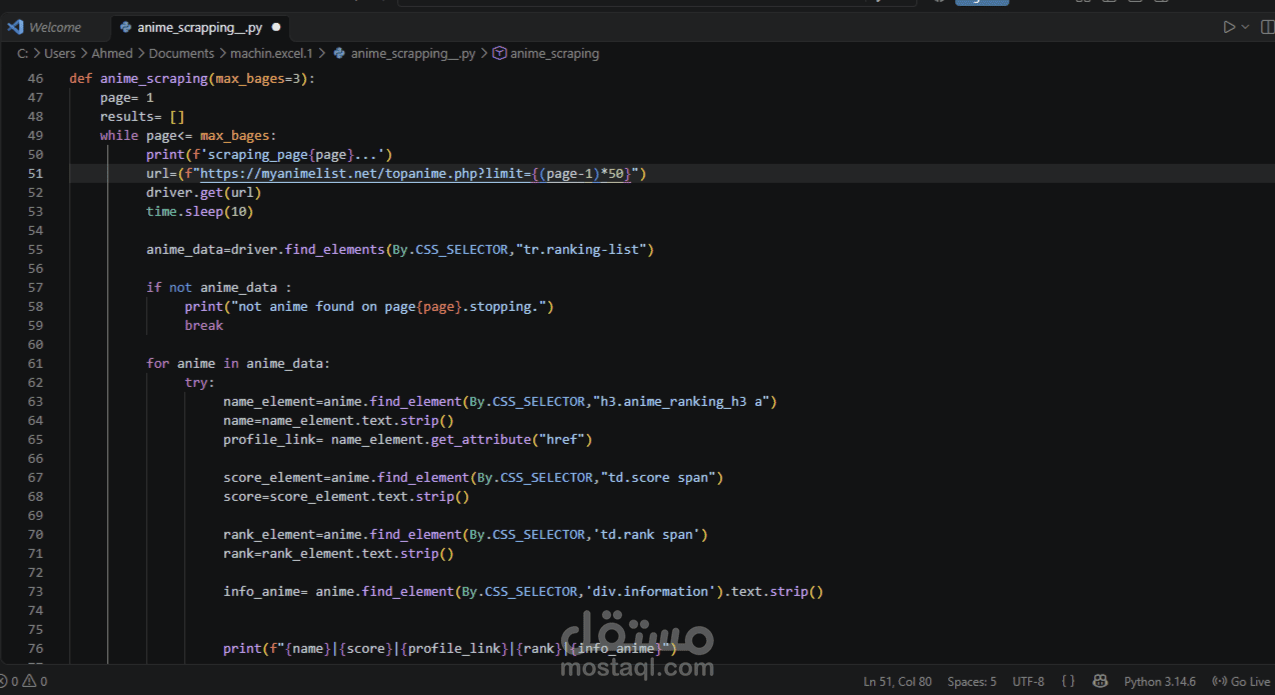
A Python-based web scraper built with Selenium to collect structured data on top-rated anime from MyAnimeList. The scraper navigates MyAnimeList's "Top Anime" listing pages and extracts the title, score, rank, and general info (type, episode count, airing dates, and member count) for each entry. It then visits each anime's individual profile page to gather additional details: studio, genre(s), source material, age rating, airing status, and premiere season.
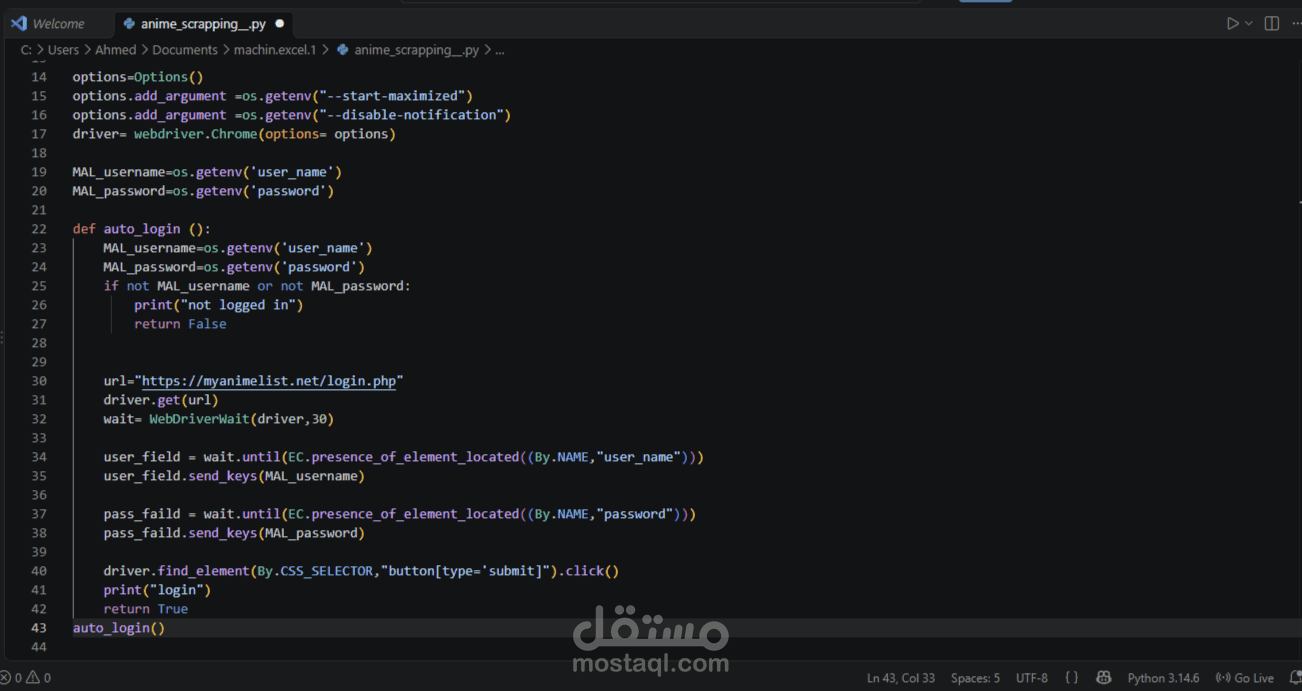
The script includes an optional login feature — if credentials are provided via environment variables, it logs into MyAnimeList before scraping; otherwise, it proceeds without authentication, since all the collected data is publicly accessible. Each extracted field is wrapped in its own error-handling block, so a missing element on any single page doesn't interrupt the overall scraping process. The final output is a structured CSV file ready for the next stage of the pipeline: cleaning and analysis with Pandas.