Emotional Speech Recognition Project
تفاصيل العمل
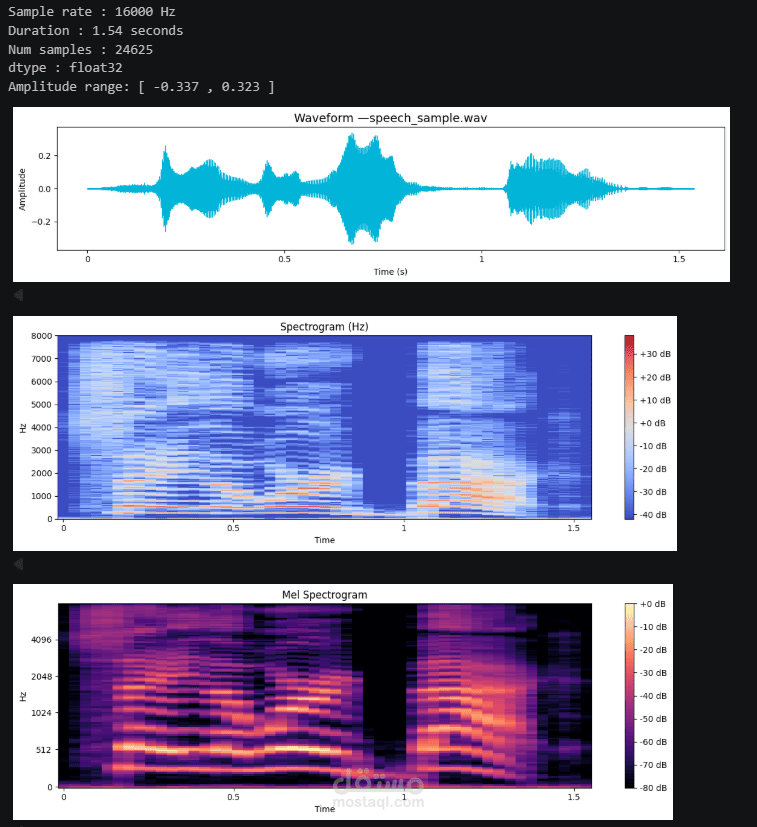
Project Title: AI System for Speaker Identification and Emotion Recognition from Voice
Project Description:
I need a Python-based system that takes an audio file (or a live recording) and determines two things:
Speaker identity (who is speaking).
Emotional state (happy, sad, angry, neutral, etc.).
Required Work:
Prepare and clean the audio data, then extract features (MFCC / Mel-spectrogram).
Train a deep learning model (CNN / LSTM / Wav2Vec2).
Evaluate accuracy (accuracy, F1-score).
Build a simple interface to upload audio and display the result with a confidence score.
Deliverables:
Full source code with documentation, the trained model, a working interface, and a results report.
Tools: Python, Librosa, PyTorch or TensorFlow, Streamlit or Flask.
If you need it shorter for a character limit, tell me and I’ll trim it.