heart disease prediction
تفاصيل العمل
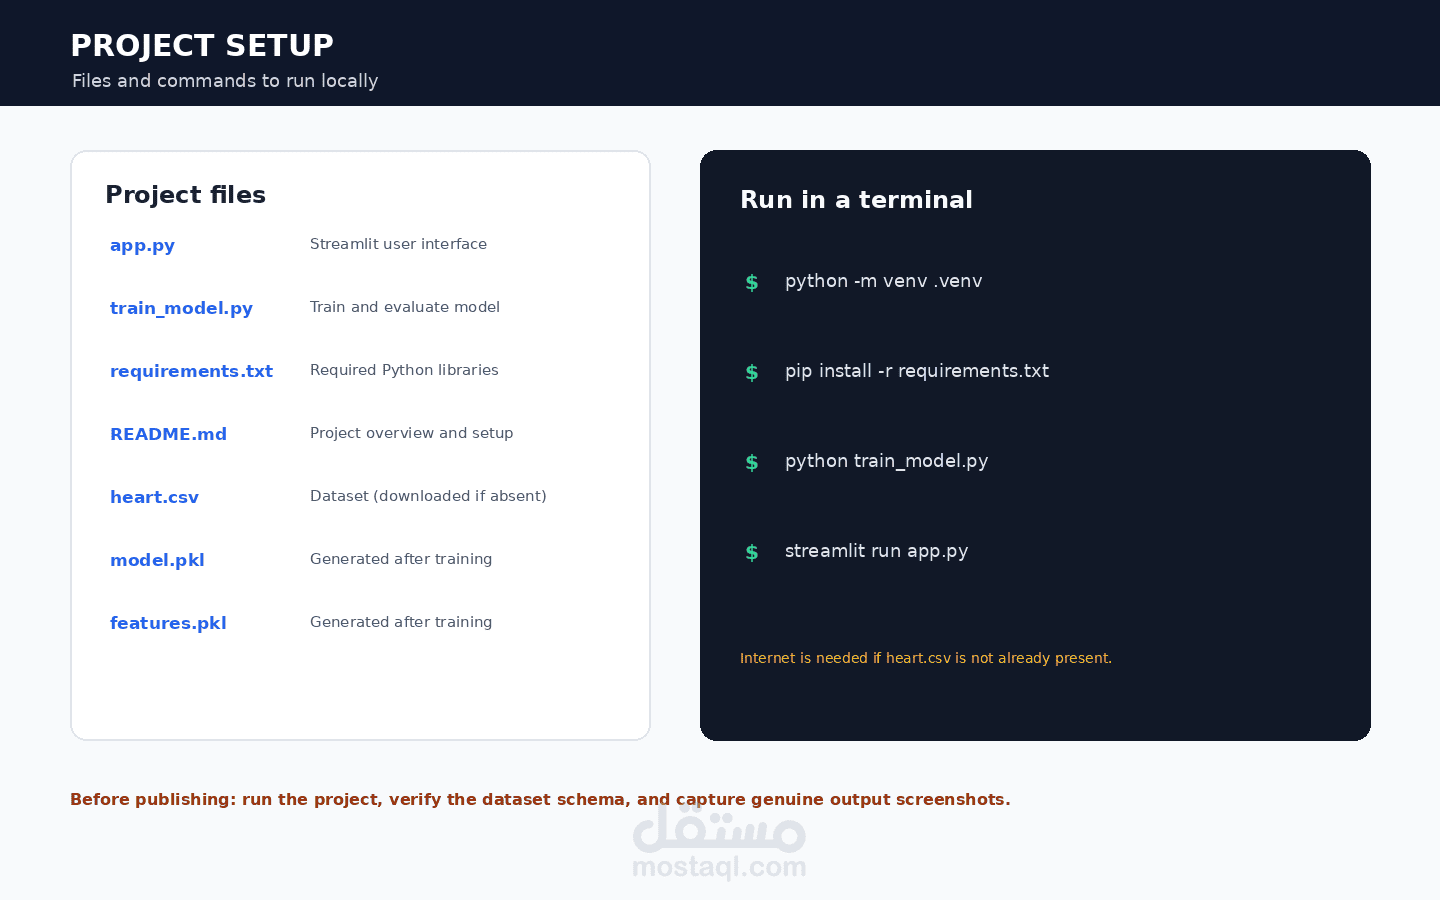
The project involves developing a machine learning model to predict the likelihood of heart disease using patient health data. The process includes collecting and preprocessing the dataset, handling missing values, exploring relevant medical features, and training classification algorithms such as Logistic Regression, Decision Trees, and Random Forest. The models are evaluated using metrics such as accuracy, precision, recall, and F1-score. Finally, the best-performing model can be integrated into a simple application to provide preliminary risk predictions and support healthcare professionals in clinical decision-making.