Industrial Text & Plate Recognition: Detection + OCR Pipeline
تفاصيل العمل
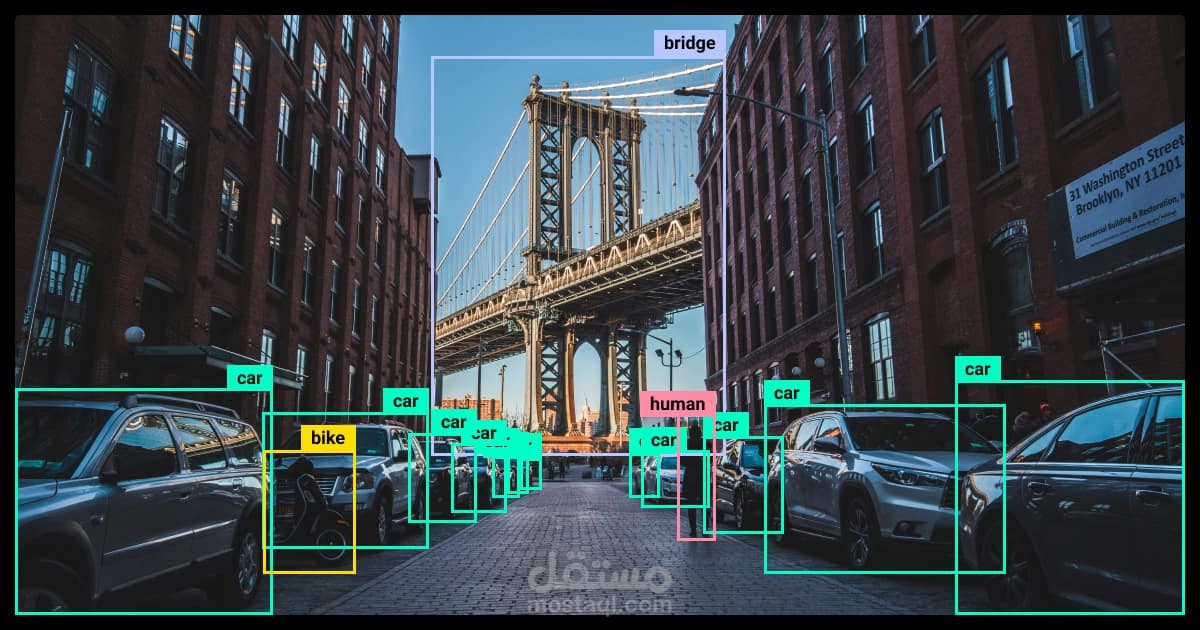
Contributed to an end-to-end pipeline that detects and reads alphanumeric identifiers from real-world images, built to handle skewed, low-quality, and inconsistent inputs.
The problem: Off-the-shelf OCR was unreliable on real images (~54% accuracy on the first baseline).
The approach:
• Trained a YOLOv8x detector to localize the target region (mAP50 of 0.87 on 4,600+ labeled images)
• Added deskewing to normalize rotated and tilted inputs
• Built a cascade fallback: when the primary OCR engine fails validation, the pipeline automatically retries with alternative engines and preprocessing
• Iterated through five versions, using error analysis at each step to target the biggest failure category
The result: OCR accuracy improved from ~54% to ~93% on the internal test set.
My role: Contributed to detection model training, OCR pipeline iterations, and evaluation/documentation, on multi-GPU infrastructure.
Skills tags: YOLOv8, OCR, OpenCV, PyTorch, Computer Vision, Python