AI-Based Space Image Caption Generator Using Swin Transformer and LSTM
تفاصيل العمل
**Project Overview**
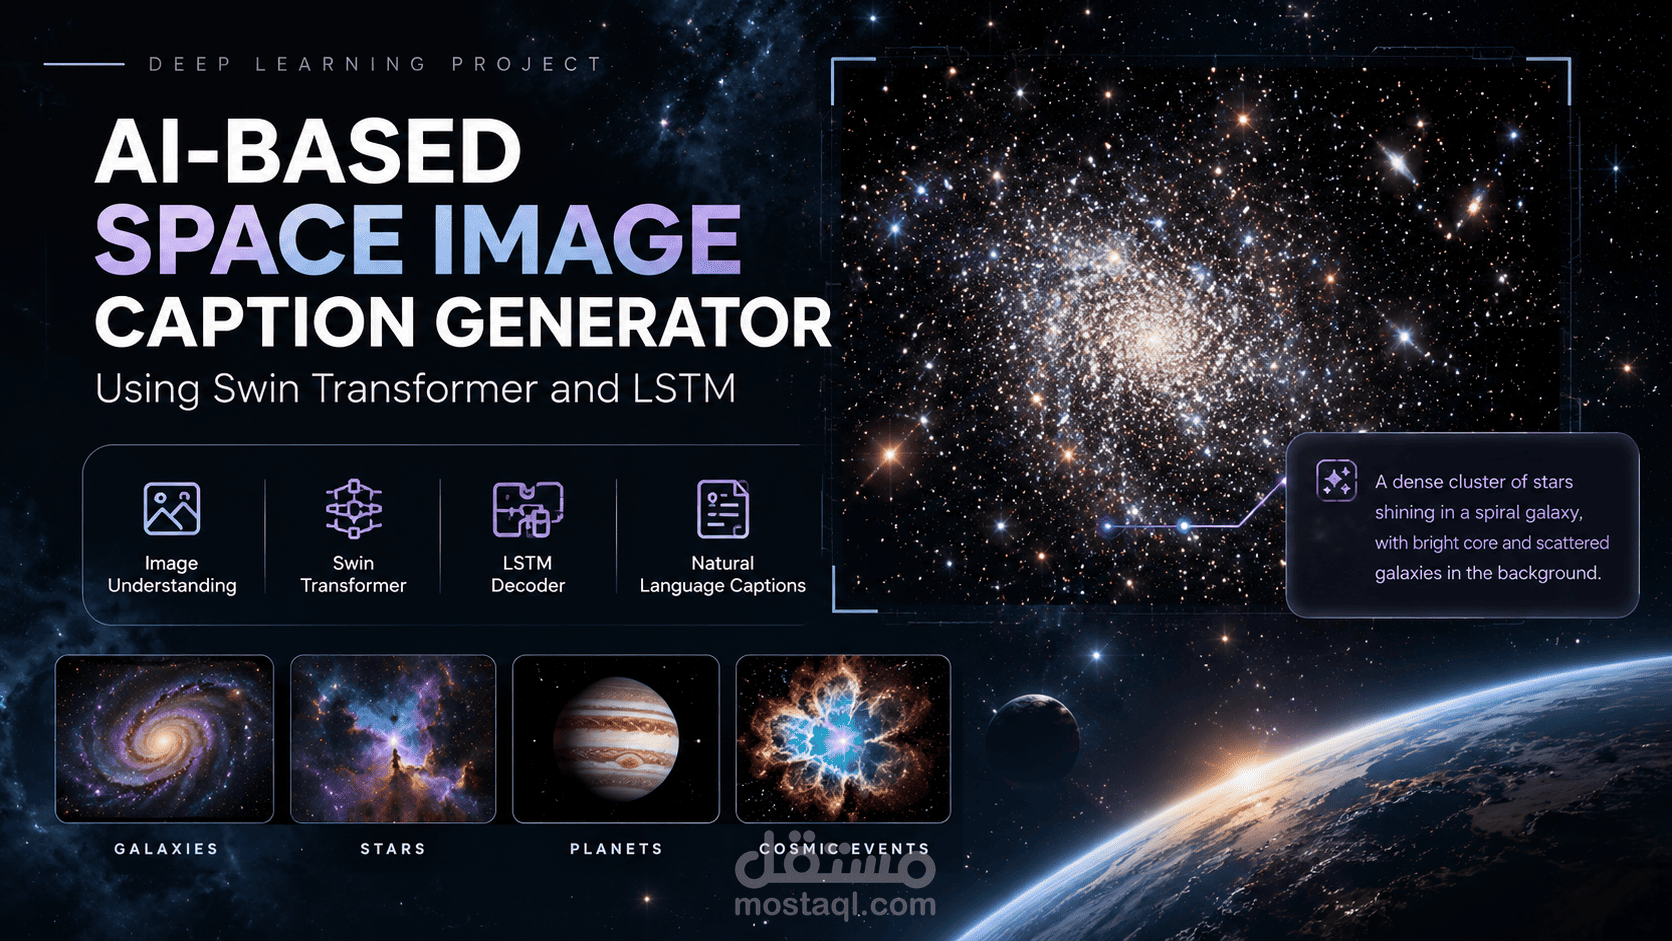
This project implements an AI-based image captioning system that generates textual descriptions for space images using deep learning and computer vision techniques.
**Key Features**
- **Swin Transformer Encoder:** Extracts visual features from input images using a pretrained vision model.
- **LSTM Decoder:** Generates text descriptions based on extracted image features.
- **Beam Search Decoding:** Explores multiple candidate word sequences to generate captions.
- **Smart Image Search:** Allows users to search the dataset by image title or keyword.
- **Image Caption Visualization:** Displays images alongside their generated descriptions.
- **BLEU Evaluation:** Implements BLEU scoring to compare generated captions with reference text.
- **Model Saving and Loading:** Saves and reloads the trained decoder weights.
**Technologies Used**
Python, PyTorch, TensorFlow Keras Tokenizer, Hugging Face Transformers, Swin Transformer, LSTM, Pandas, Matplotlib, PIL, and NLTK.
**Implementation**
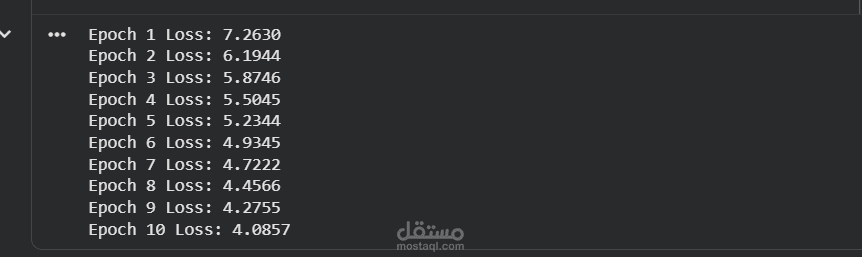
The system preprocesses image captions, tokenizes the text, extracts image features using a pretrained Swin Transformer, and trains an LSTM decoder to generate descriptions. It also provides an interactive search interface for finding images and generating captions.
This project demonstrates practical applications of deep learning, computer vision, and natural language generation.