Arabic Text Preprocessing and Tokenization Using SANAD Dataset
تفاصيل العمل
**Project Overview**
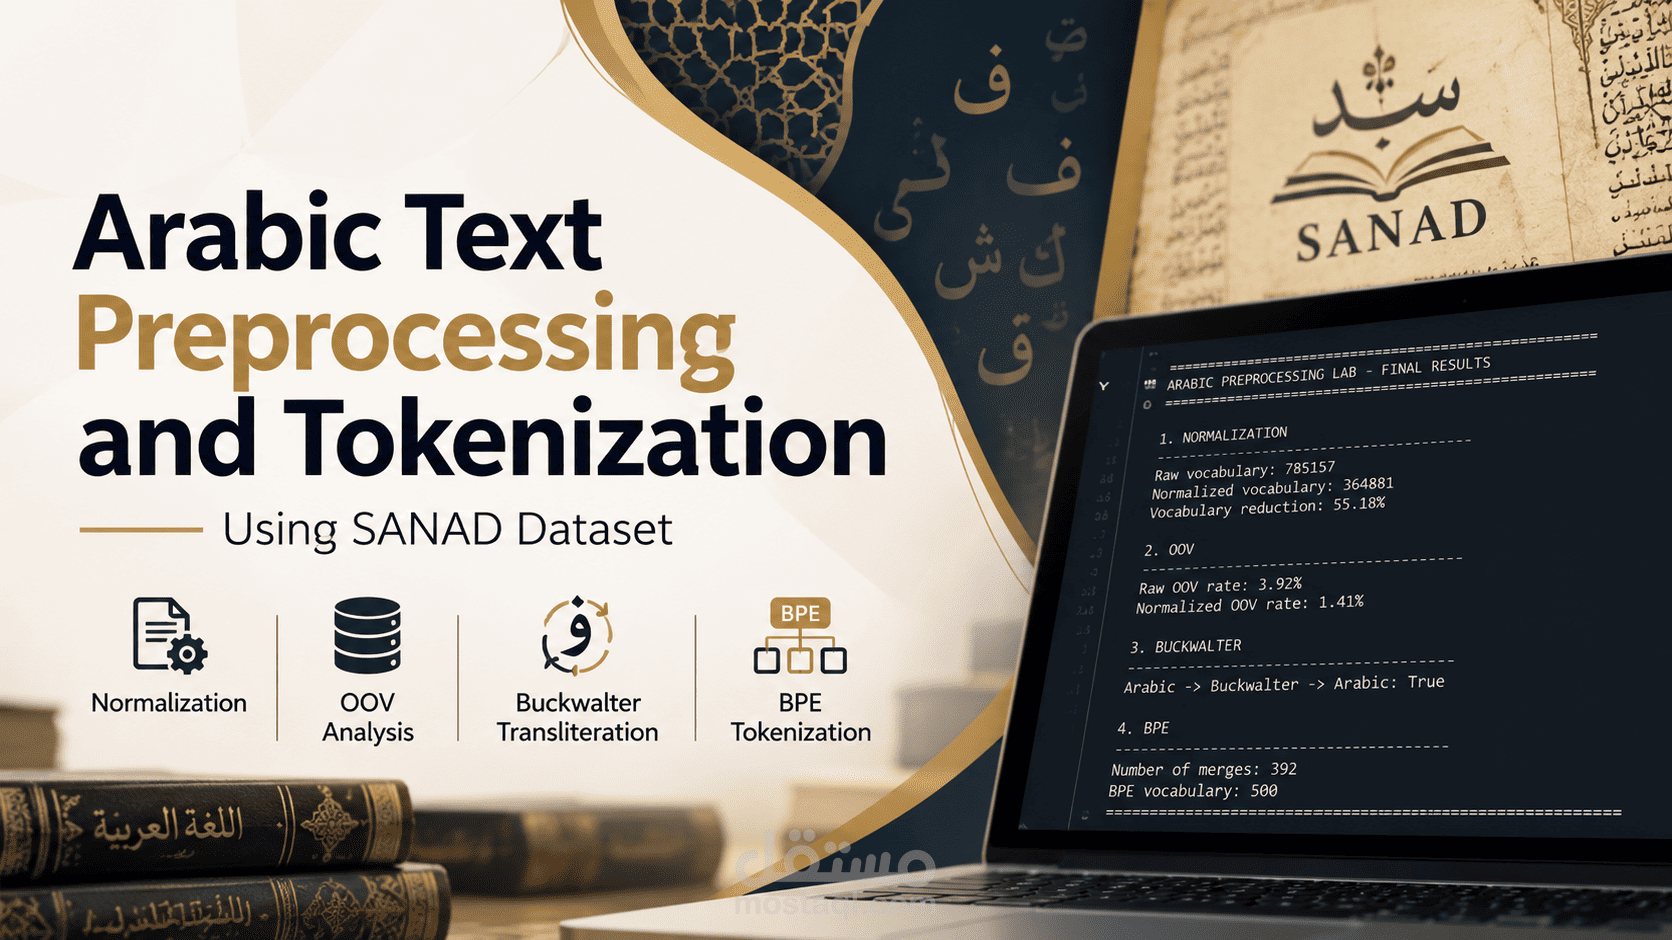
This project focuses on Arabic text preprocessing and tokenization using the SANAD dataset, which contains 45,500 Arabic text documents.
**Key Features**
- **Arabic Text Normalization:** Removed diacritics, standardized Arabic characters, and cleaned text to reduce vocabulary variations.
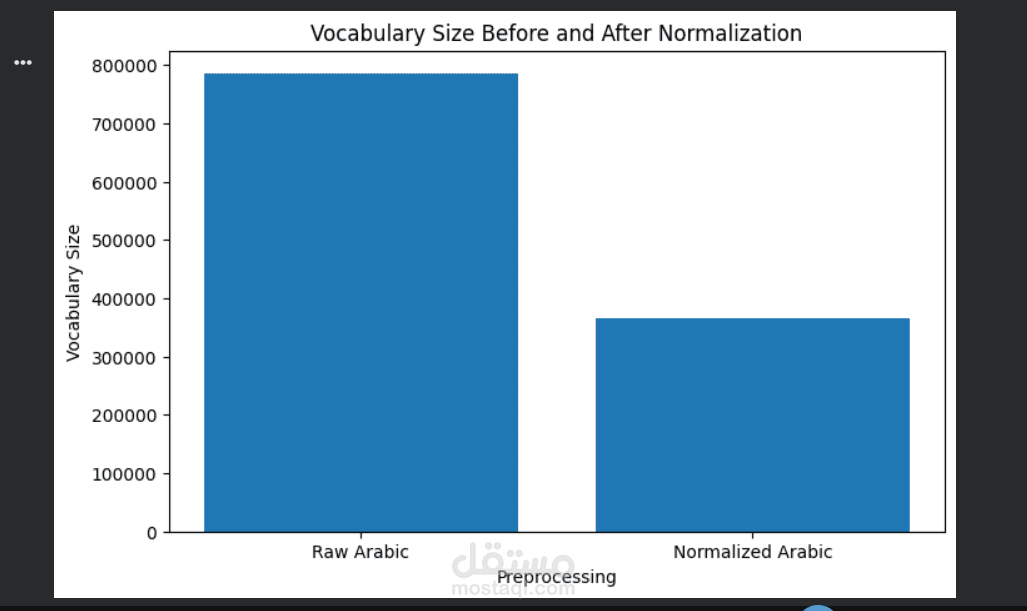
- **Vocabulary Analysis:** Compared vocabulary size before and after normalization.
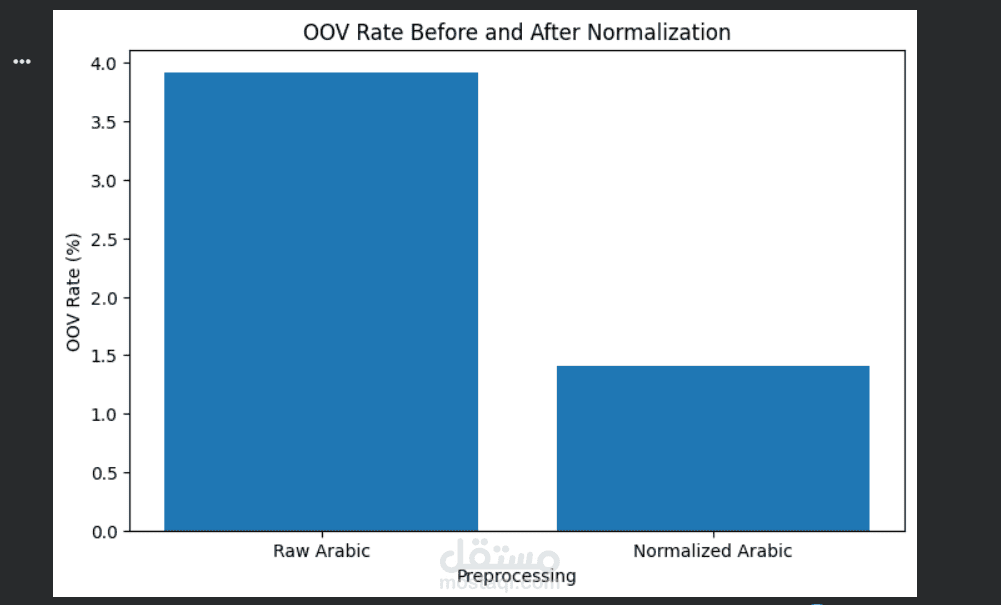
- **Out-of-Vocabulary (OOV) Analysis:** Measured the OOV rate using an 80/20 training and testing split.
- **Buckwalter Encoding and Decoding:** Implemented Arabic-to-Buckwalter conversion and reverse decoding.
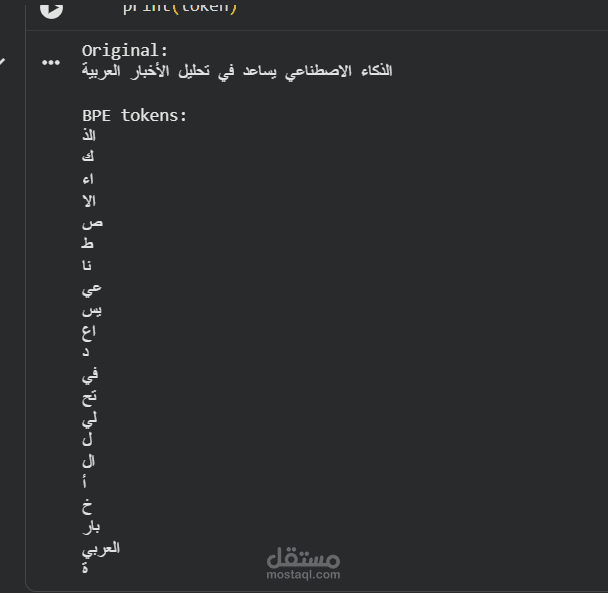
- **BPE Tokenizer:** Built a Byte Pair Encoding tokenizer from scratch to learn subword units from Arabic text.
- **Results Visualization:** Created charts to compare vocabulary size and OOV rates before and after normalization.
- **Results Export:** Saved the analysis results and learned BPE merges to files.
**Technologies Used**
Python, Pandas, Matplotlib, Regular Expressions, Counter, and Pathlib.
**Results**
- Reduced vocabulary size by 55.18% after normalization.
- Reduced the measured OOV rate from 3.92% to 1.41%.
- Built a BPE vocabulary containing 500 symbols with 392 merge operations.
- Successfully tested Arabic-to-Buckwalter conversion and reverse decoding.
This project demonstrates practical skills in Arabic Natural Language Processing (NLP), text preprocessing, vocabulary analysis, and subword tokenization.