Healthcare Stroke Data Analysis & Visualization Using Python
تفاصيل العمل
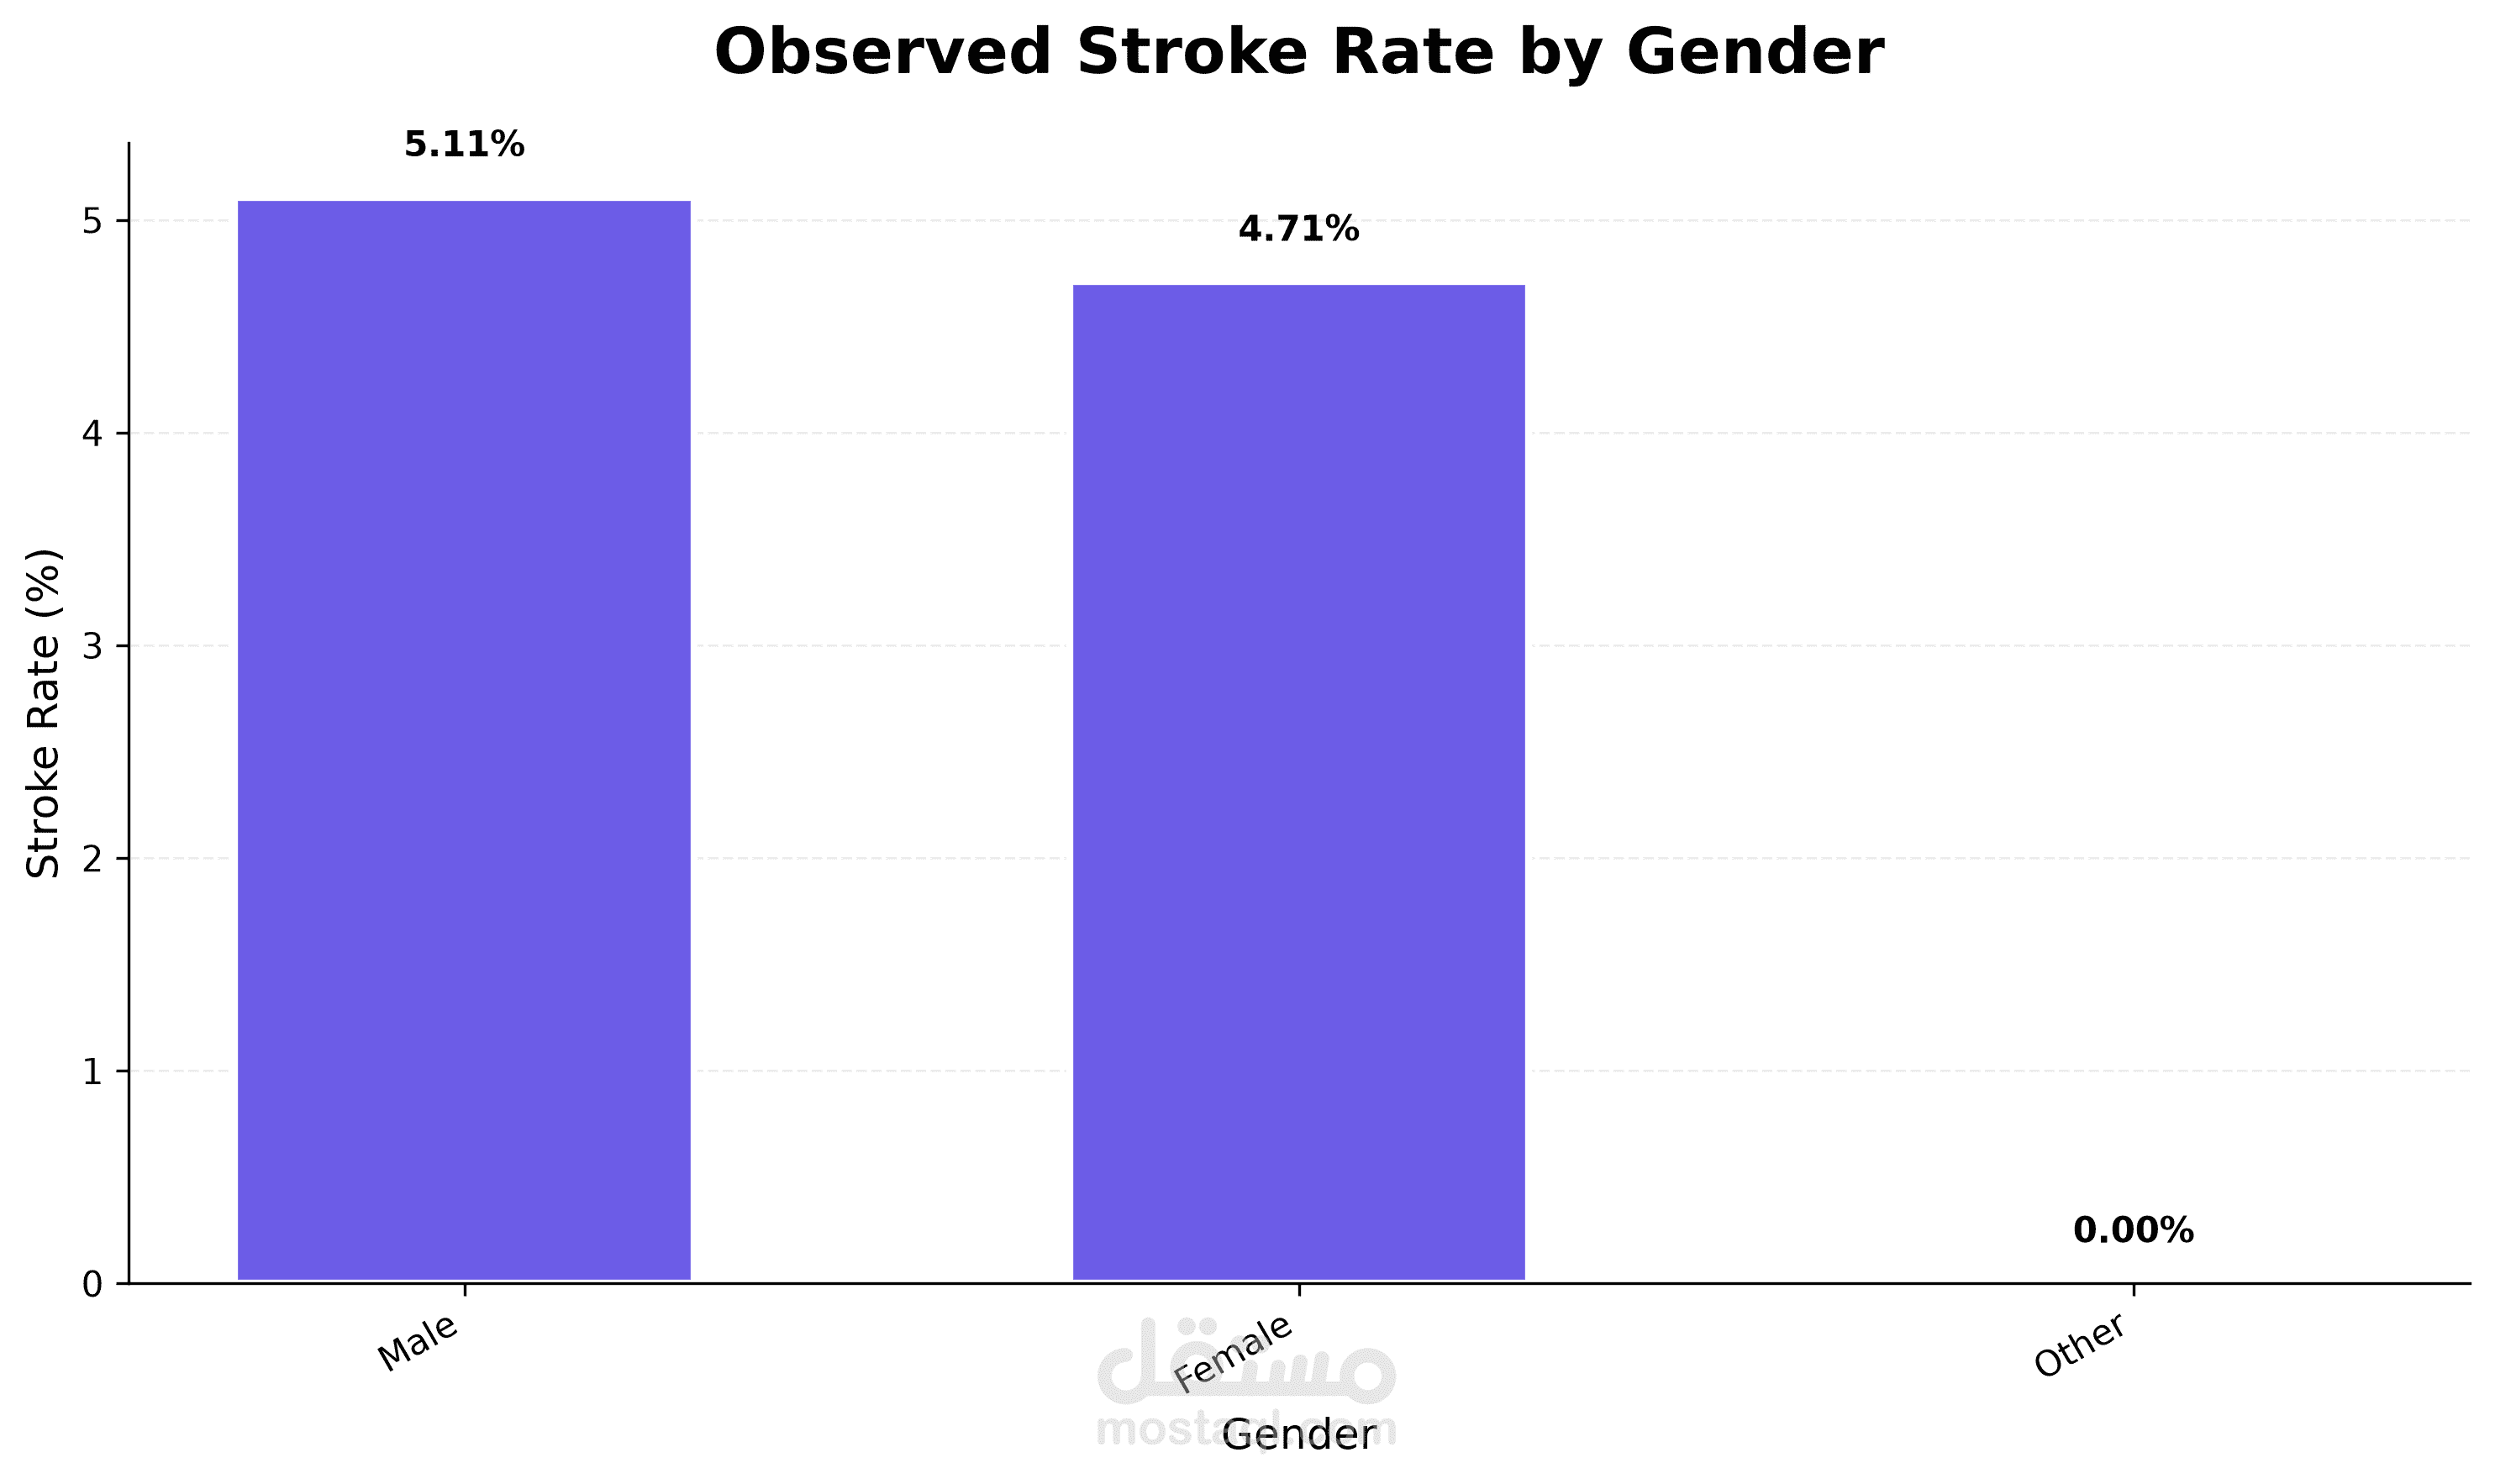
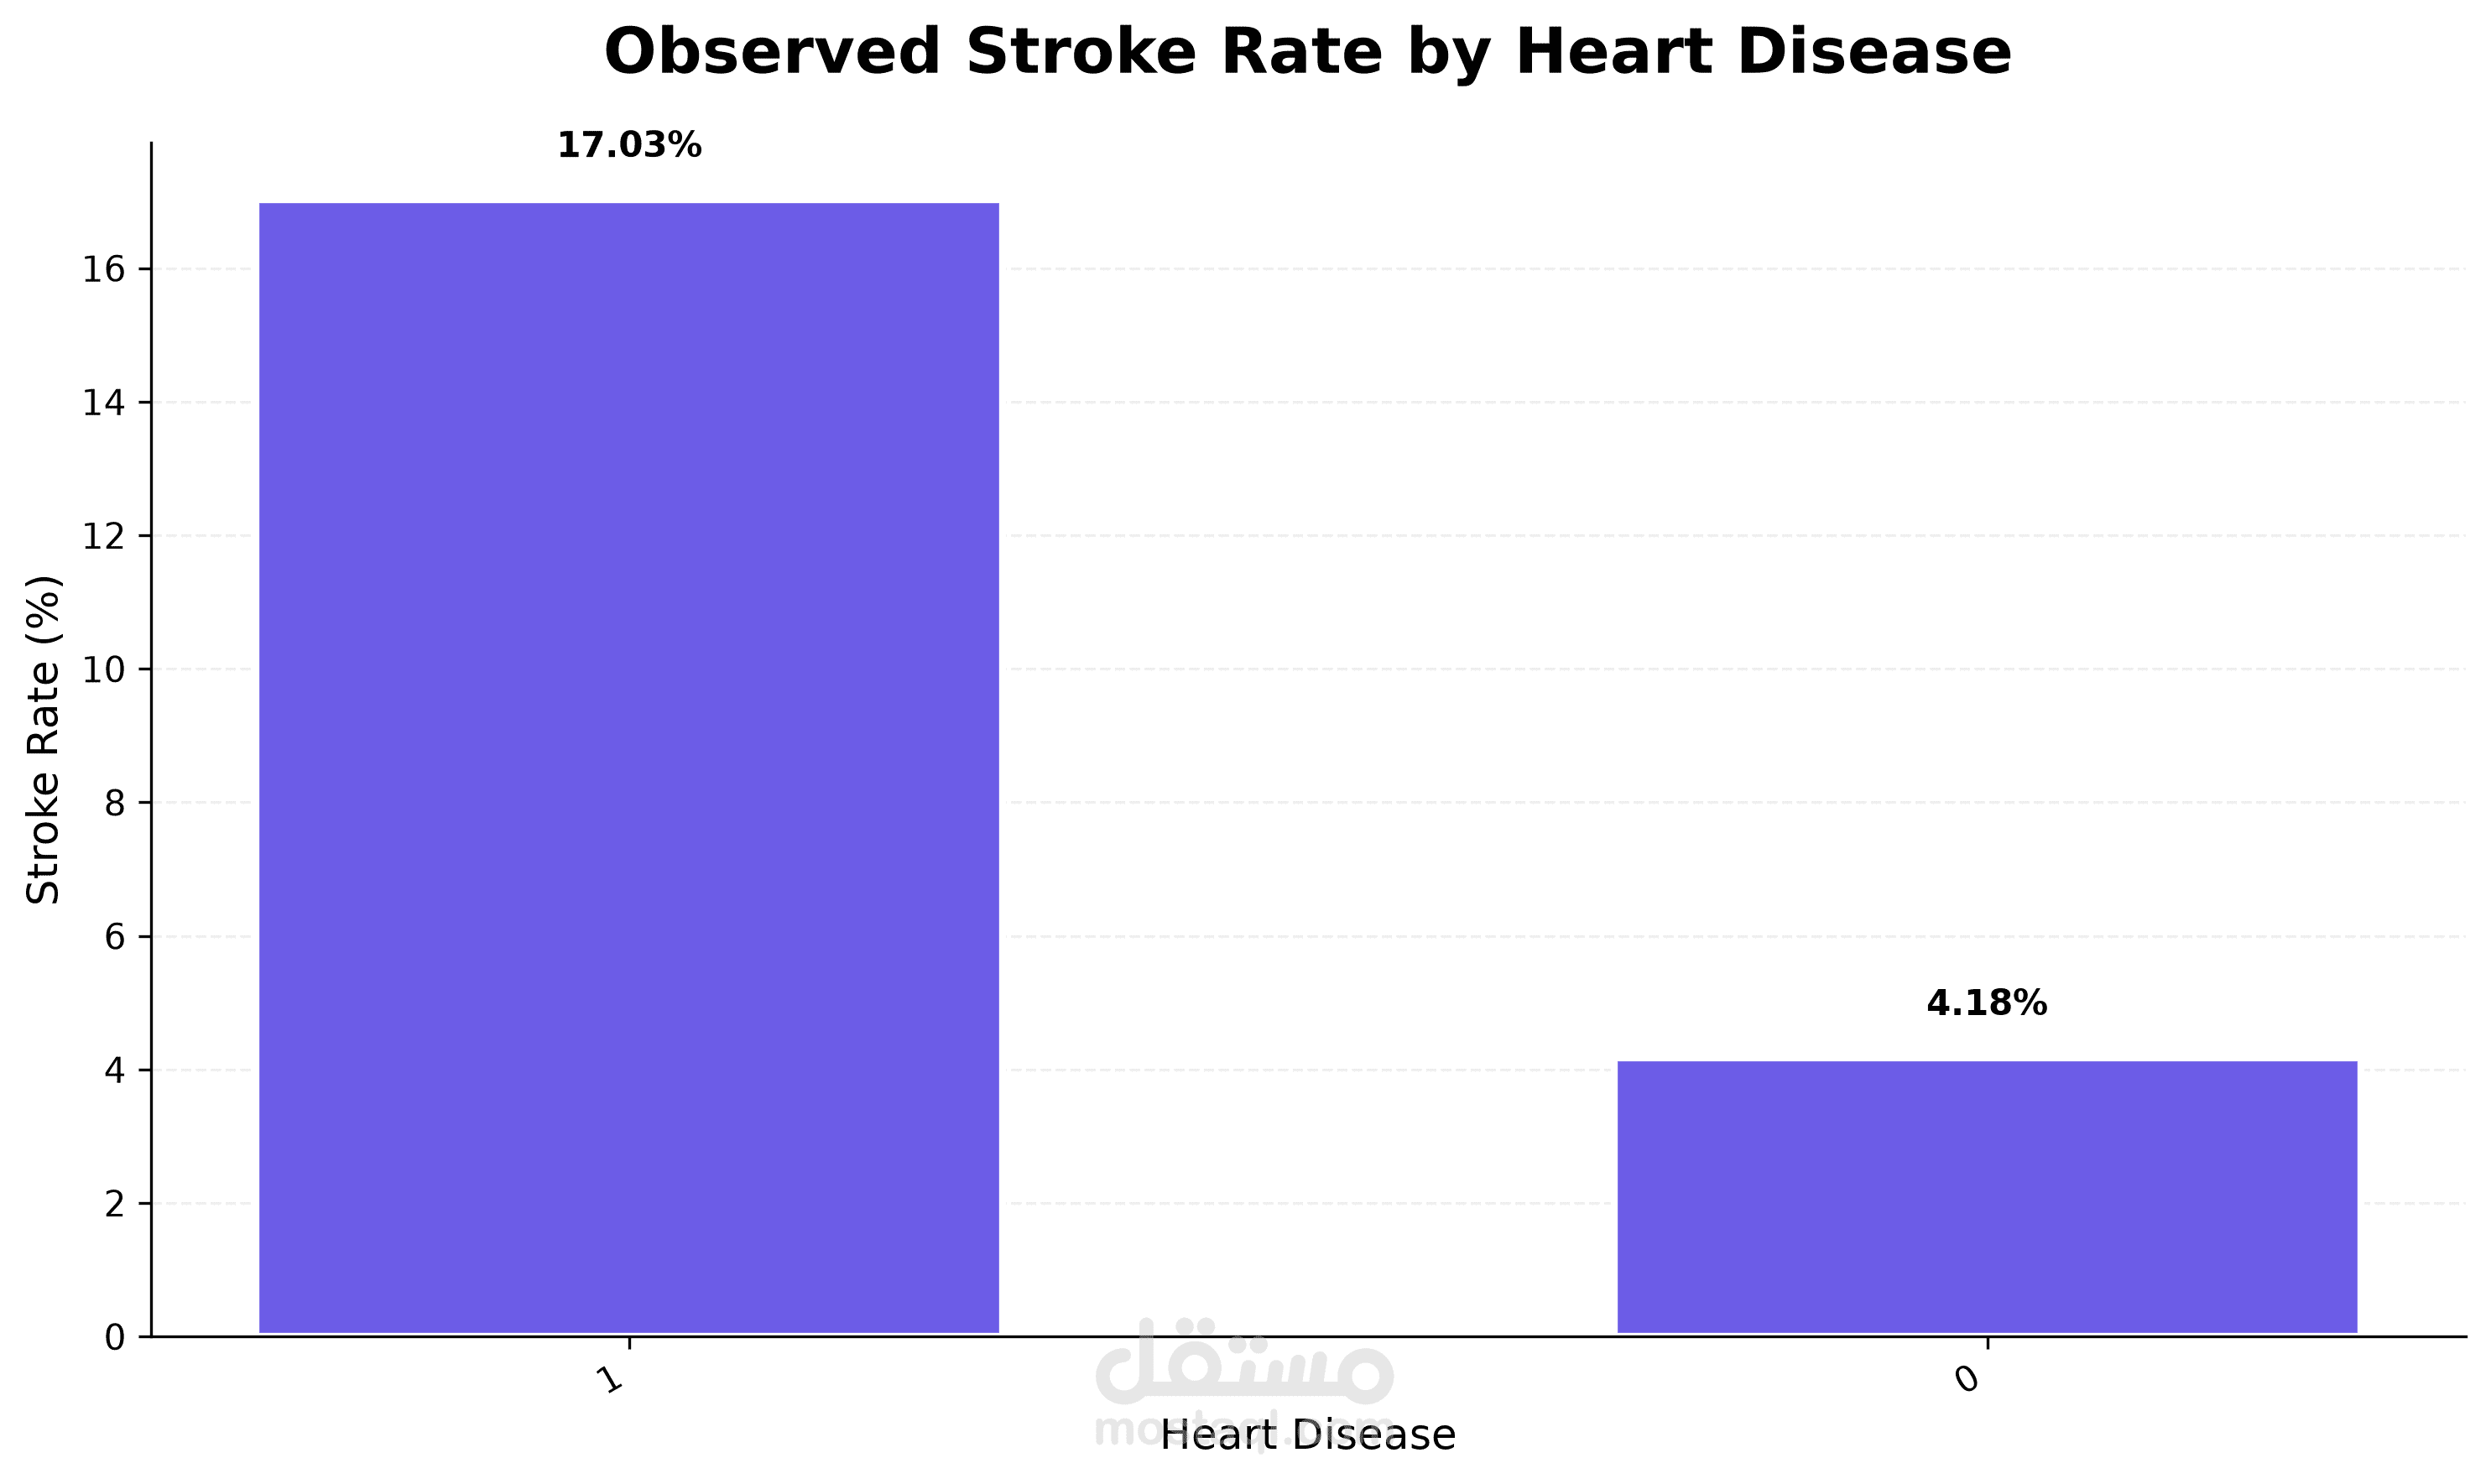
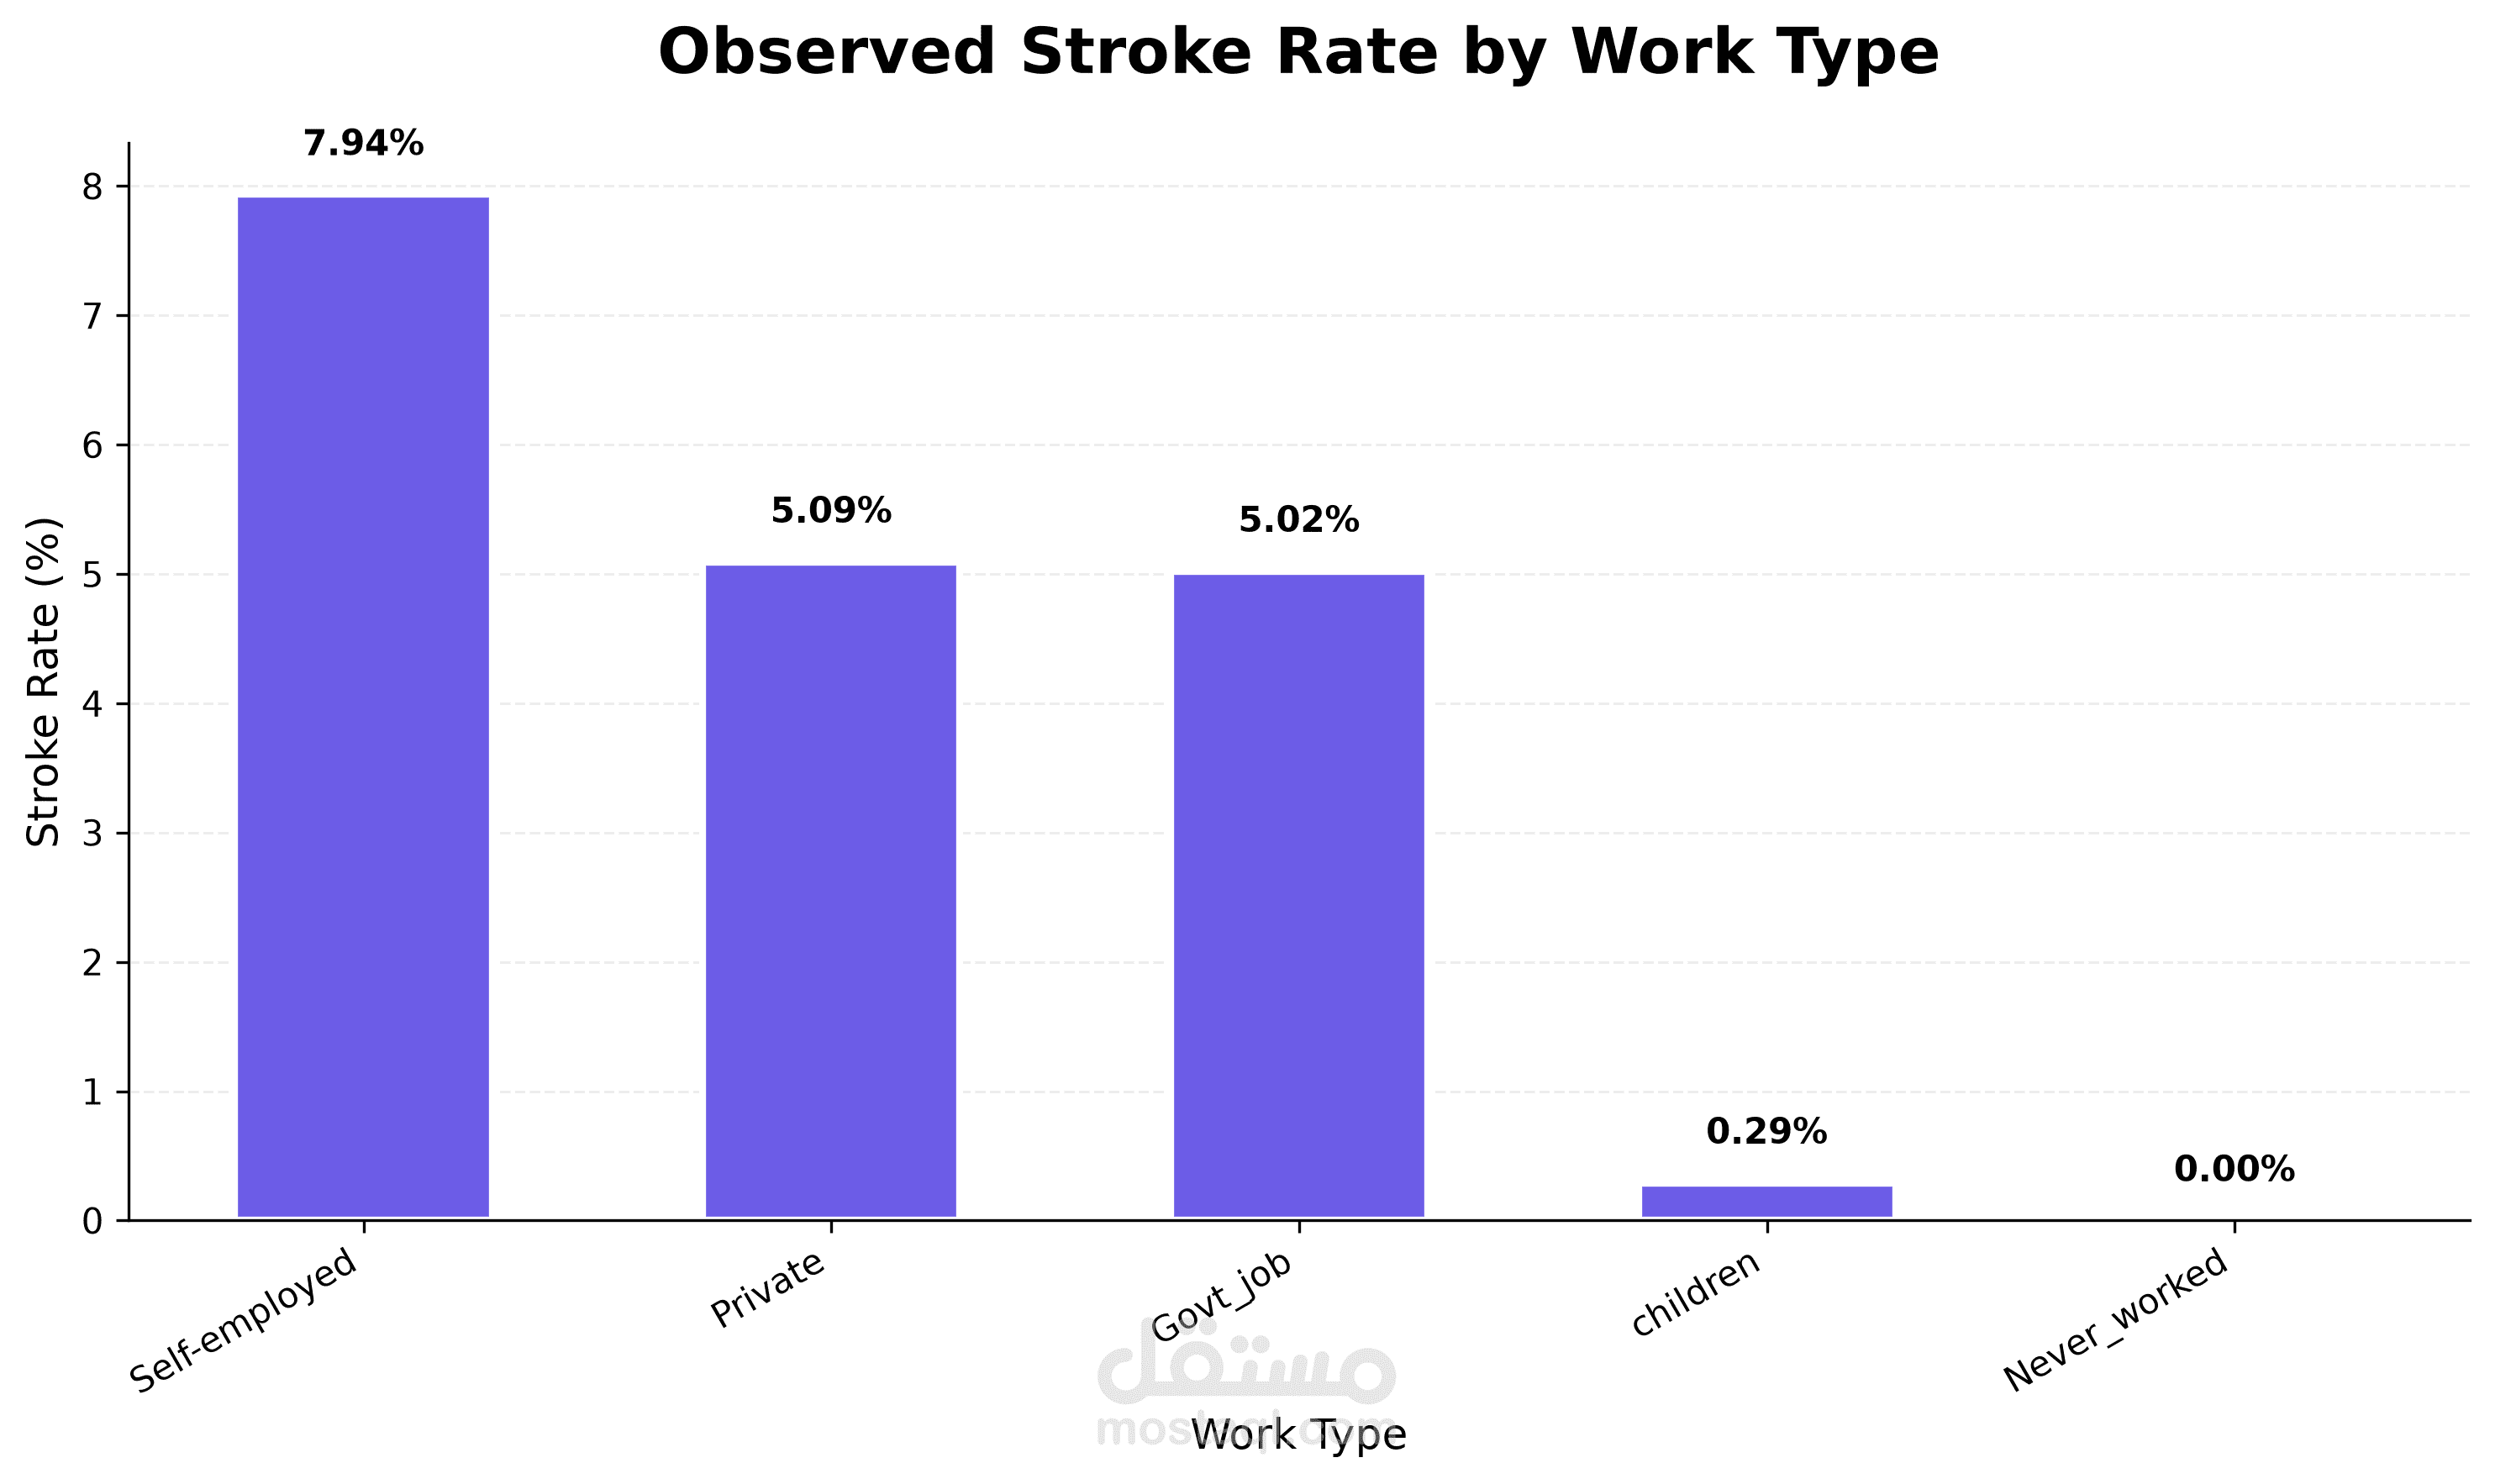
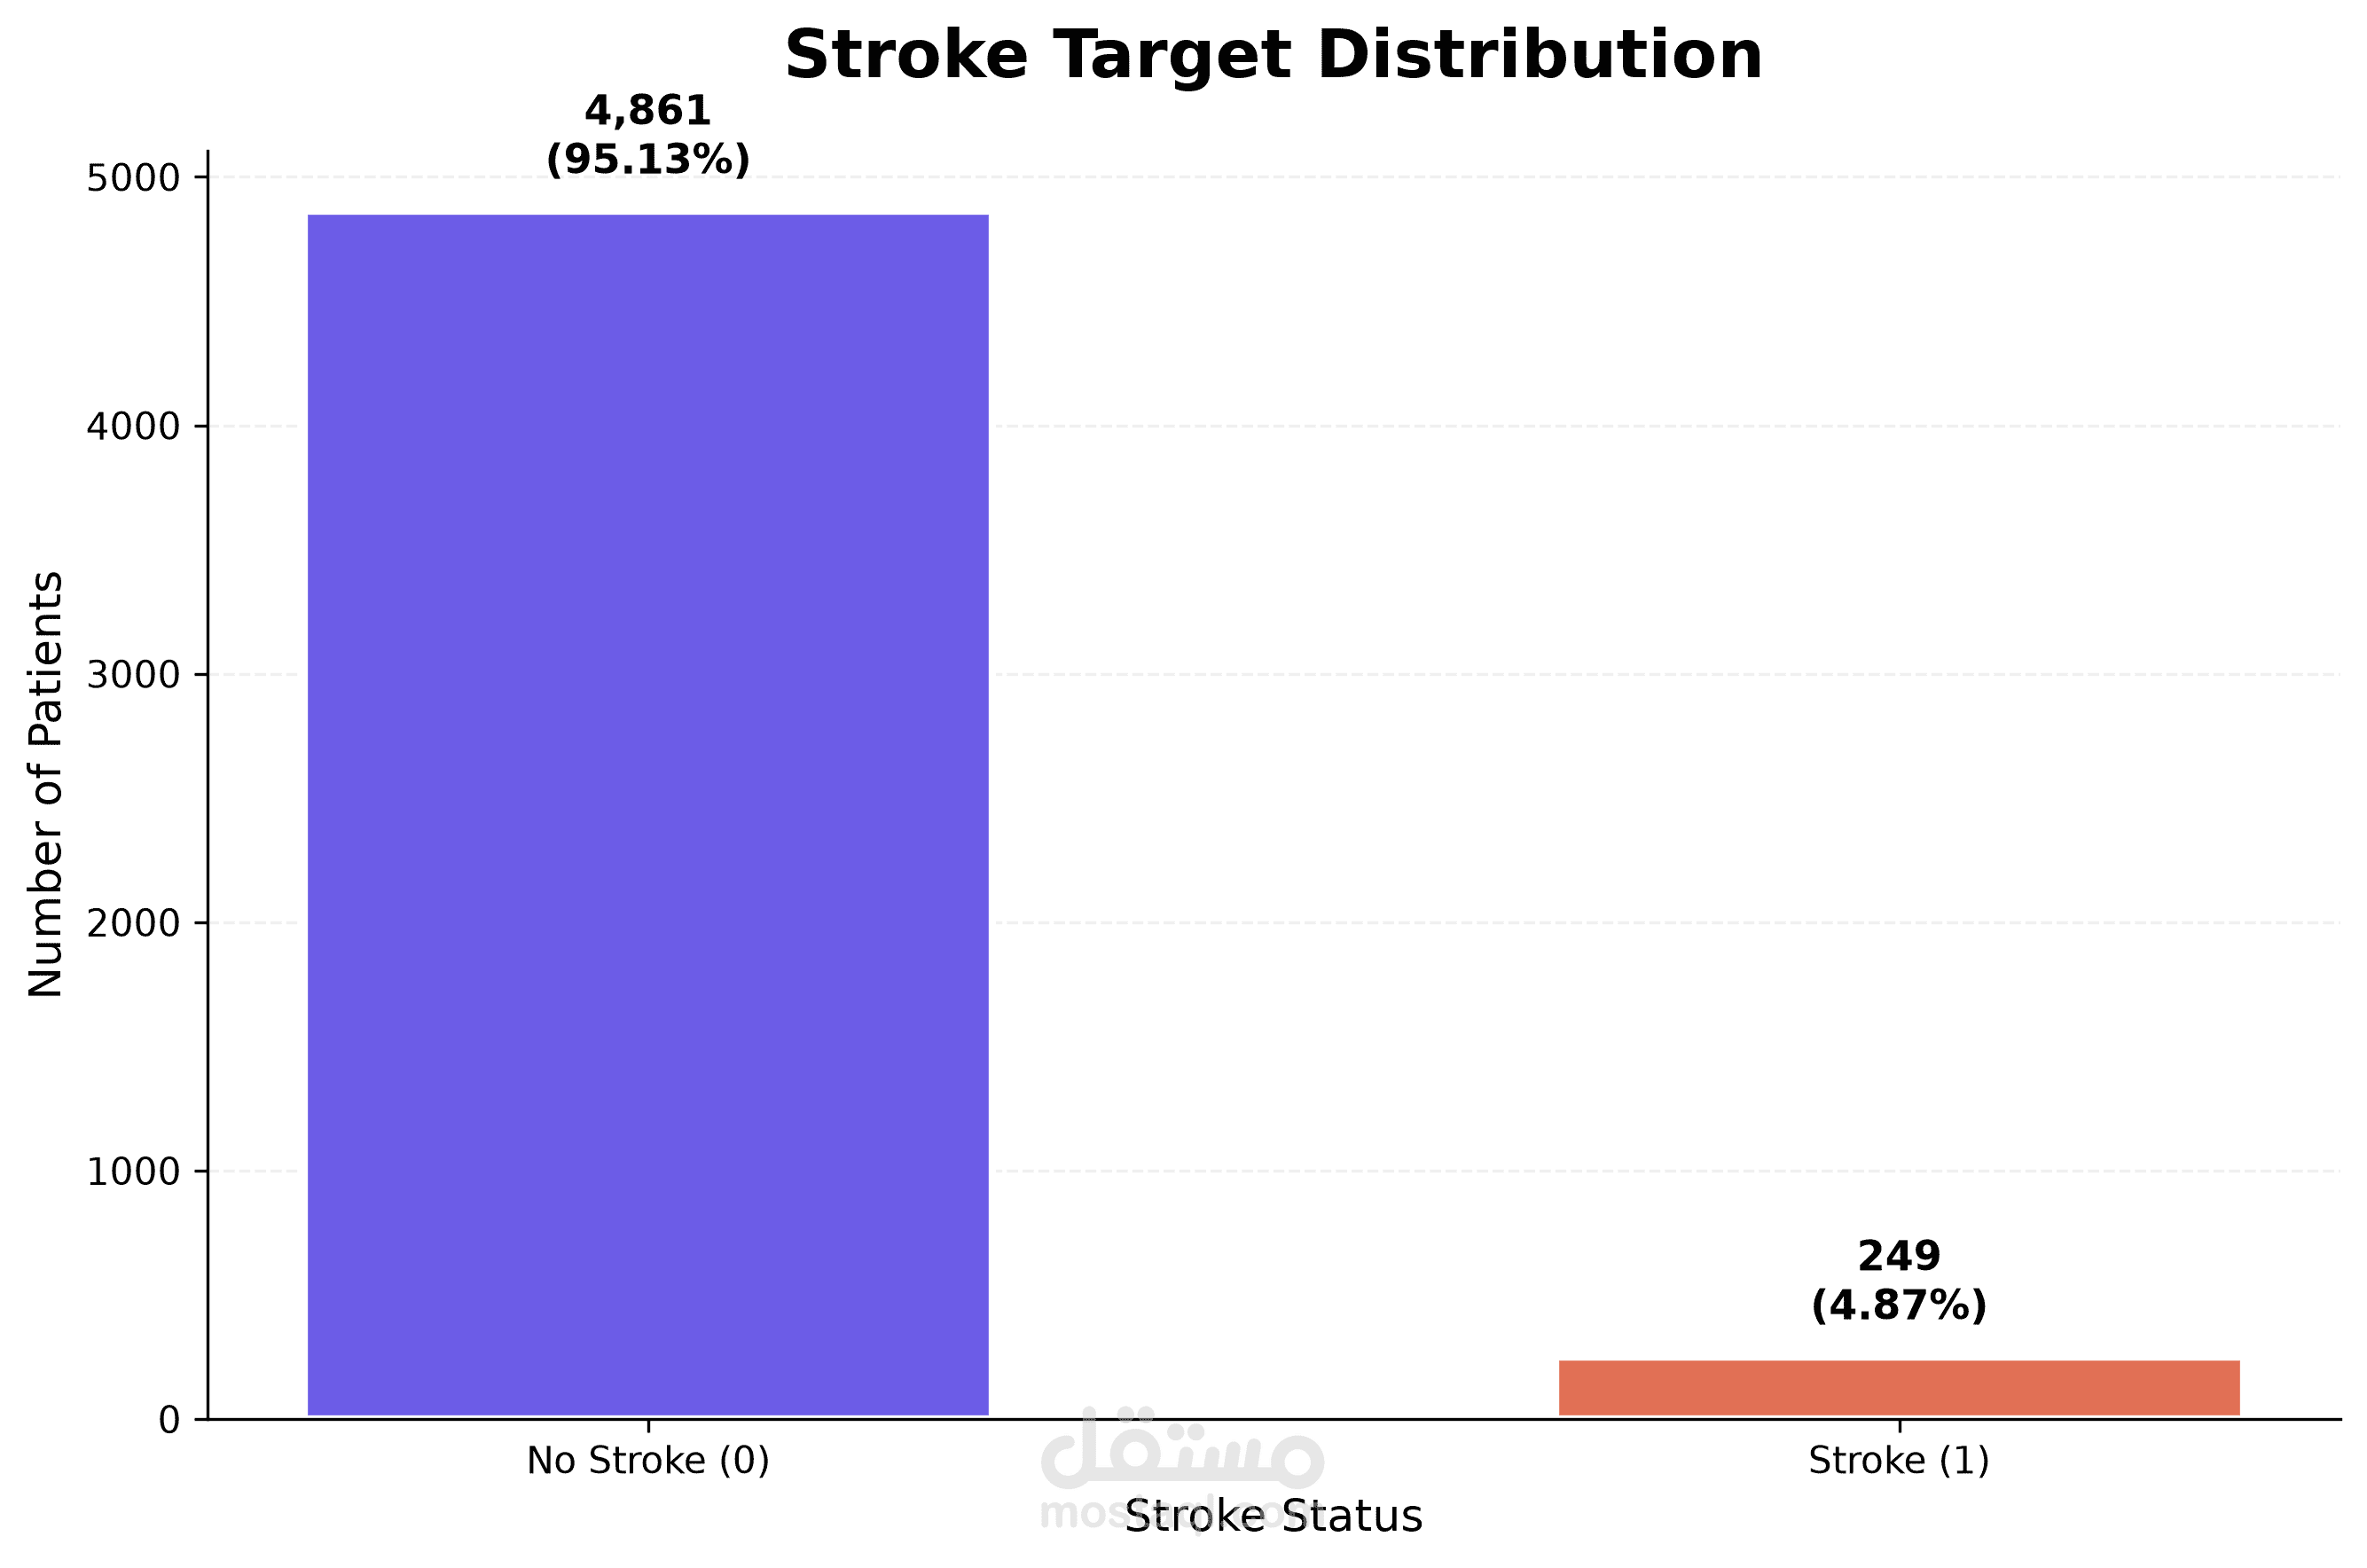
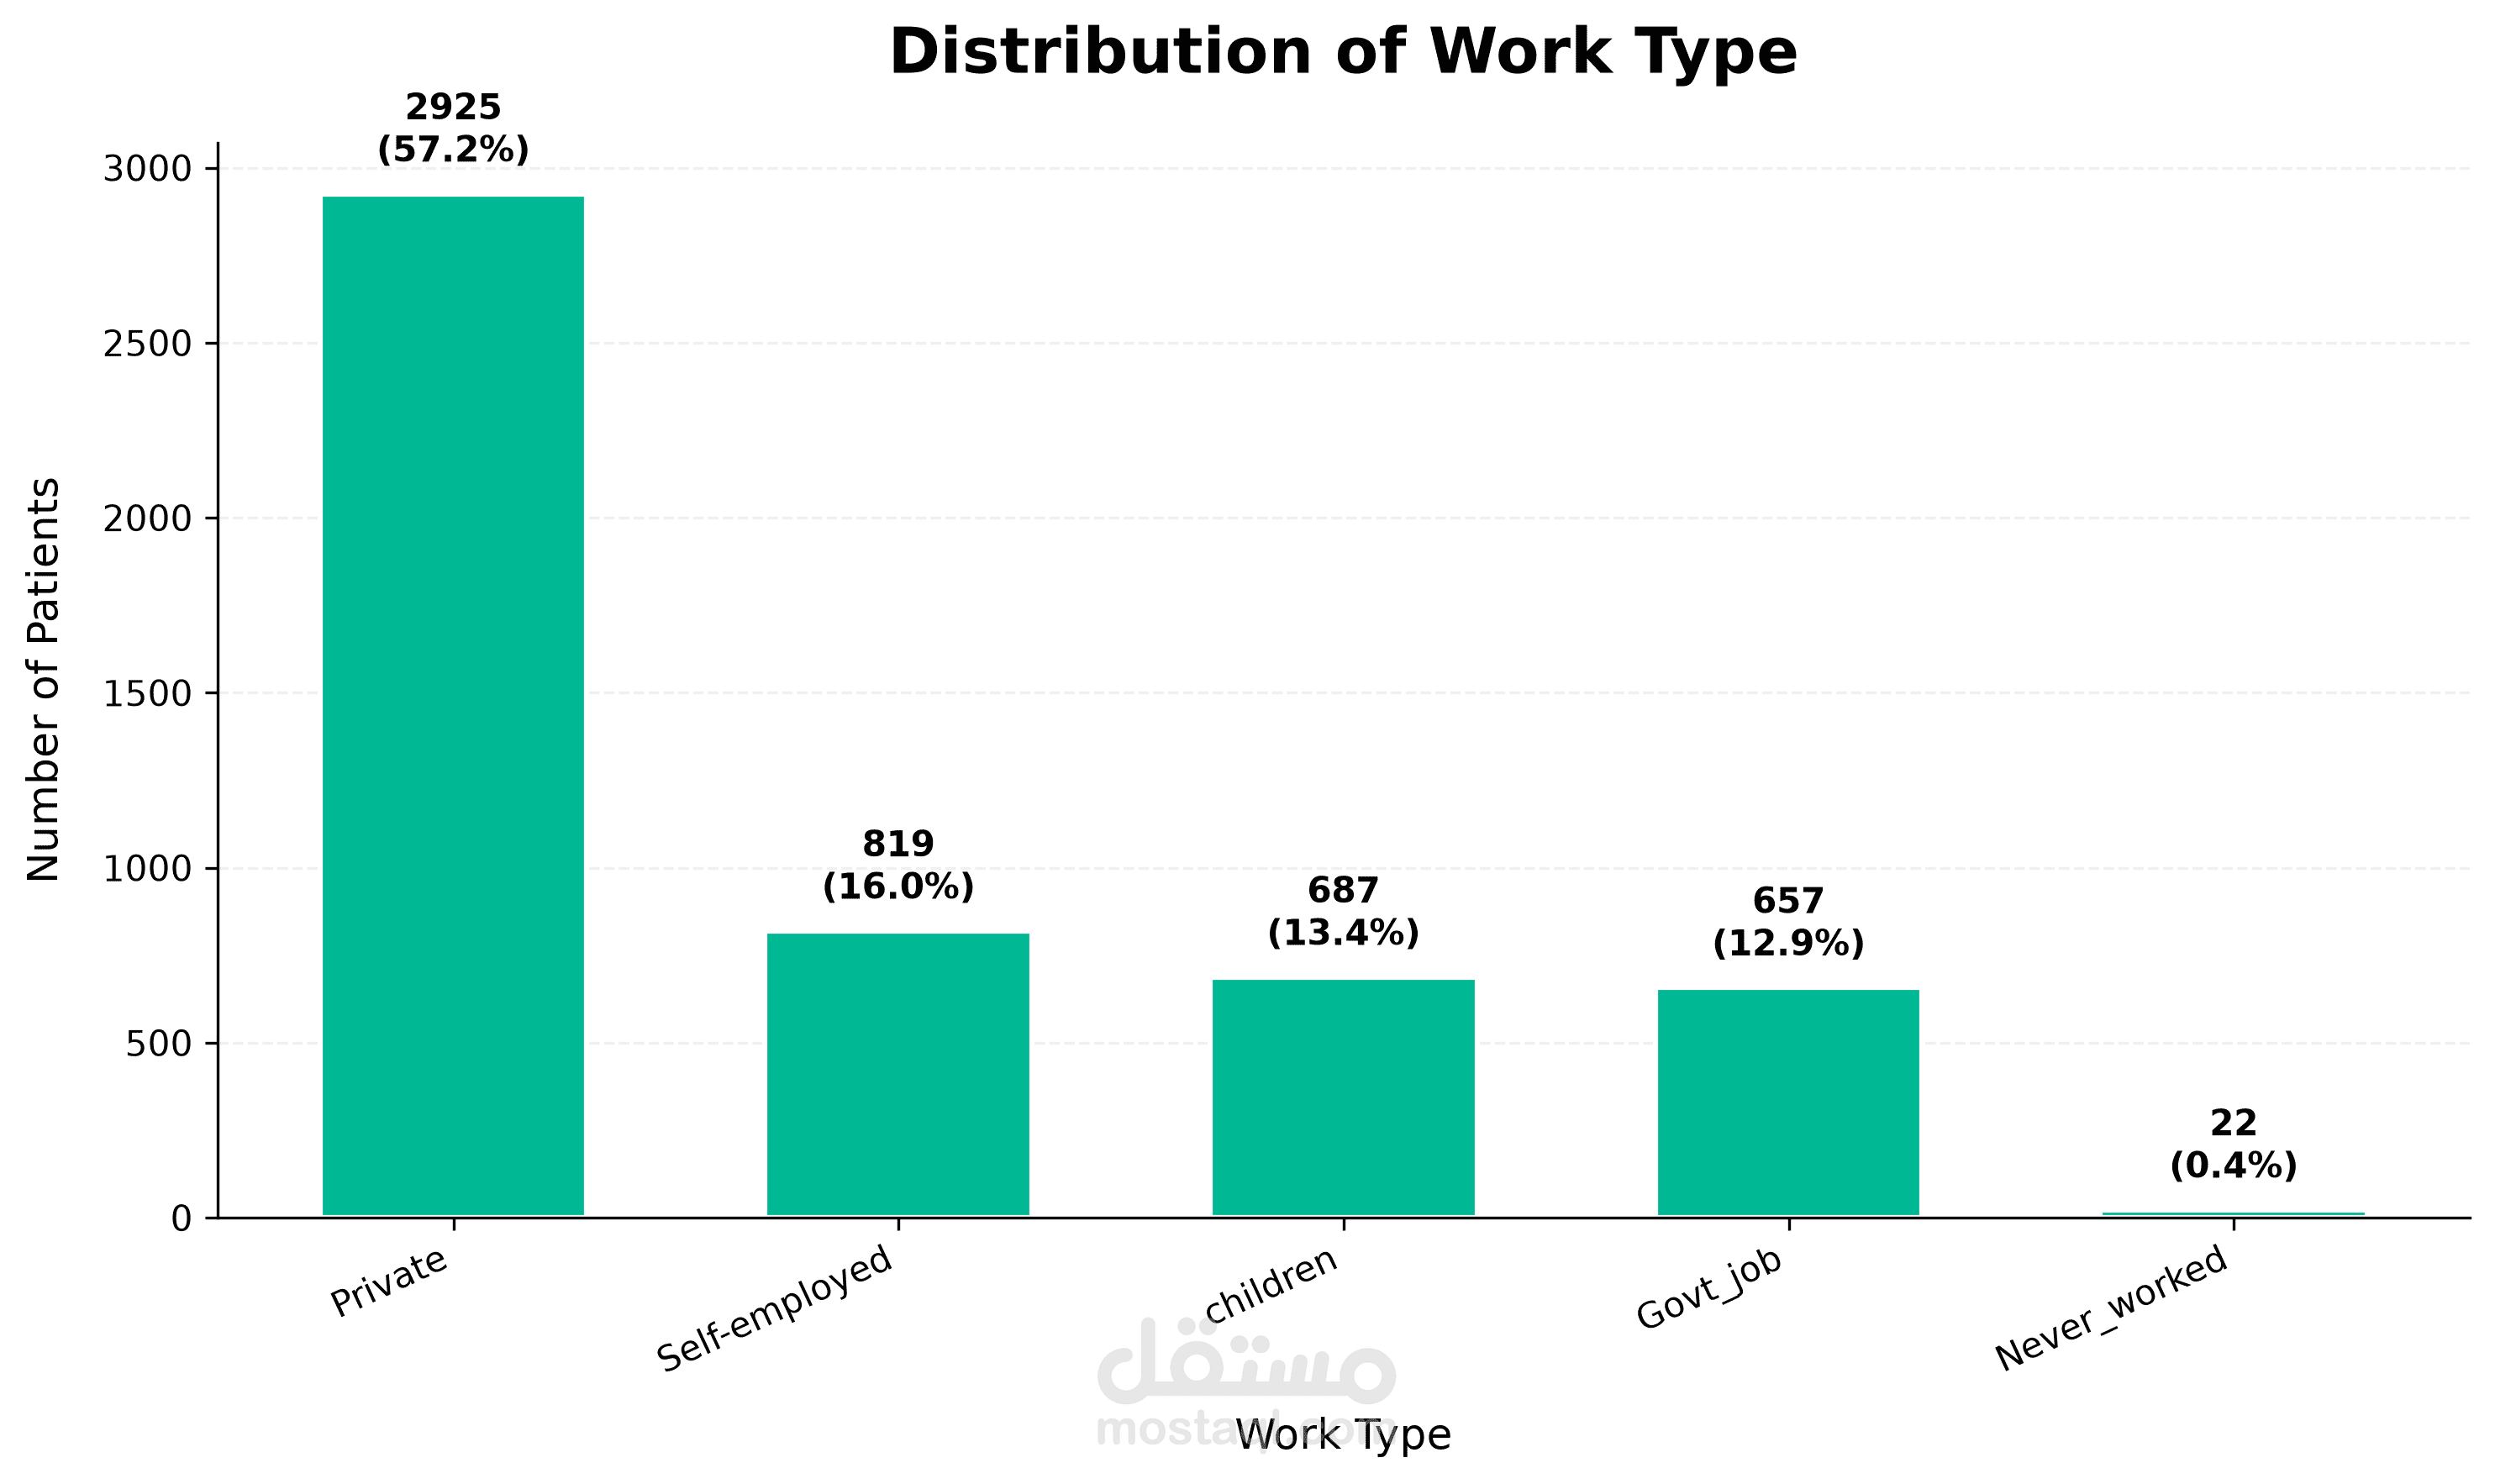
**Project Overview**
This project focuses on exploratory data analysis (EDA) of healthcare data to investigate patterns and relationships associated with stroke occurrence.
**Project Objectives**
- Explore and understand the healthcare dataset.
- Clean and prepare data for analysis.
- Handle missing values and assess data quality.
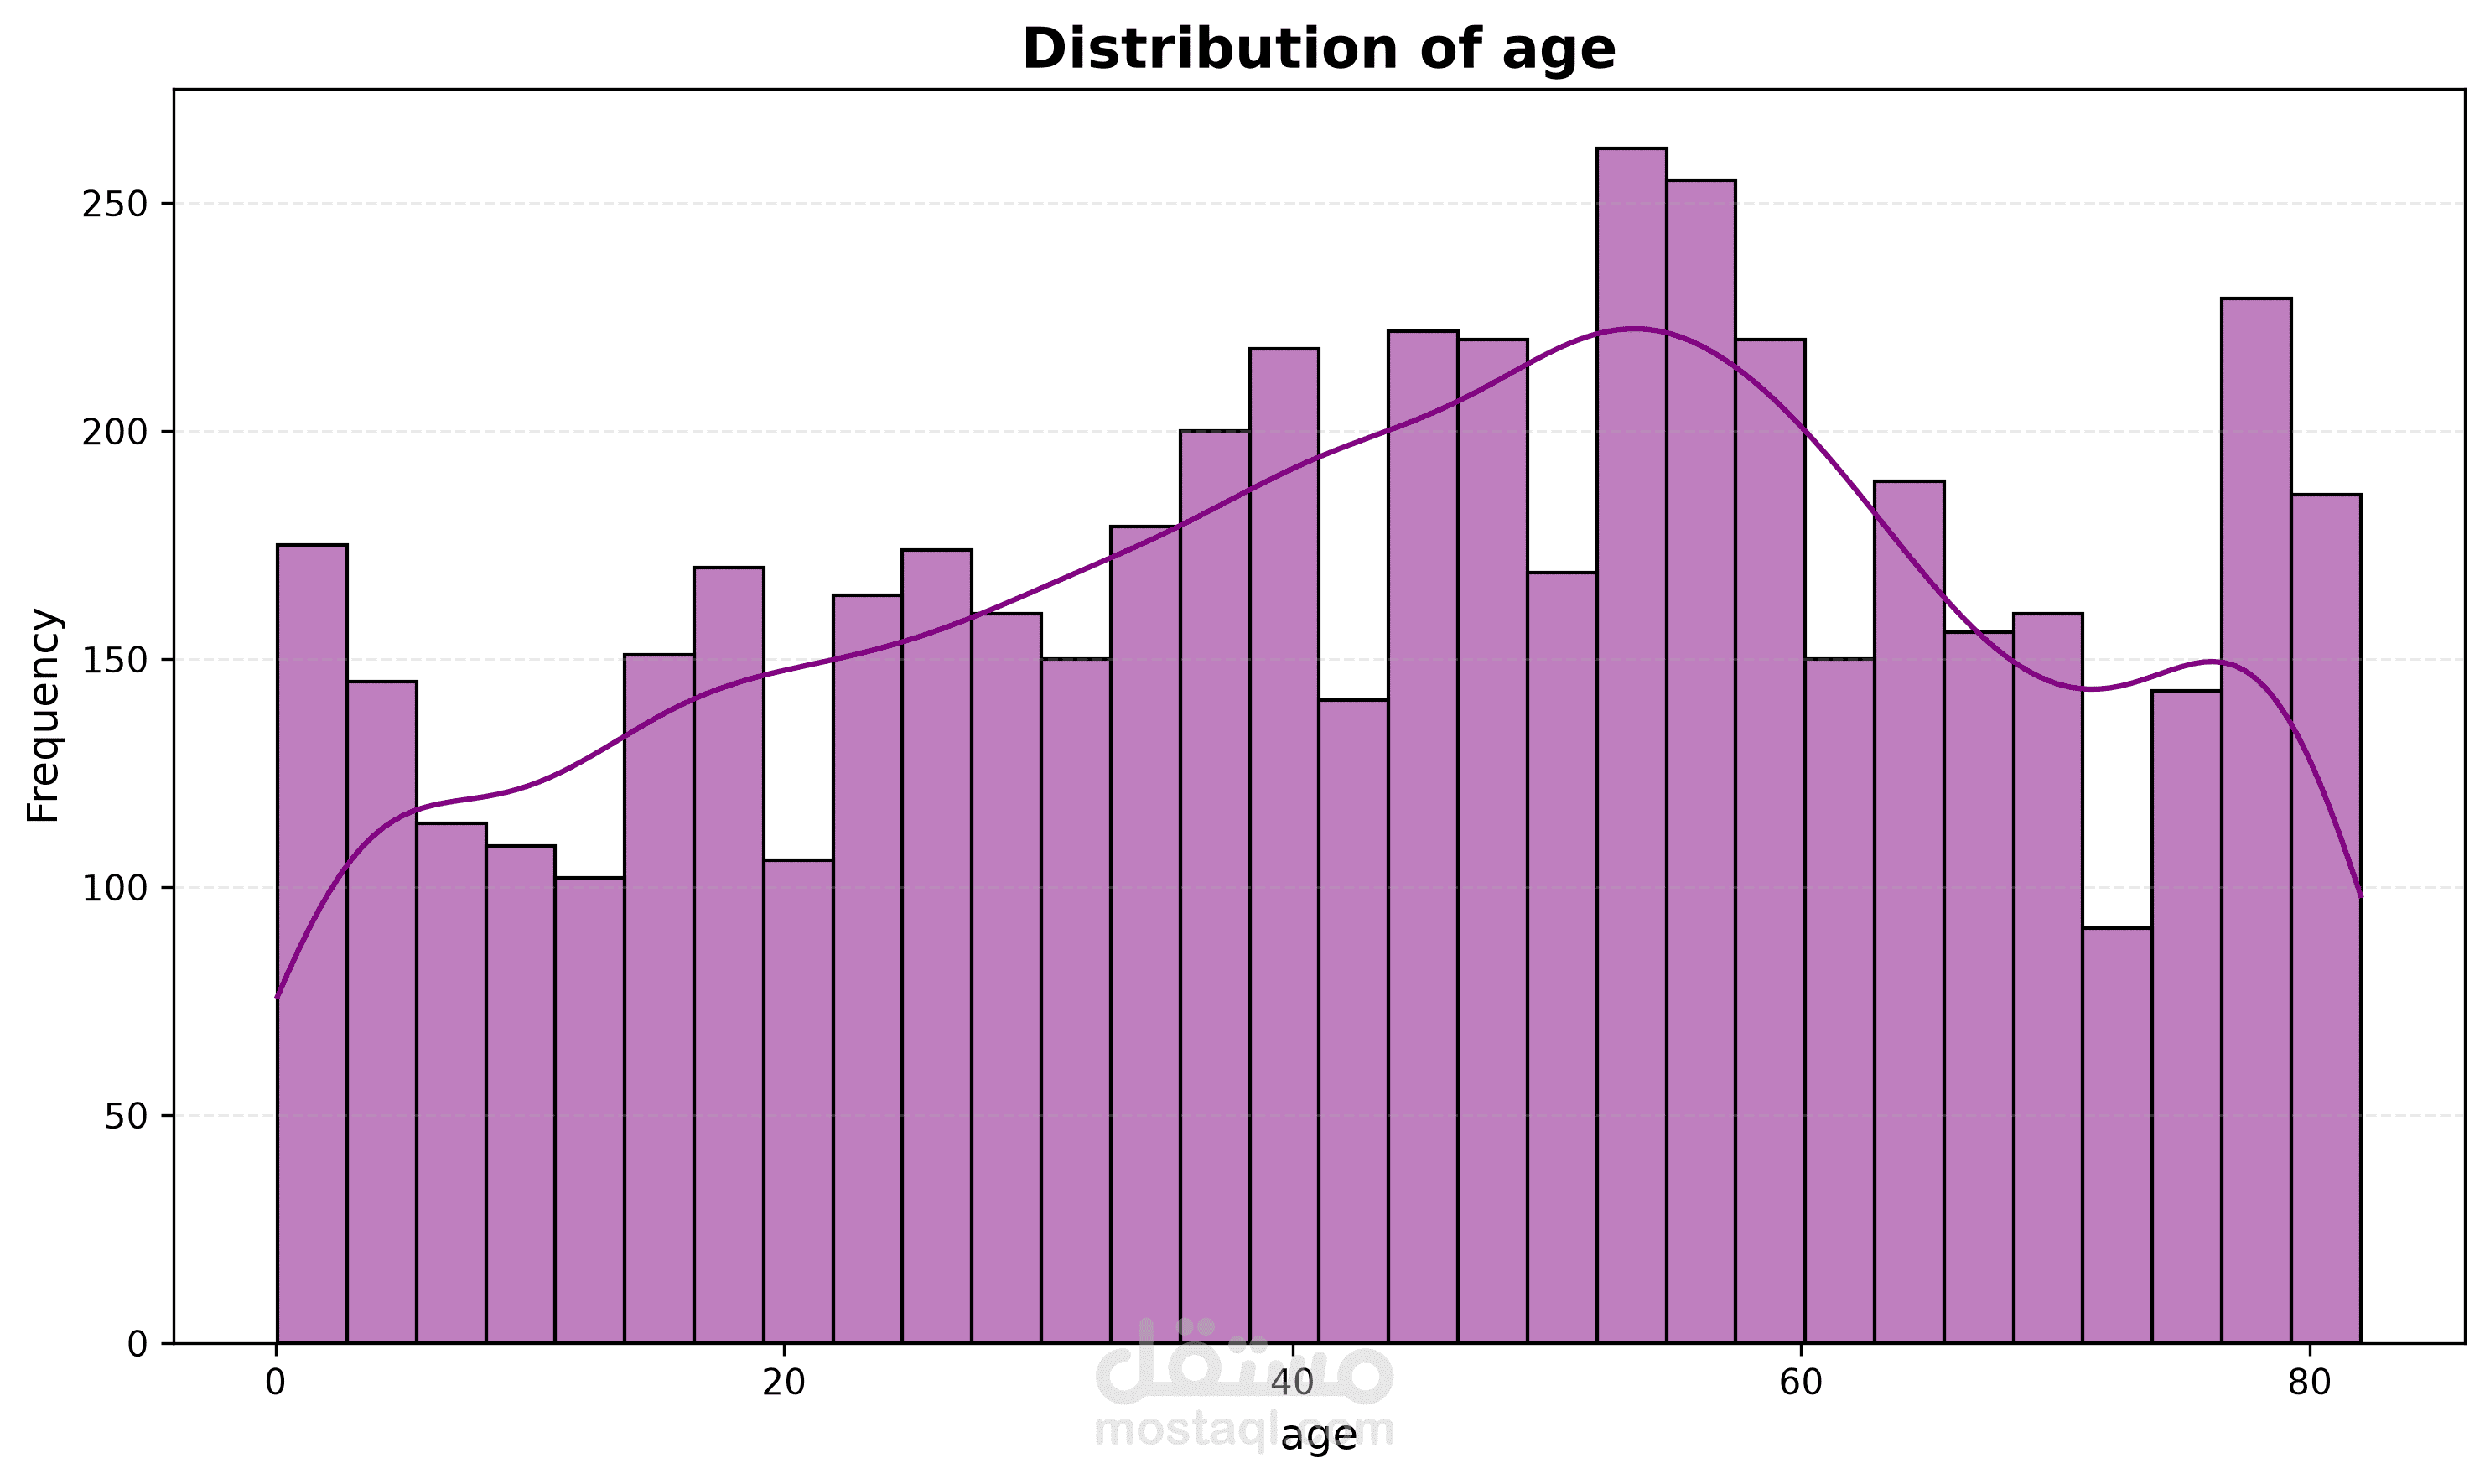
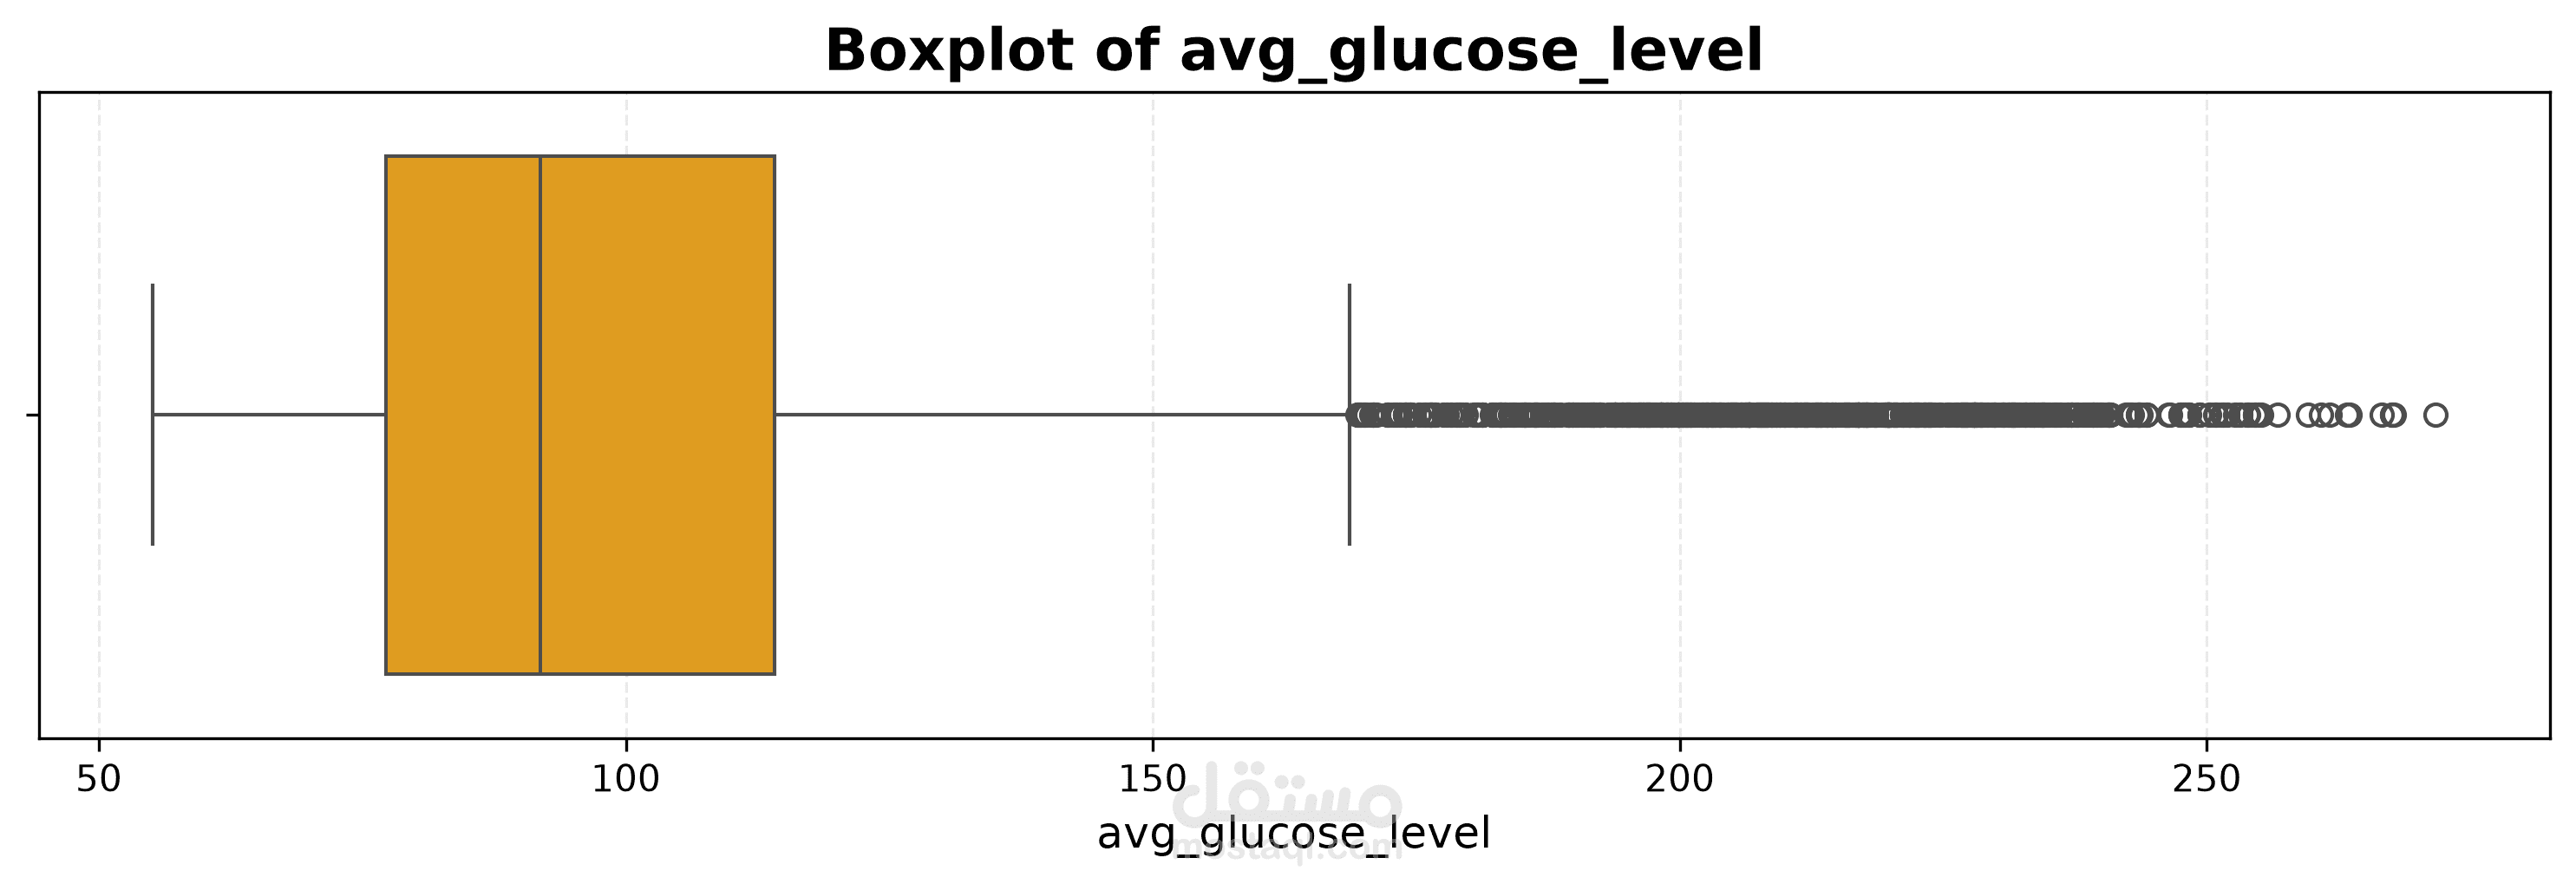
- Analyze numerical and categorical features.
- Explore relationships between patient characteristics and stroke occurrence.
- Create visualizations to communicate findings clearly.
**Tools & Technologies**
- Python
- Pandas and NumPy
- Matplotlib and Seaborn
- Jupyter Notebook
**Key Tasks Performed**
- Data cleaning and preprocessing.
- Missing-value and duplicate checks.
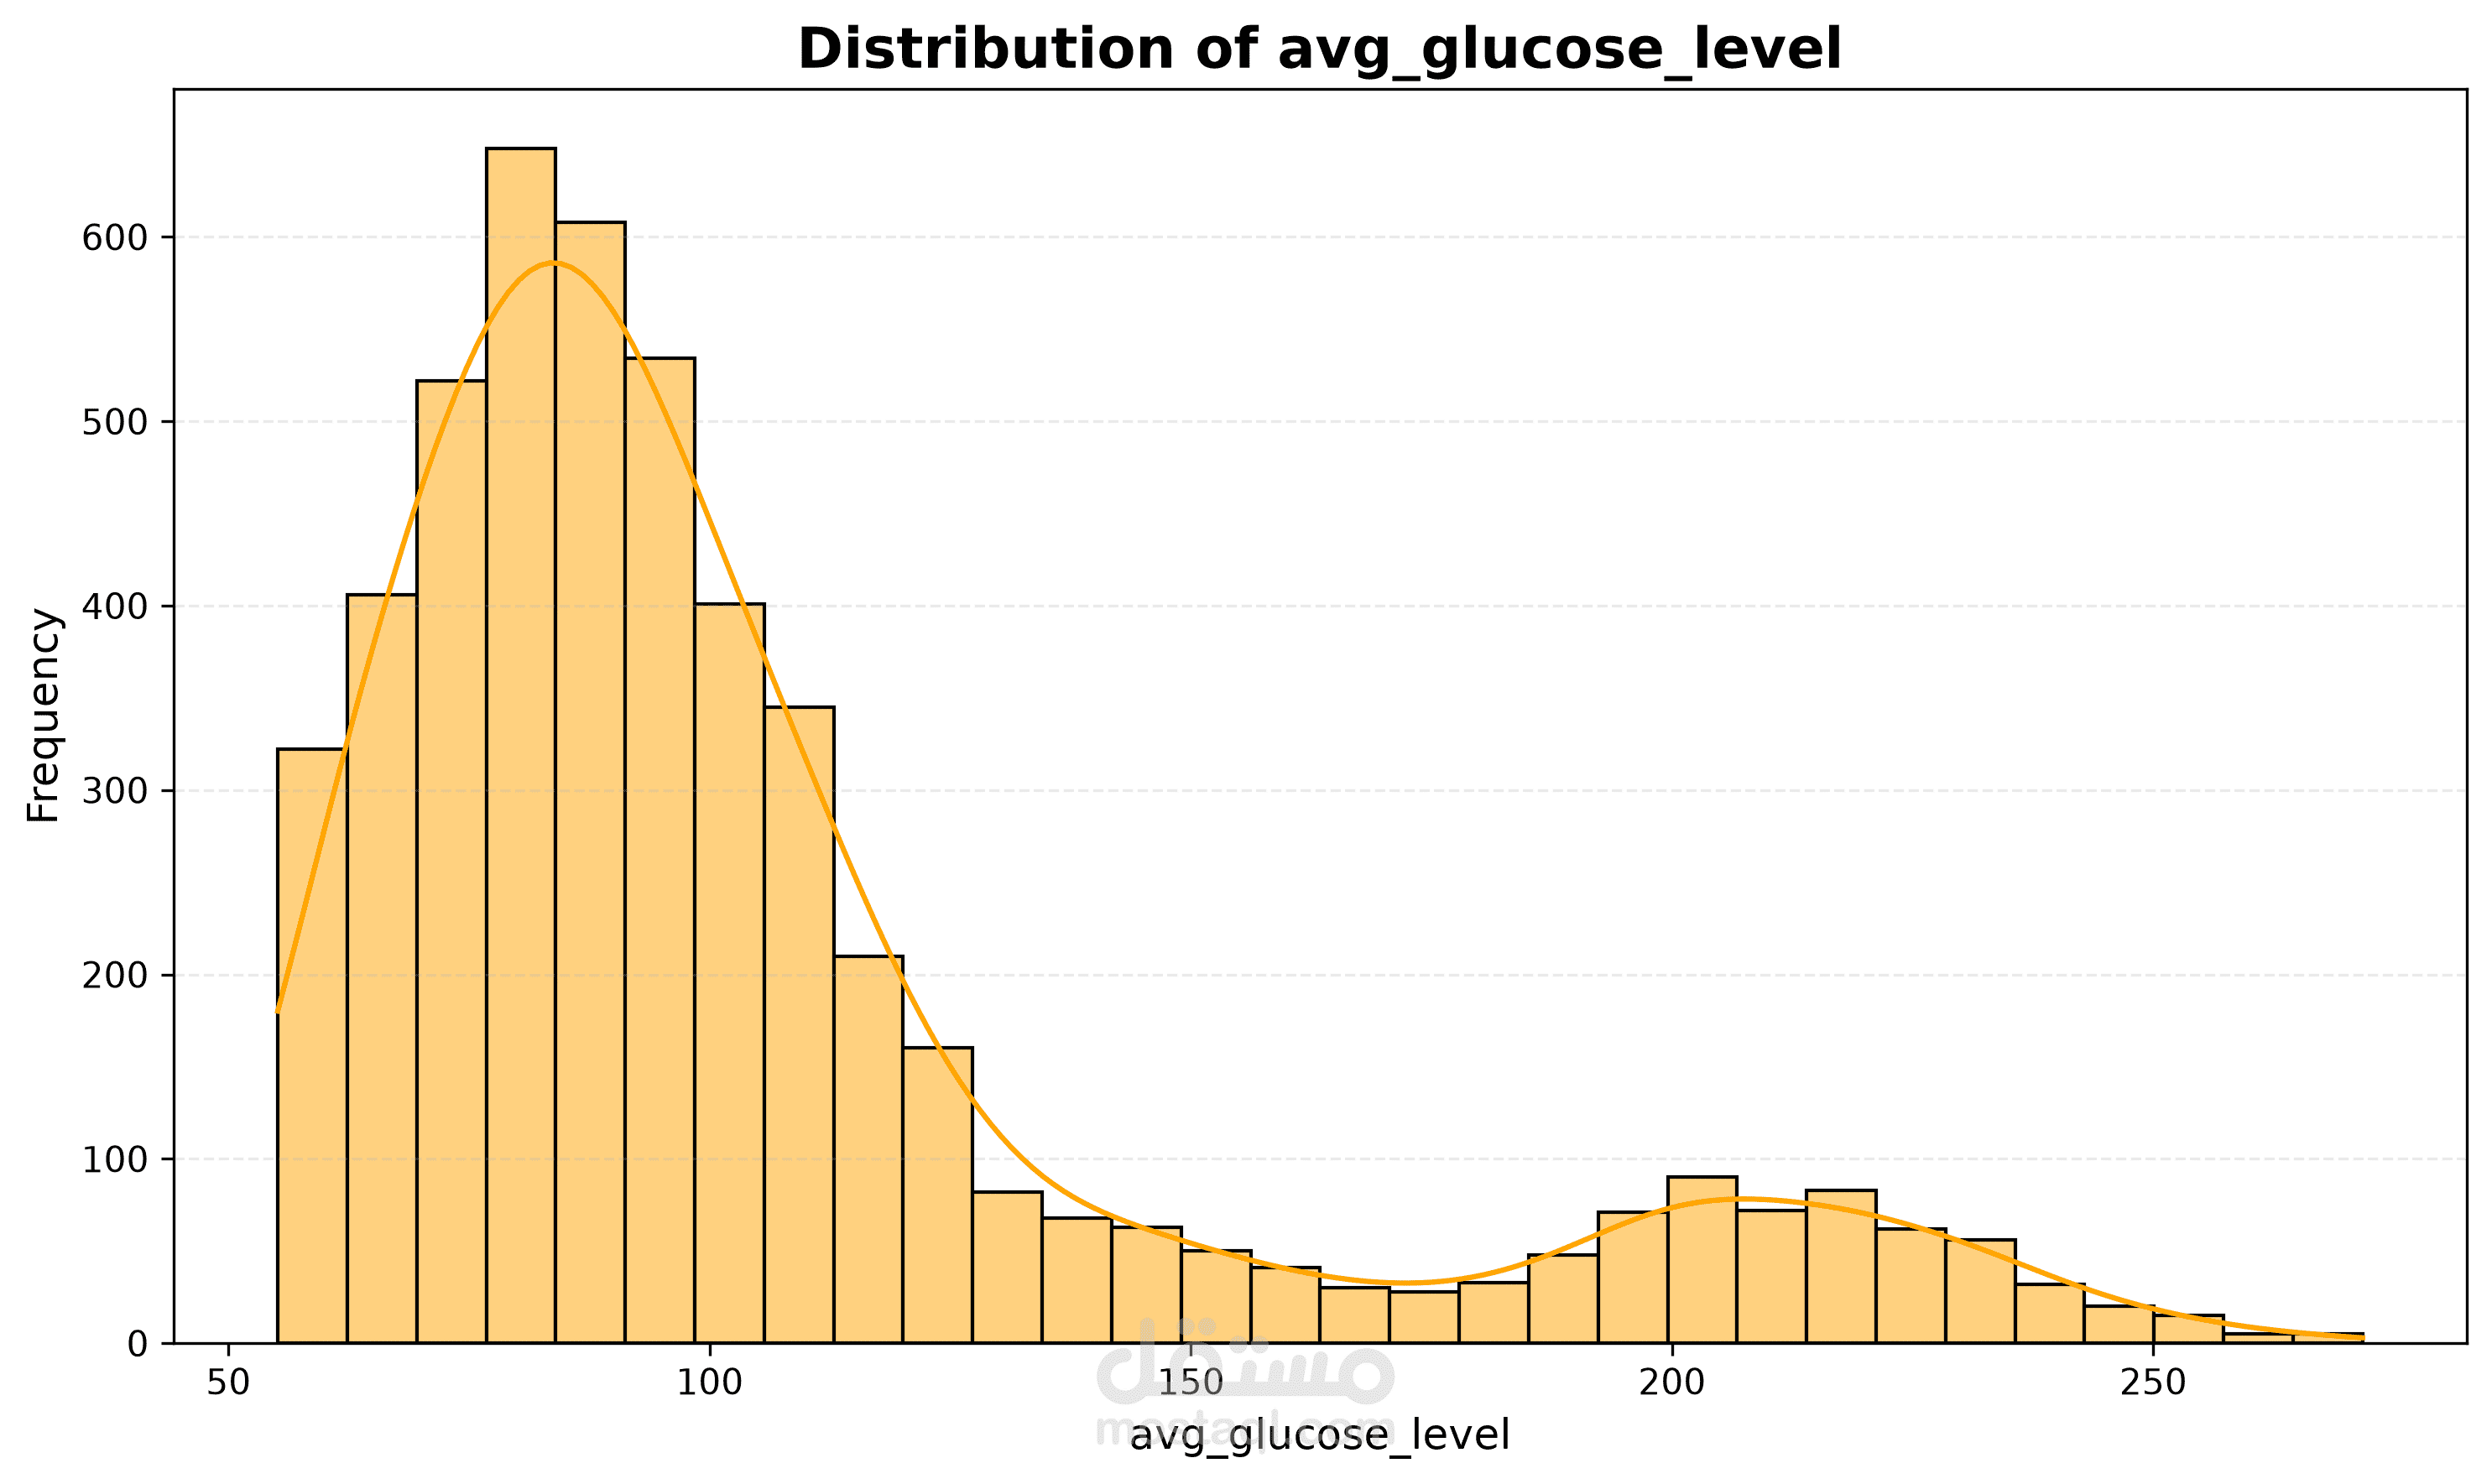
- Statistical summaries and exploratory analysis.
- Feature engineering, including age groups and BMI categories.
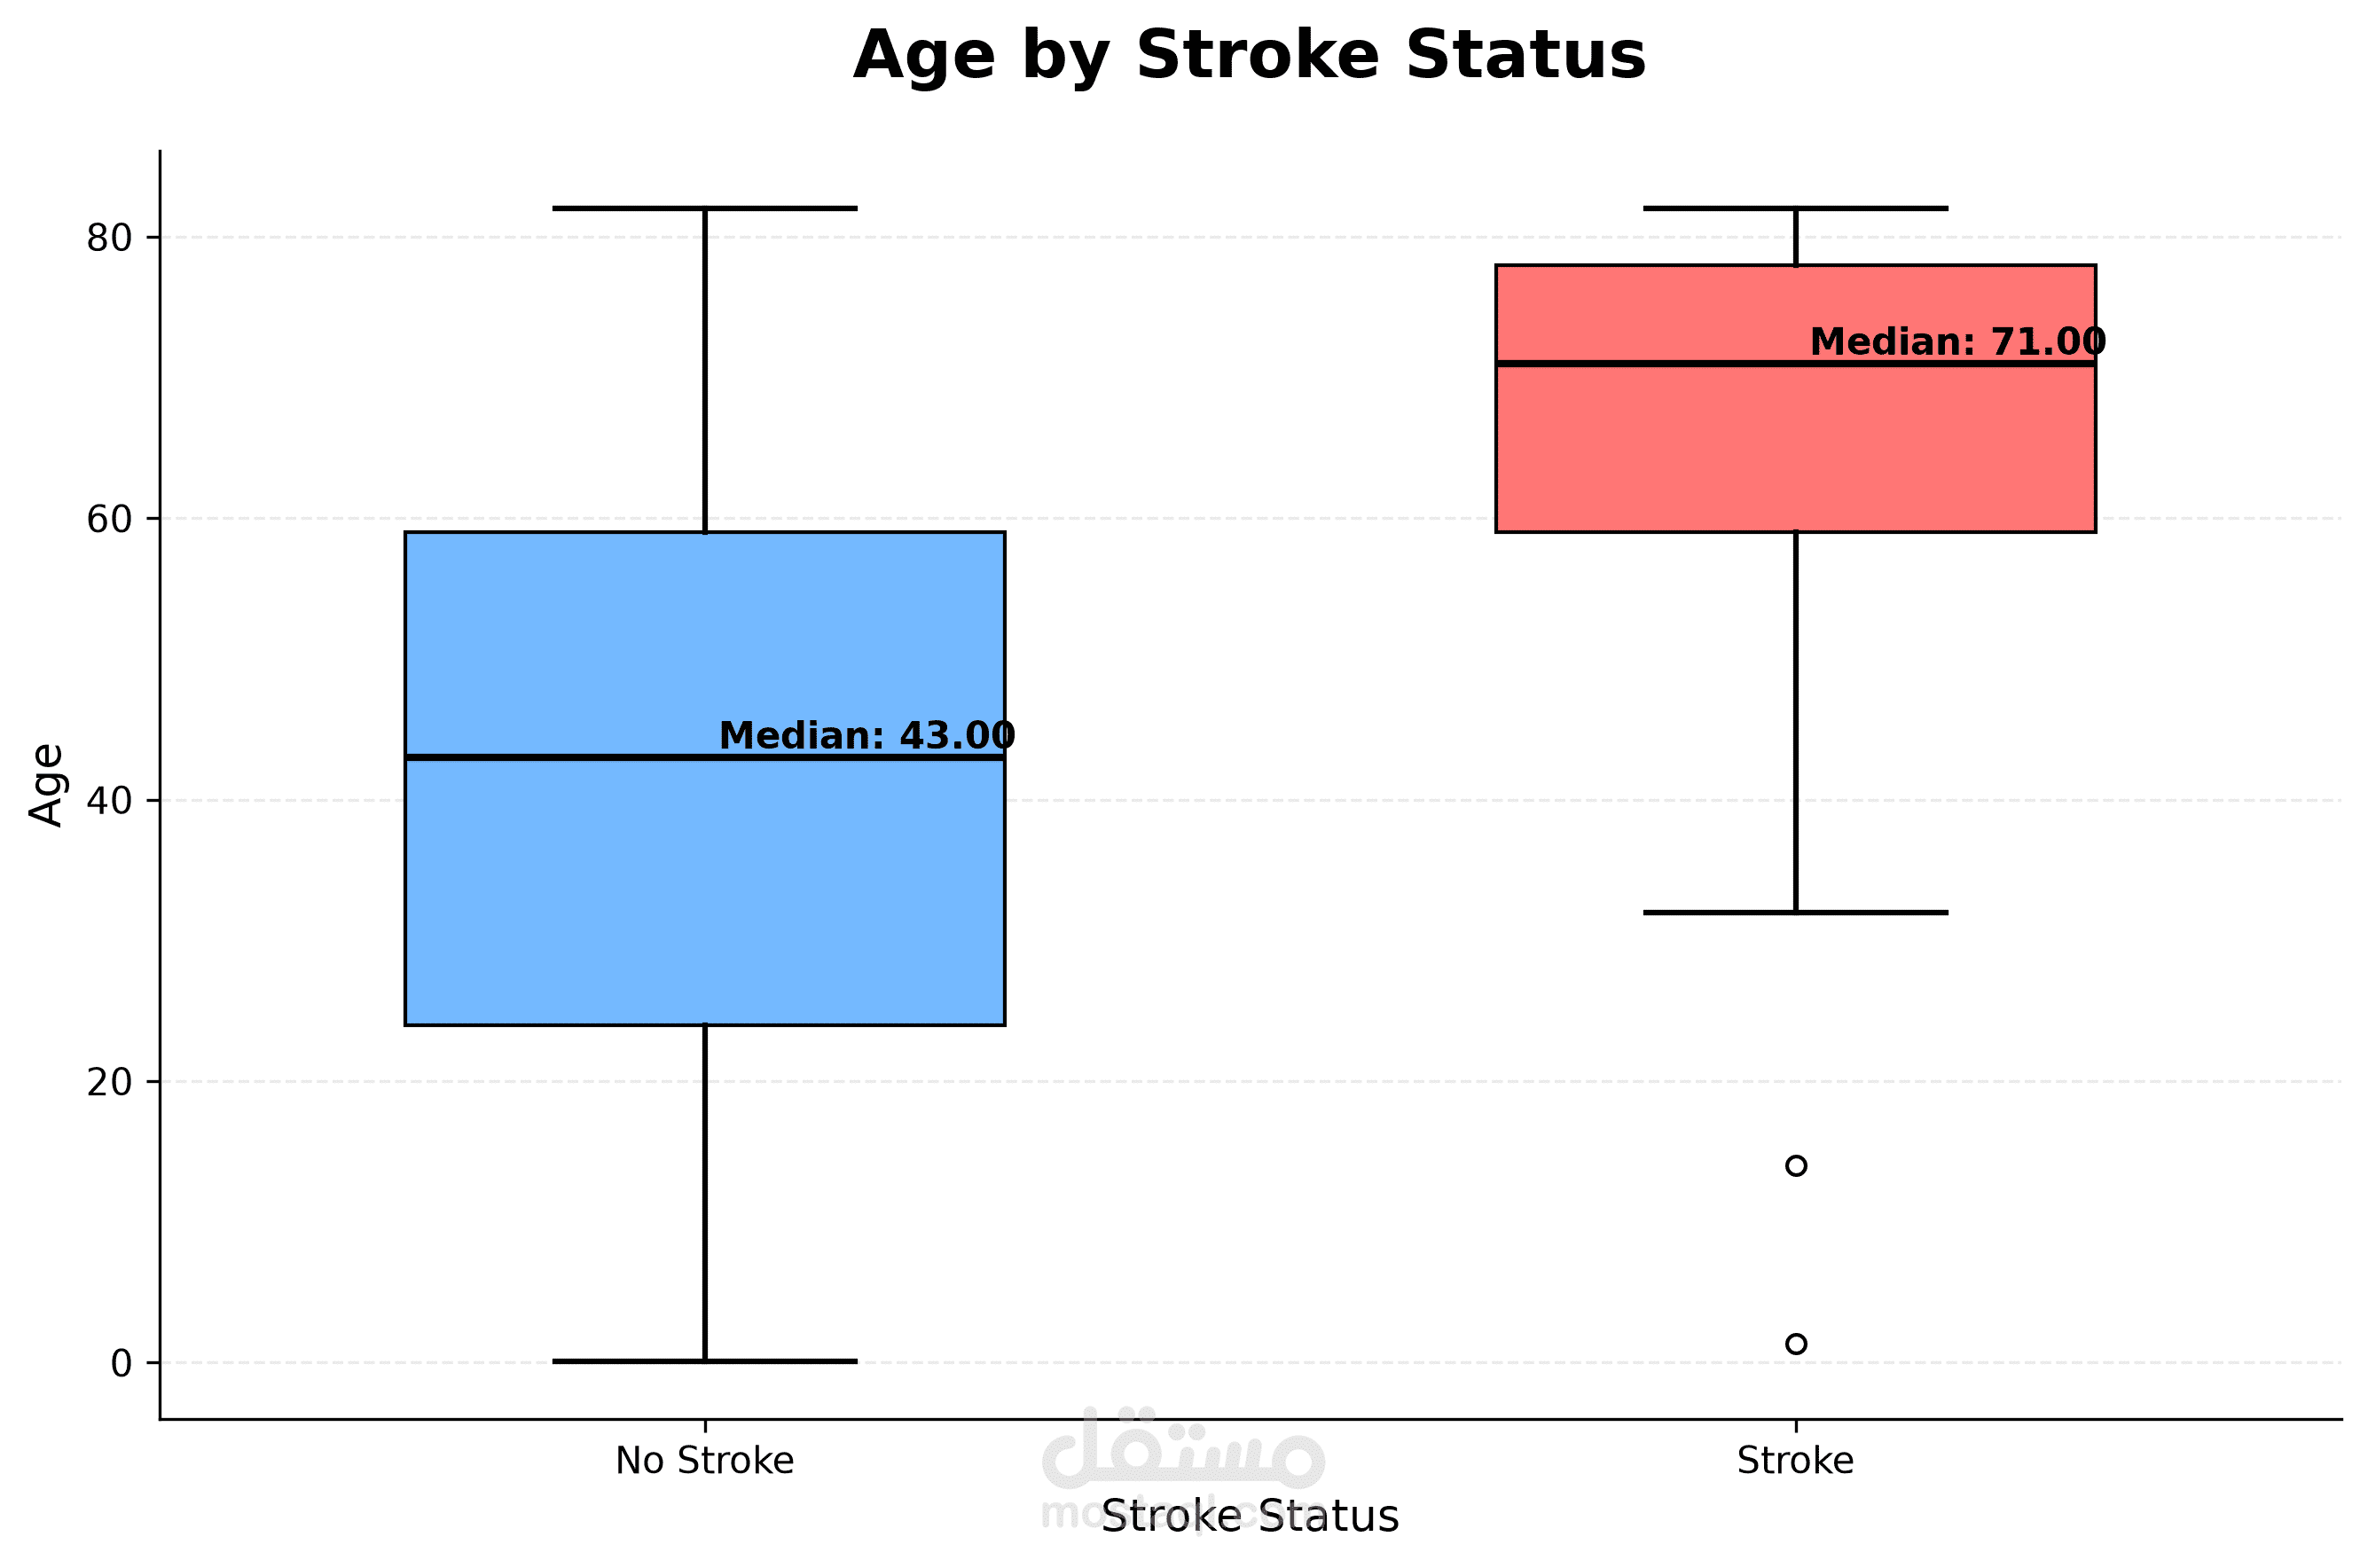
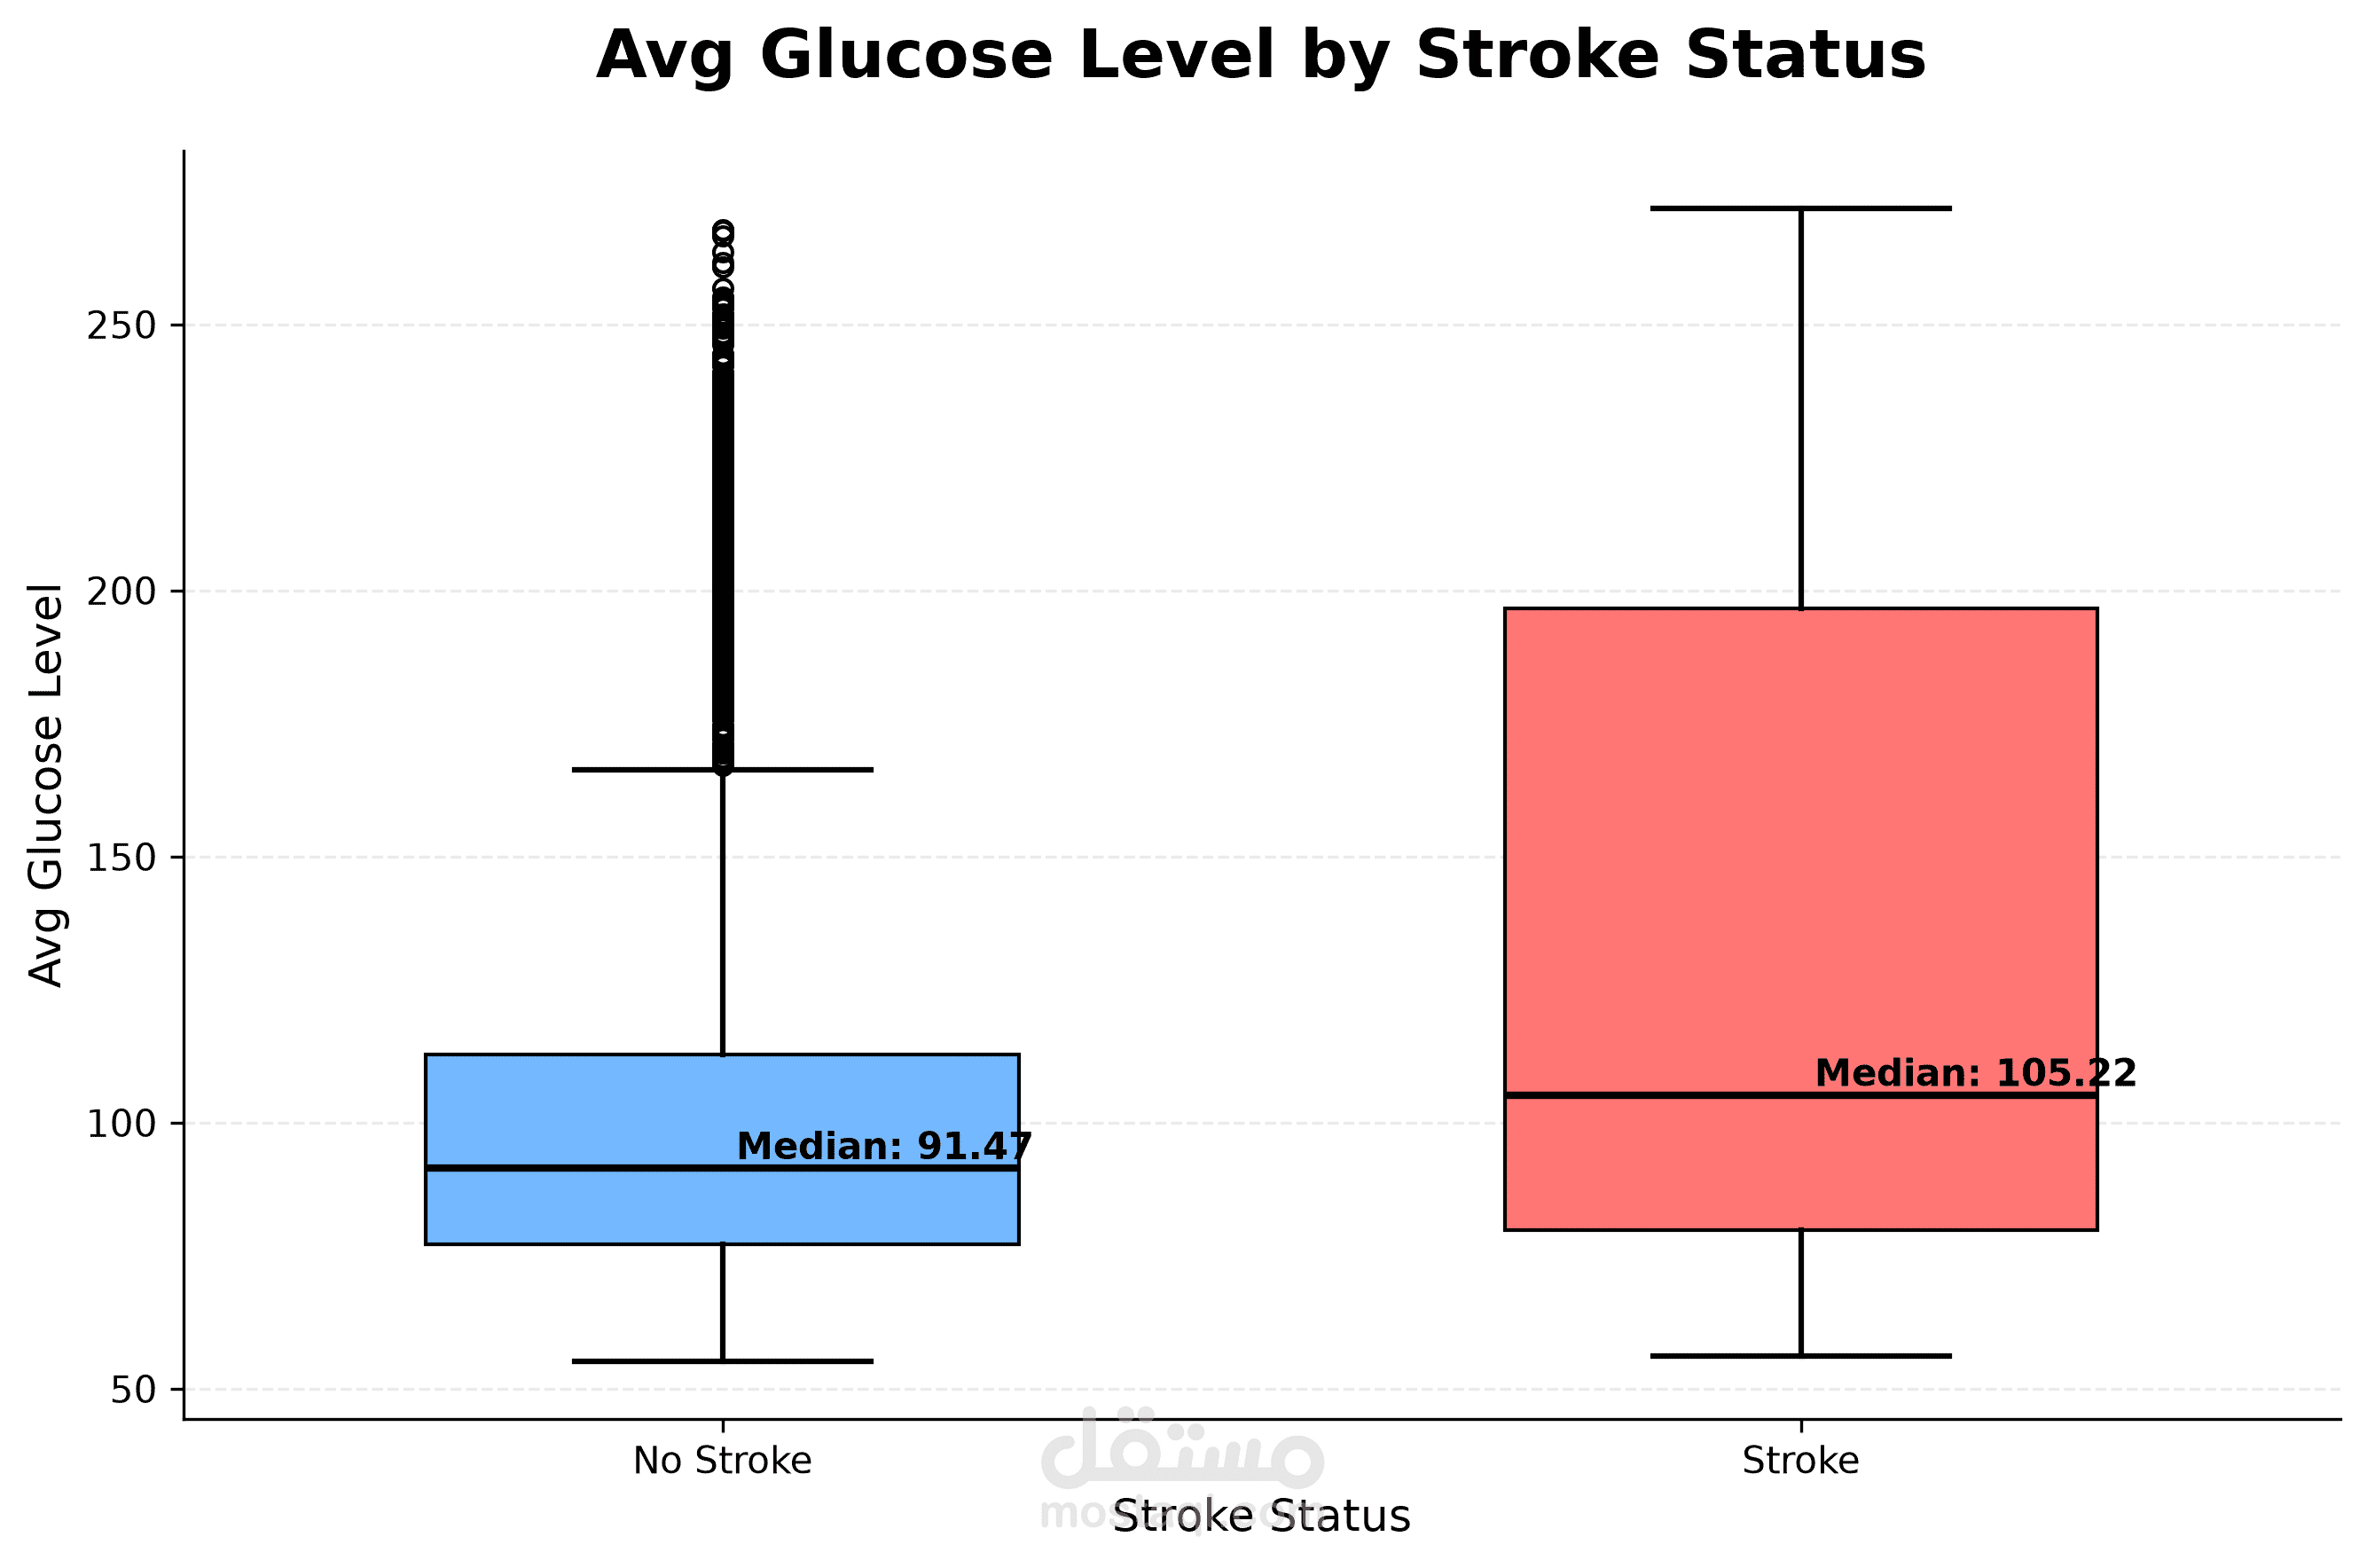
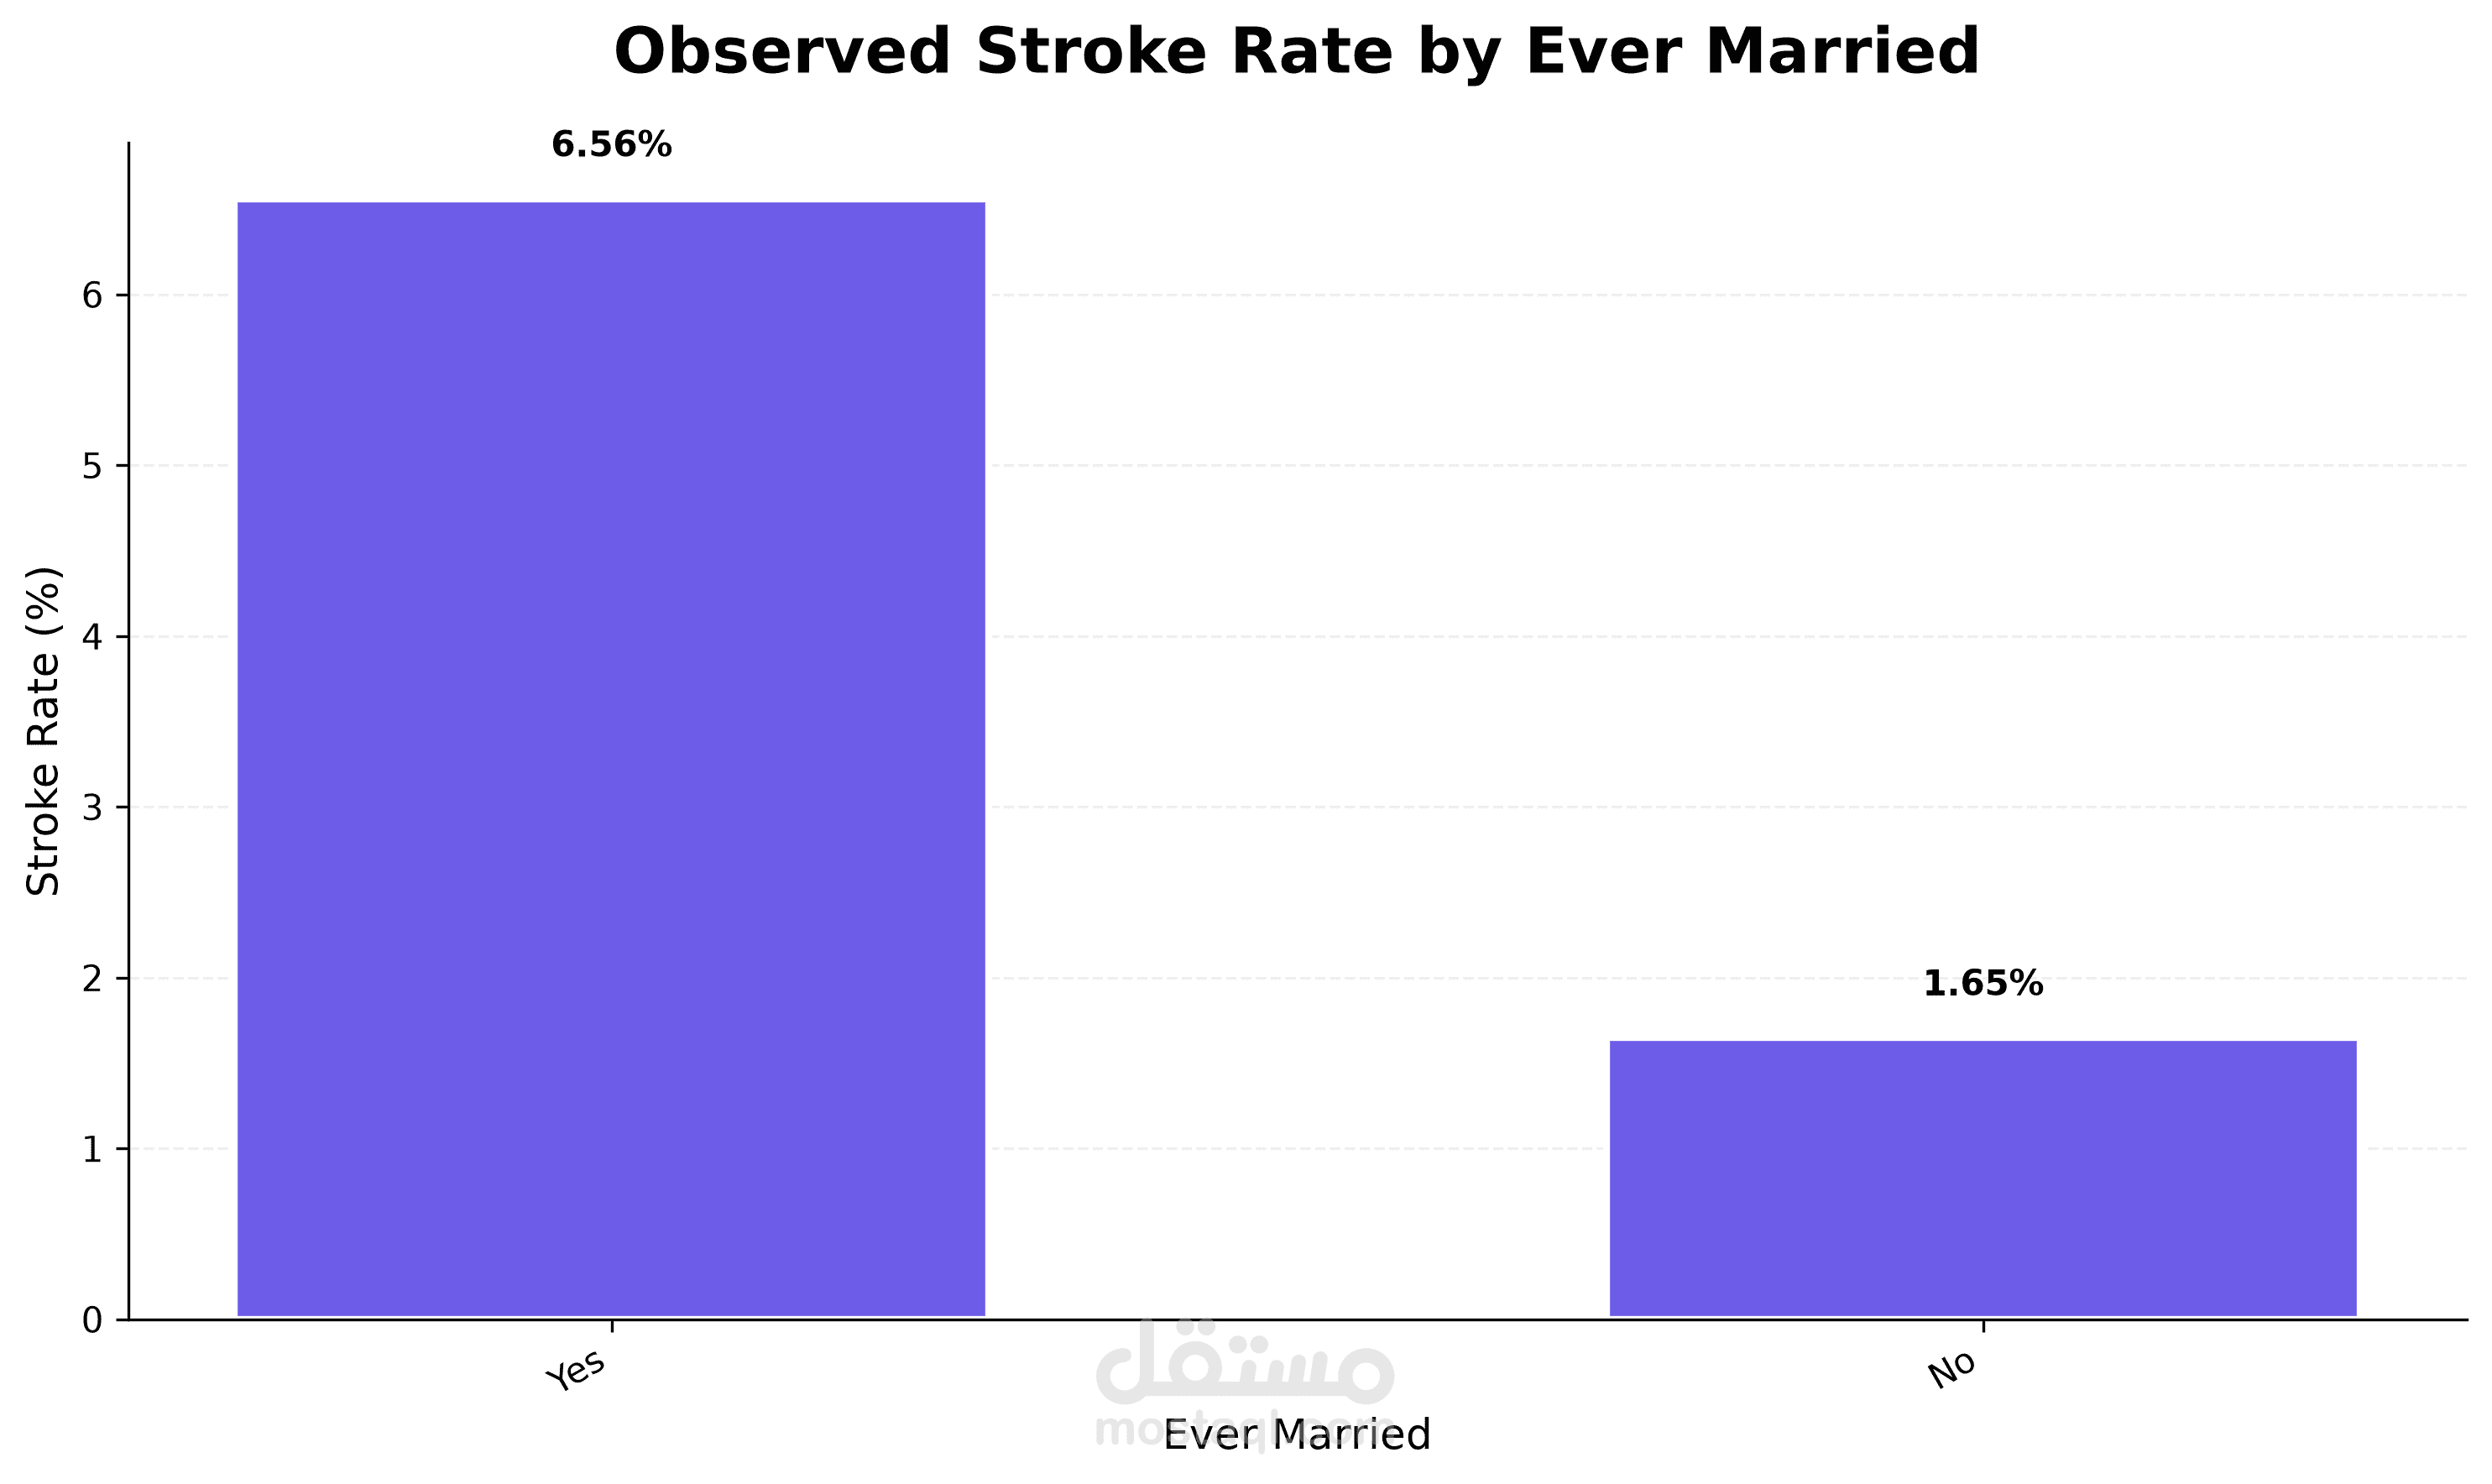
- Comparative analysis of patient characteristics by stroke status.
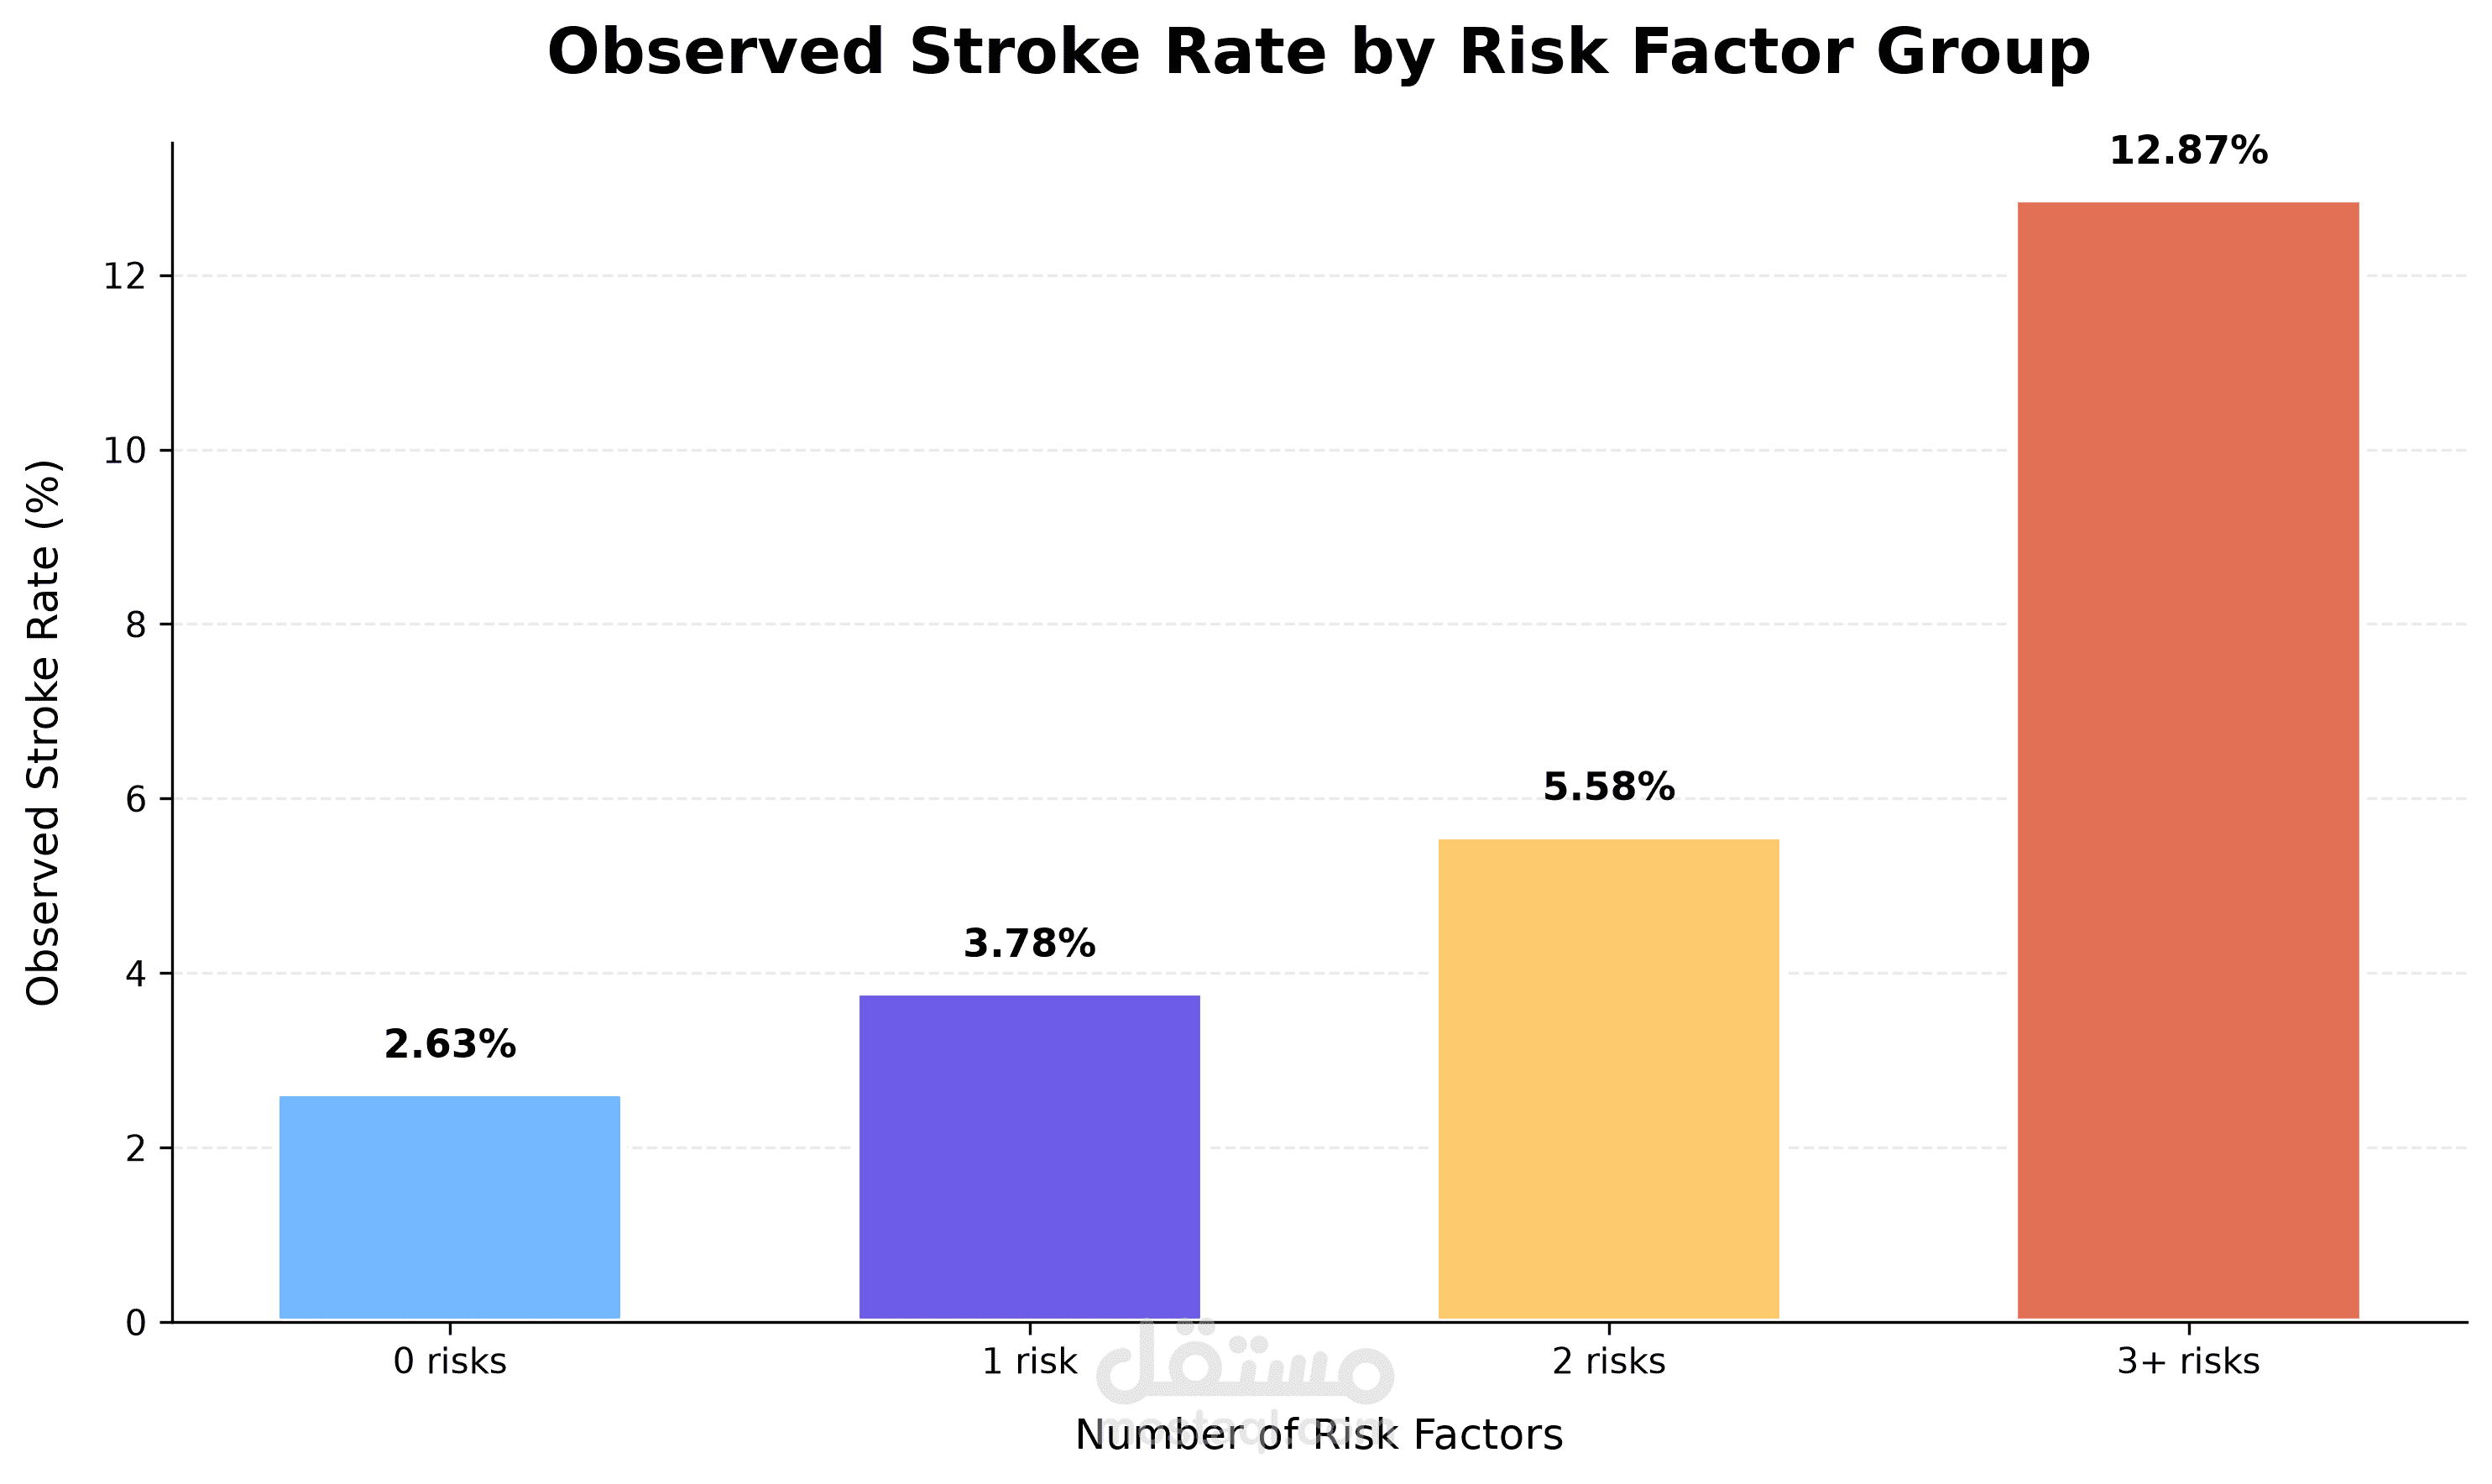
- Data visualization and interpretation of observed patterns.
**Deliverable**
A documented exploratory data analysis project with data preparation, visualizations, and insights into patterns in the dataset.
This project demonstrates practical skills in Python, healthcare data analysis, data cleaning, and visualization. The findings are exploratory and do not represent medical diagnoses or prove causal relationships.