LLM API Reliability — Response Caching with Groq
تفاصيل العمل
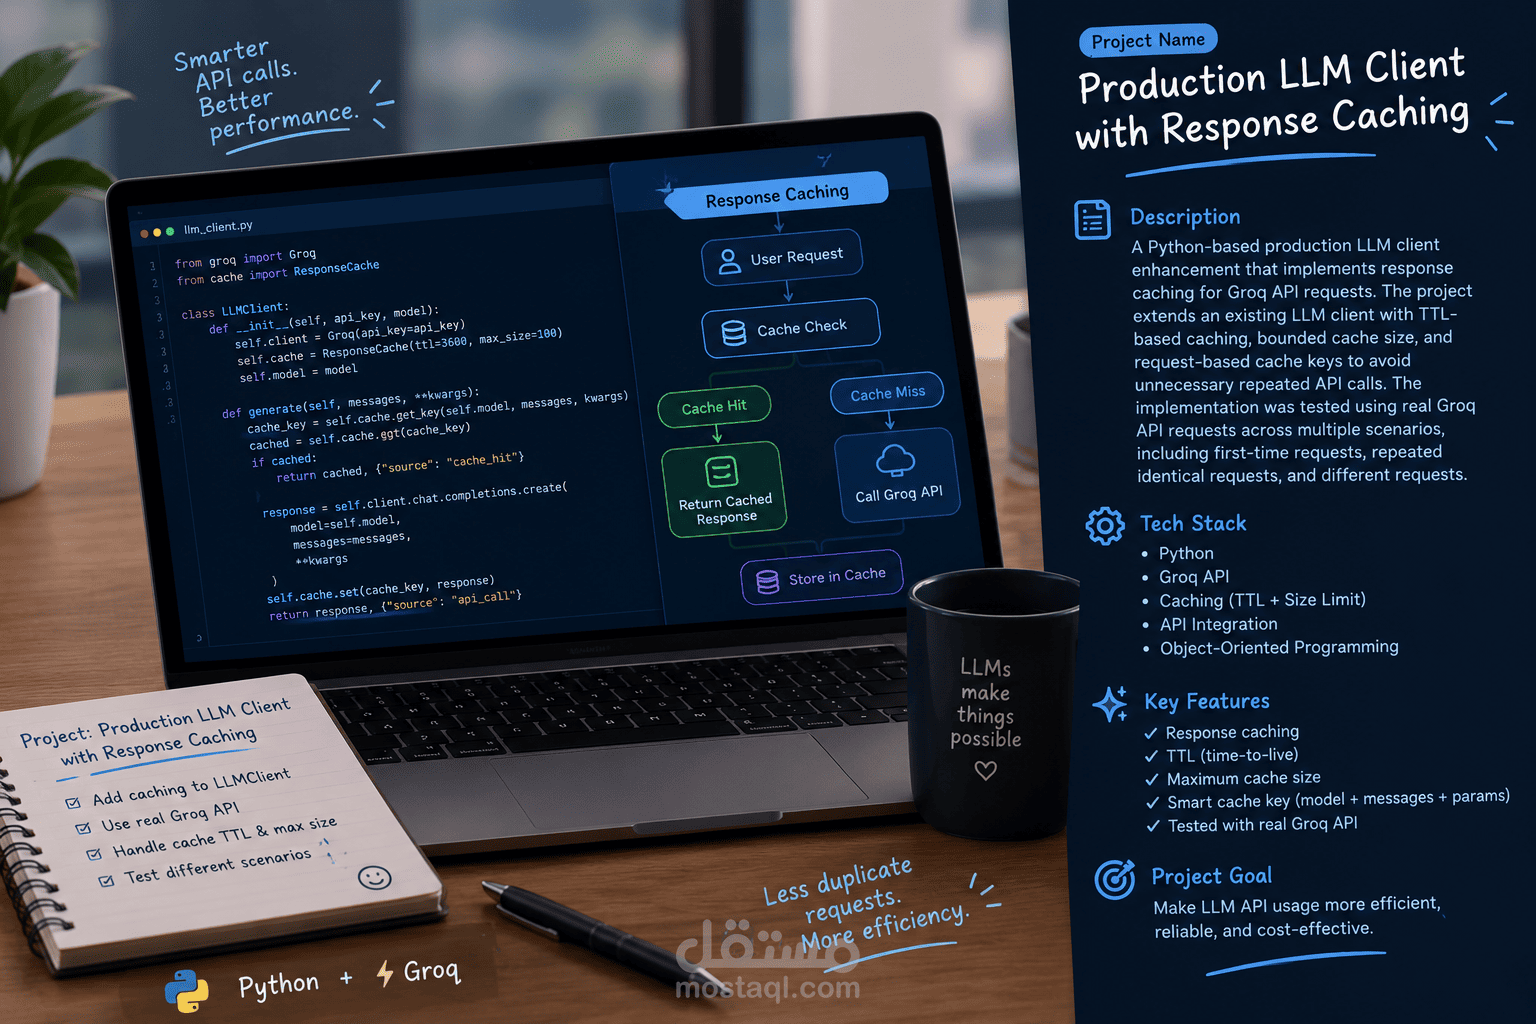
A Python-based production LLM client enhancement that implements response caching for Groq API requests. The project extends an existing LLM client with TTL-based caching, bounded cache size, and request-based cache keys to avoid unnecessary repeated API calls. The implementation was tested using real Groq API requests across multiple scenarios, including first-time requests, repeated identical requests, and different requests.