Arabic Automatic Speech Recognition (ASR) System from Scratch
تفاصيل العمل
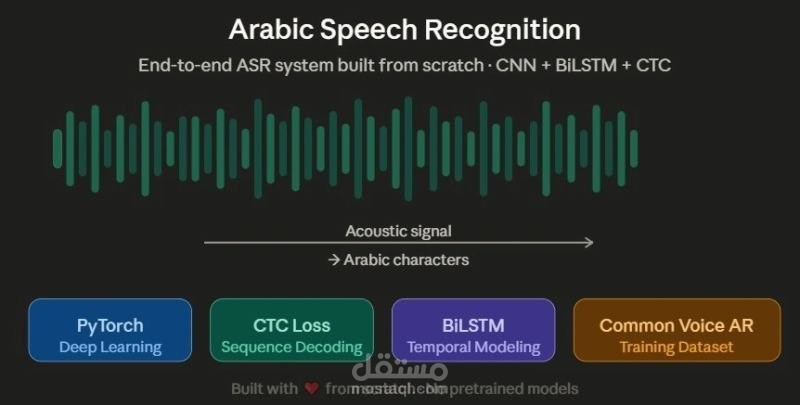
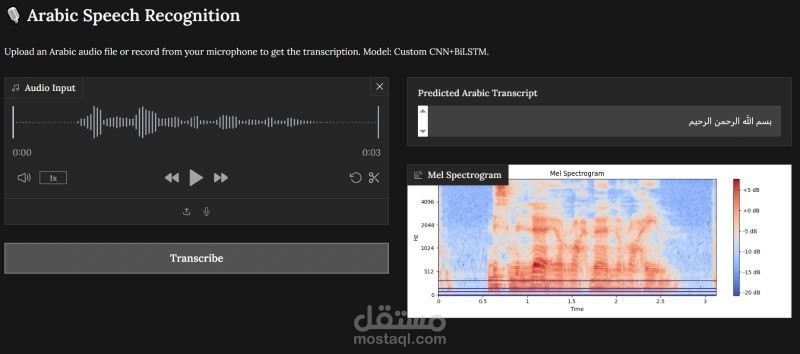
Developed an end-to-end Arabic Automatic Speech Recognition (ASR) system from scratch using PyTorch, without relying on pretrained models.
The system uses a custom CNN + BiLSTM + CTC architecture and was trained on the Mozilla Common Voice Arabic dataset. I implemented the complete pipeline, including audio preprocessing, Arabic text normalization, SpecAugment, mixed-precision training (AMP), checkpoint management, and real-time WER/CER evaluation.
A Greedy CTC Decoder was implemented for speech-to-text inference, along with an interactive Gradio interface for testing live Arabic speech transcription.
Model Performance:
• WER: 35.48%
• CER: 10.69%
Tech Stack:
• PyTorch
• torchaudio
• librosa
• Gradio
• jiwer
This project strengthened my practical experience in deep learning, speech processing, sequence modeling, CTC-based training, and building complete AI systems from the ground up.