credit-risk-prediction
تفاصيل العمل
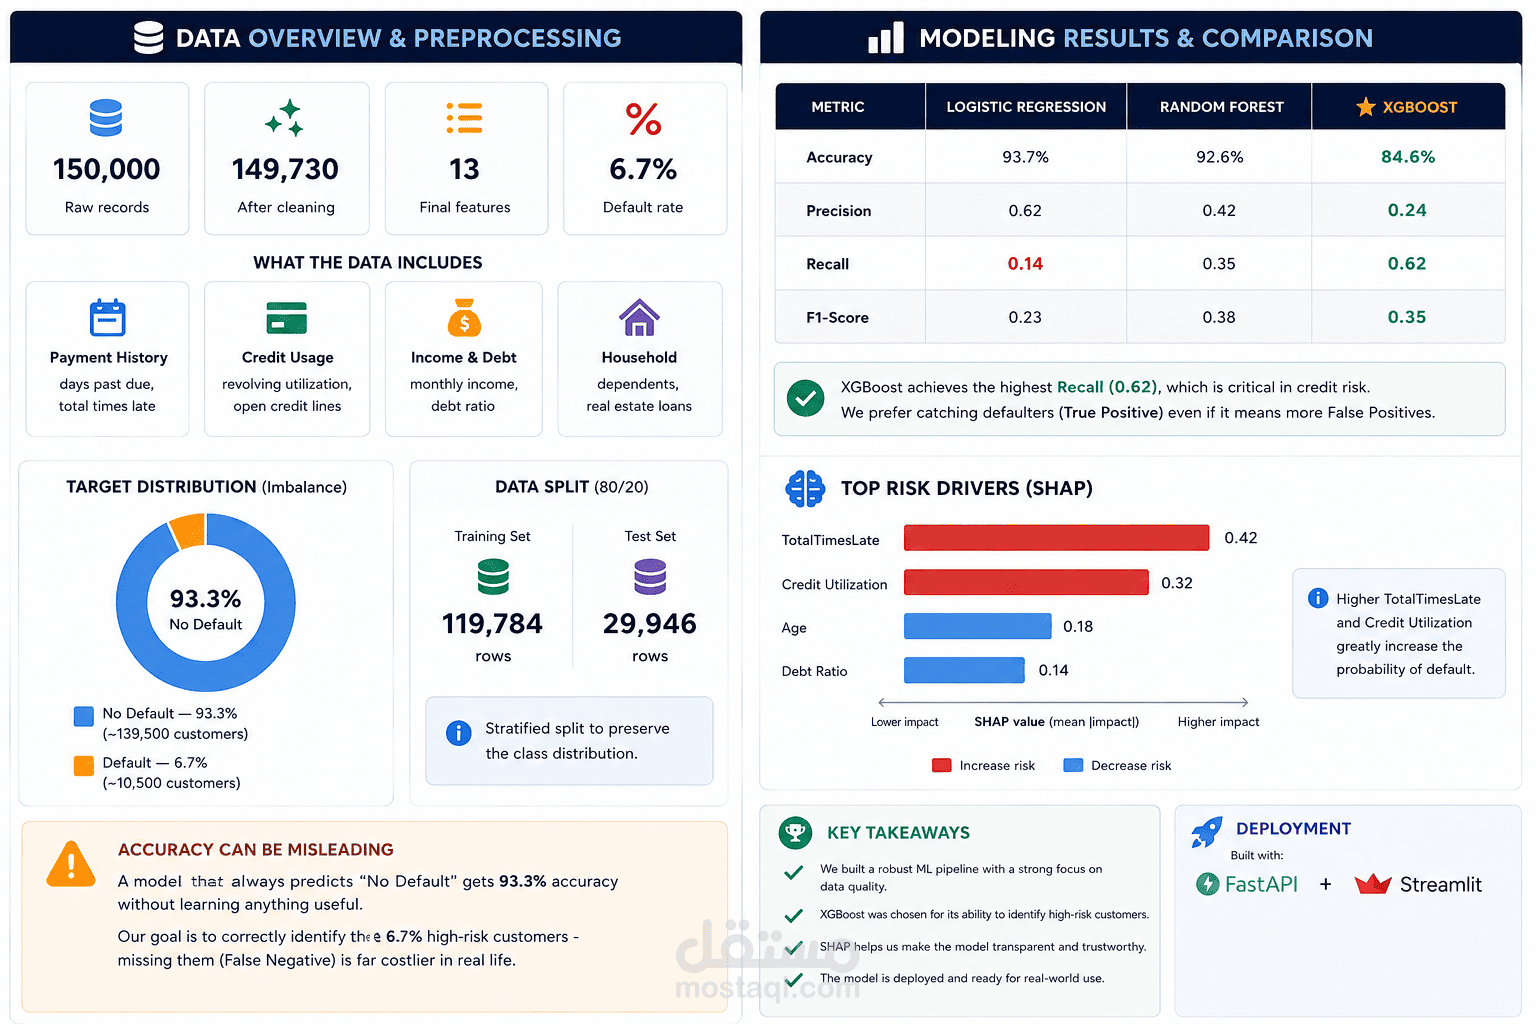
•Built an end-to-end ML pipeline on 150,000 customer records, cleaning and engineering 13 final features while
handling a 93.3%/6.7% class imbalance.
•Trained and compared Logistic Regression, Random Forest, and XGBoost, selecting XGBoost for achieving the
highest recall (0.62) — critical for correctly identifying high-risk customers.
•Used SHAP to identify Total Times Late and Credit Utilization as the top drivers of default risk, improving model
transparency and trust.
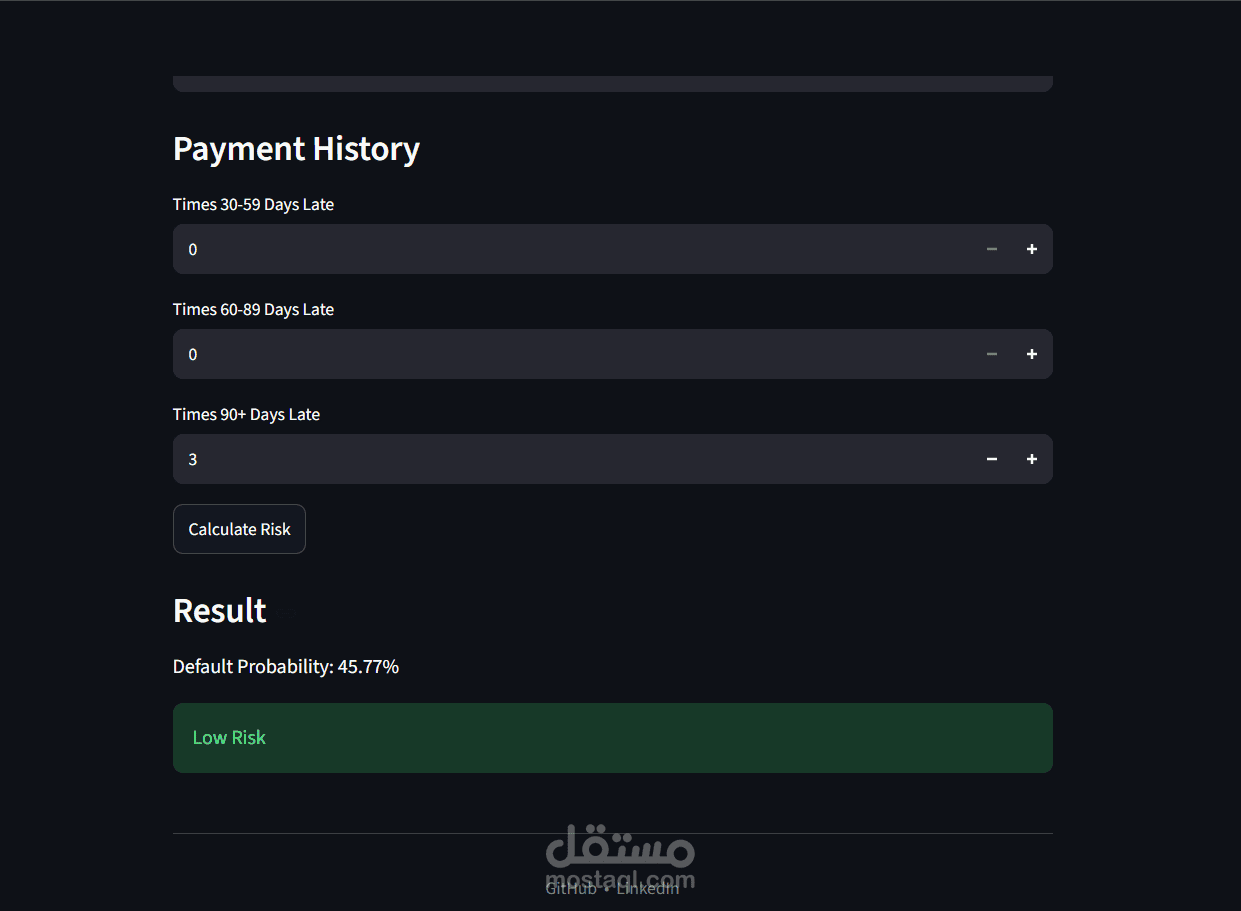
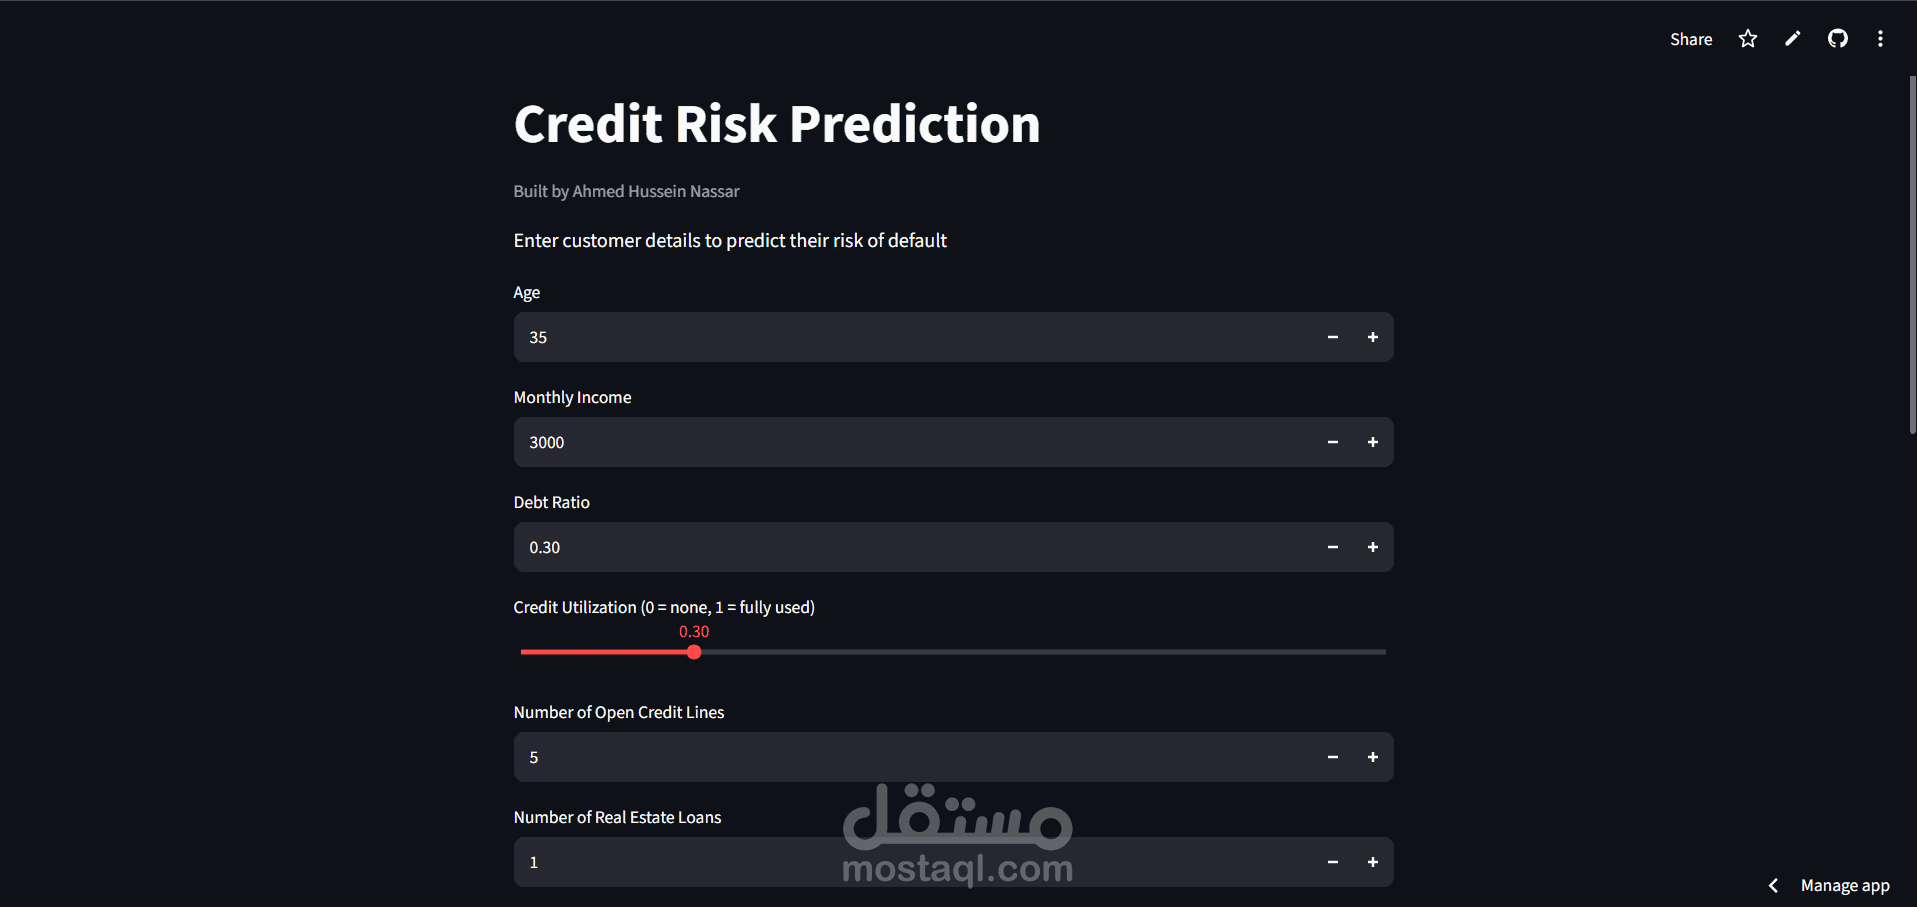
•Deployed the solution using FastAPI and Streamlit.