AI-Generated Speech Detection Using Traditional Speech Features and Machine Learning
تفاصيل العمل
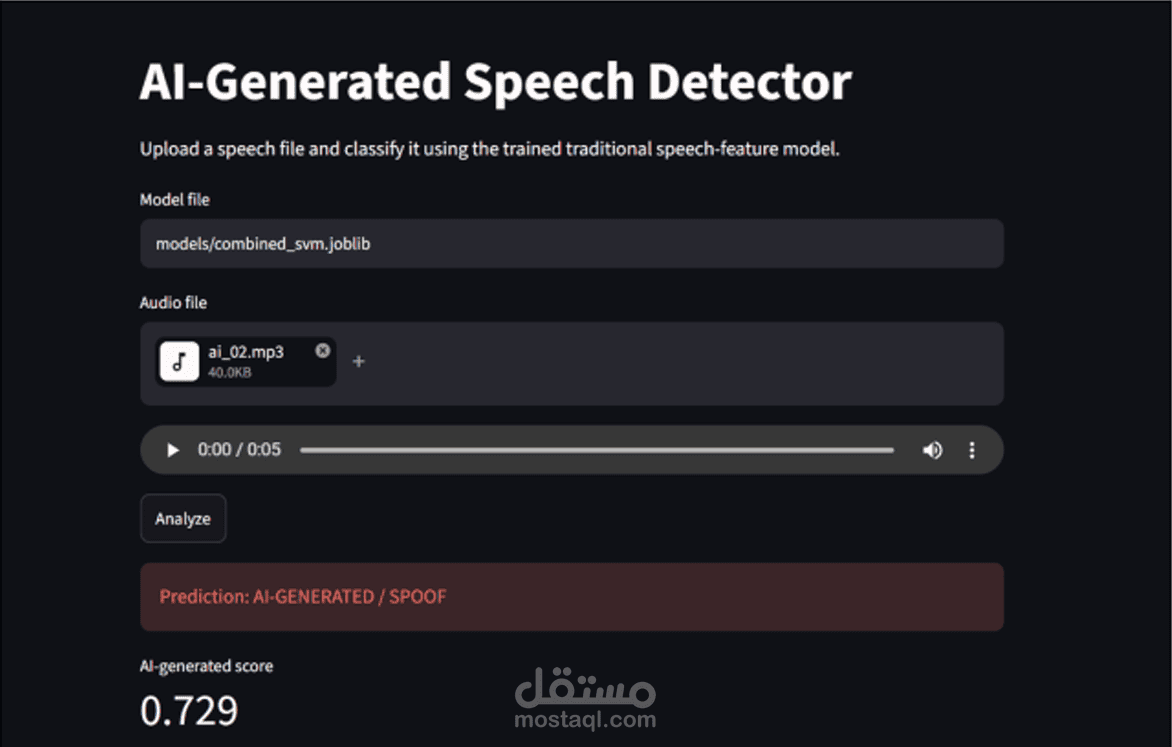
Developed an AI-based audio deepfake detection system designed to distinguish between real and synthetically generated speech. The project uses audio signal processing techniques to extract features such as MFCC and LFCC, which are then used to train and evaluate multiple machine learning models.
Several models were compared using performance metrics including Accuracy, F1 Score, ROC AUC, and Equal Error Rate (EER). The system also includes a prediction interface that allows users to upload an audio file and receive a classification result indicating whether the audio is genuine or fake.
The project was built using Python and machine learning libraries, with a focus on feature extraction, model evaluation, generalization testing, and practical deployment of the trained models.