Q-Learning GridWorld — Reinforcement Learning Agent
تفاصيل العمل
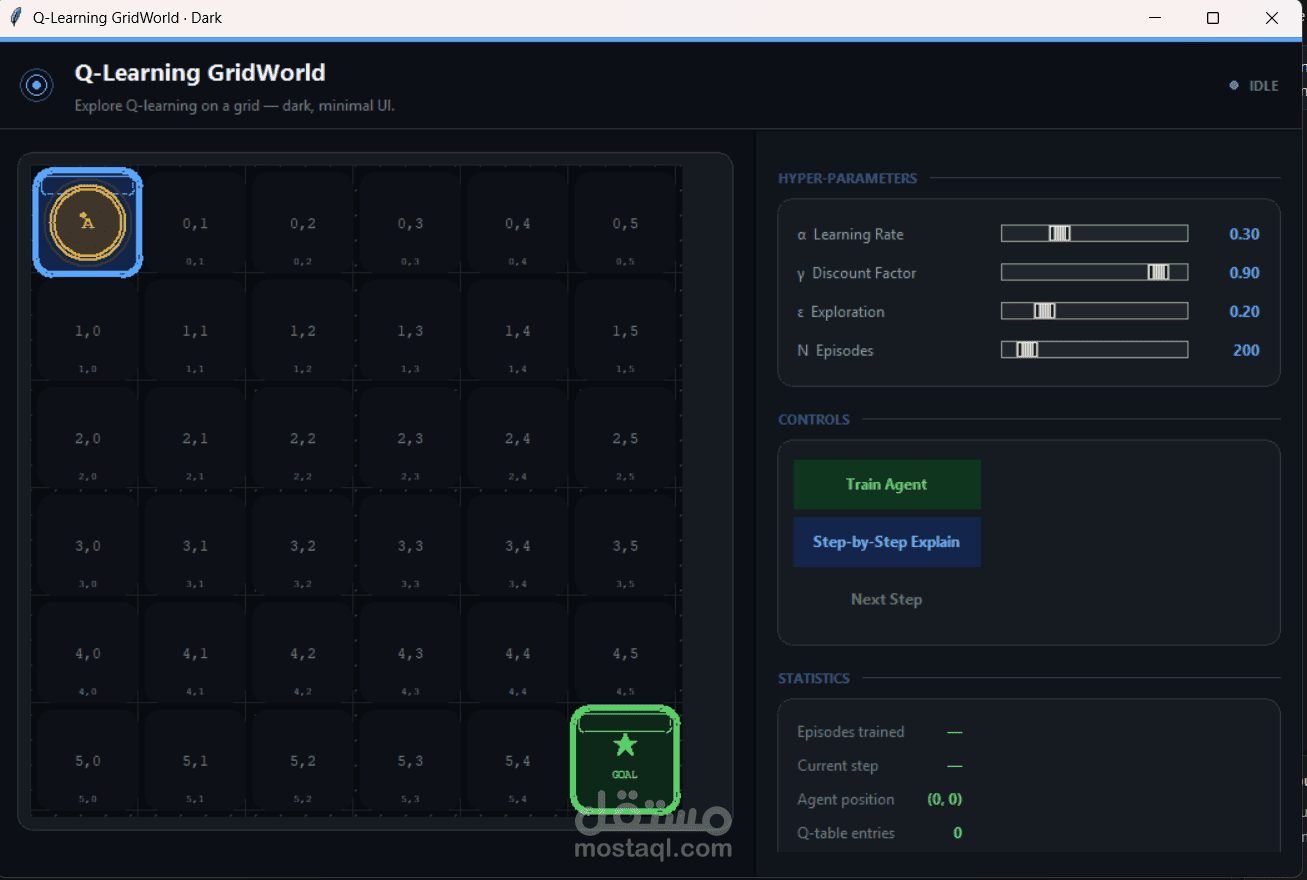
A Reinforcement Learning project that implements a Q-Learning agent to learn how to navigate a GridWorld environment and reach a target while optimizing its actions based on rewards.
The agent learns through trial and error by interacting with the environment, selecting actions, receiving rewards, and updating a Q-table based on the expected future rewards of different state-action pairs.
The project includes environment initialization, state and action handling, reward-based learning, exploration versus exploitation using an epsilon-greedy strategy, Q-table updates, and evaluation of the trained agent.
Training performance was analyzed through learning curves and the agent's behavior was evaluated after training to demonstrate how the learned policy improves navigation through the environment.
Technologies: Python, Reinforcement Learning, Q-Learning, NumPy, GridWorld, Q-Table, Epsilon-Greedy Exploration, and Data Visualization.