Fraud Detection System — Machine Learning Web Application
تفاصيل العمل
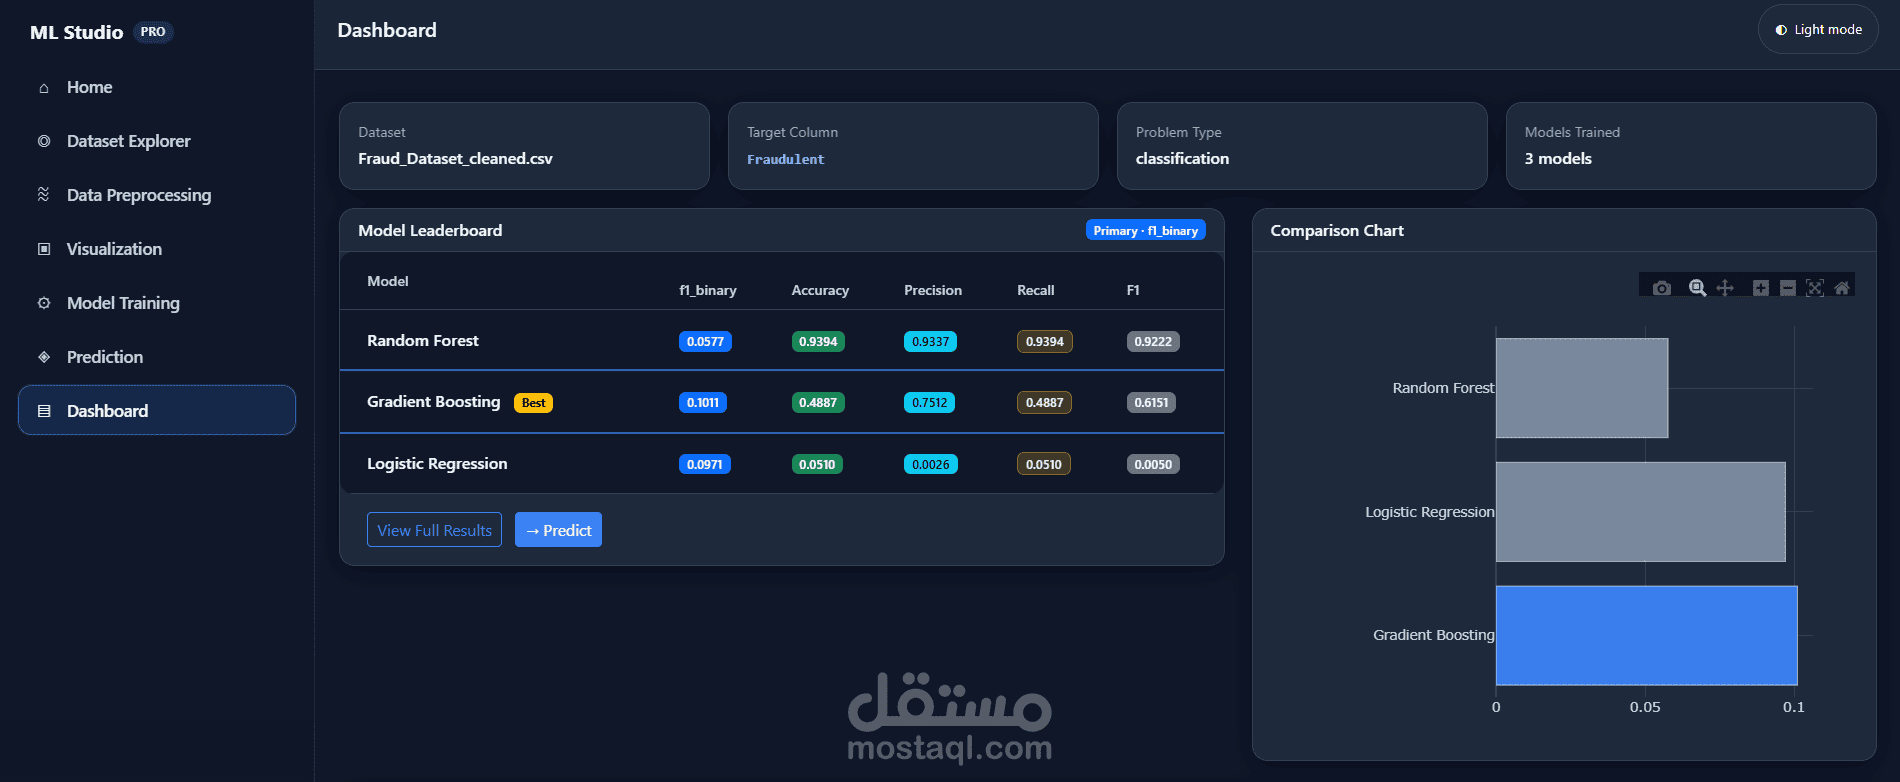
A machine learning web application for fraud detection, developed using Python, Flask, and scikit-learn.
The system allows users to upload tabular CSV datasets, explore and visualize the data, configure preprocessing, train and compare multiple machine learning models, and perform real-time predictions through a web interface.
The project includes a flexible preprocessing pipeline with missing-value imputation, feature scaling, categorical encoding, outlier handling, feature engineering, and SMOTE for imbalanced classification data. Multiple ensemble approaches were implemented, including Random Forest, Voting, Bagging, and Boosting models.
The application also provides interactive Plotly dashboards for dataset exploration, correlation analysis, missing-value visualization, model comparison, and evaluation metrics such as Accuracy, Precision, Recall, F1-score, and ROC AUC.
The system uses saved model artifacts with joblib and applies the same preprocessing pipeline during inference to maintain consistency between training and prediction.
Technologies: Python, Flask, scikit-learn, XGBoost, imbalanced-learn, Pandas, NumPy, Plotly, Matplotlib, Seaborn, Bootstrap, Jinja2, JavaScript, and joblib