Paper Research Assistant AI
تفاصيل العمل
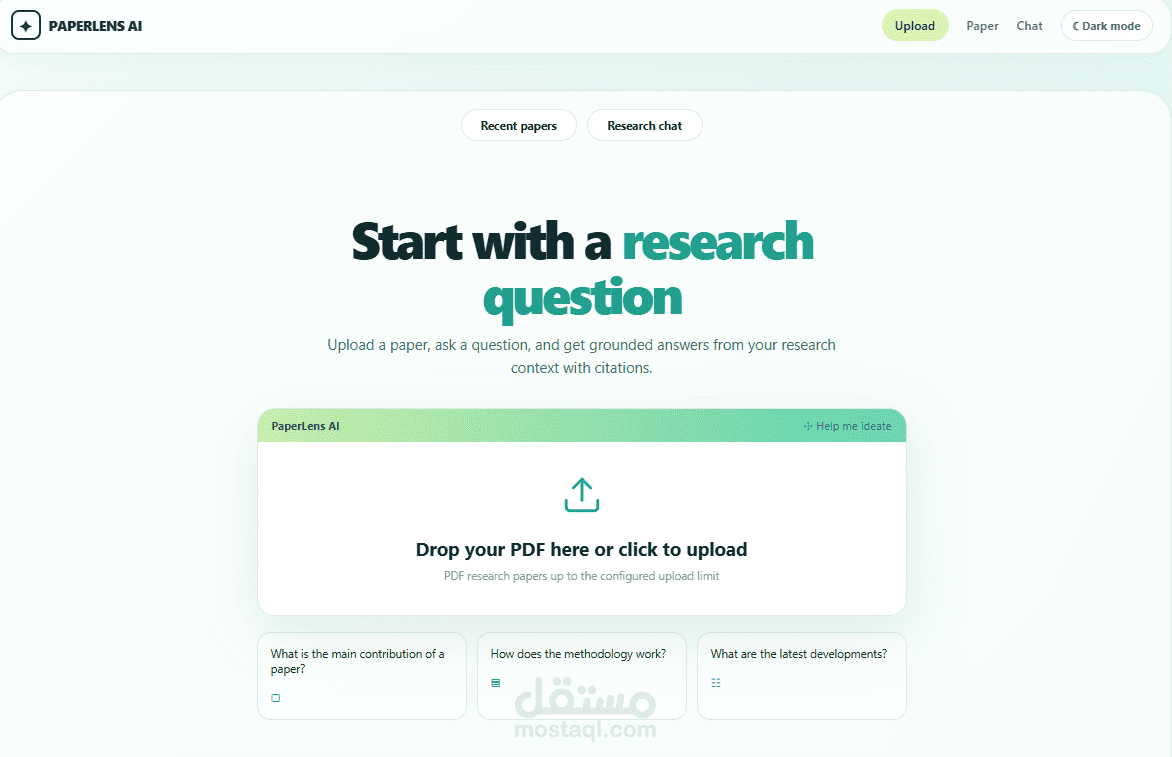
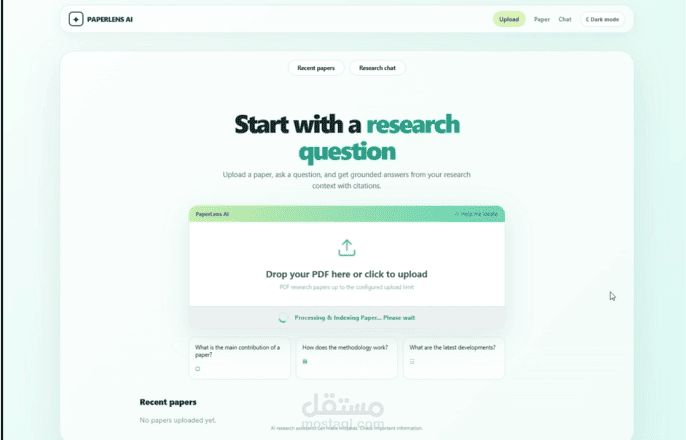
An AI-powered scientific paper analysis and question-answering system designed to help researchers process and understand academic papers.
My role in the project was **Document Intelligence / Document Processing Developer**. I was responsible for PDF text extraction and preprocessing, content cleaning, section and heading detection, document chunking, and metadata preservation.
The system processes scientific papers and transforms unstructured PDF content into structured, meaningful chunks that can be used for downstream AI analysis and question answering.
**Technologies:** Python, FastAPI, PyMuPDF, NLP, PDF Processing, Document Intelligence.