NYC Taxi Big Data Analytics & Trip Duration Prediction
تفاصيل العمل
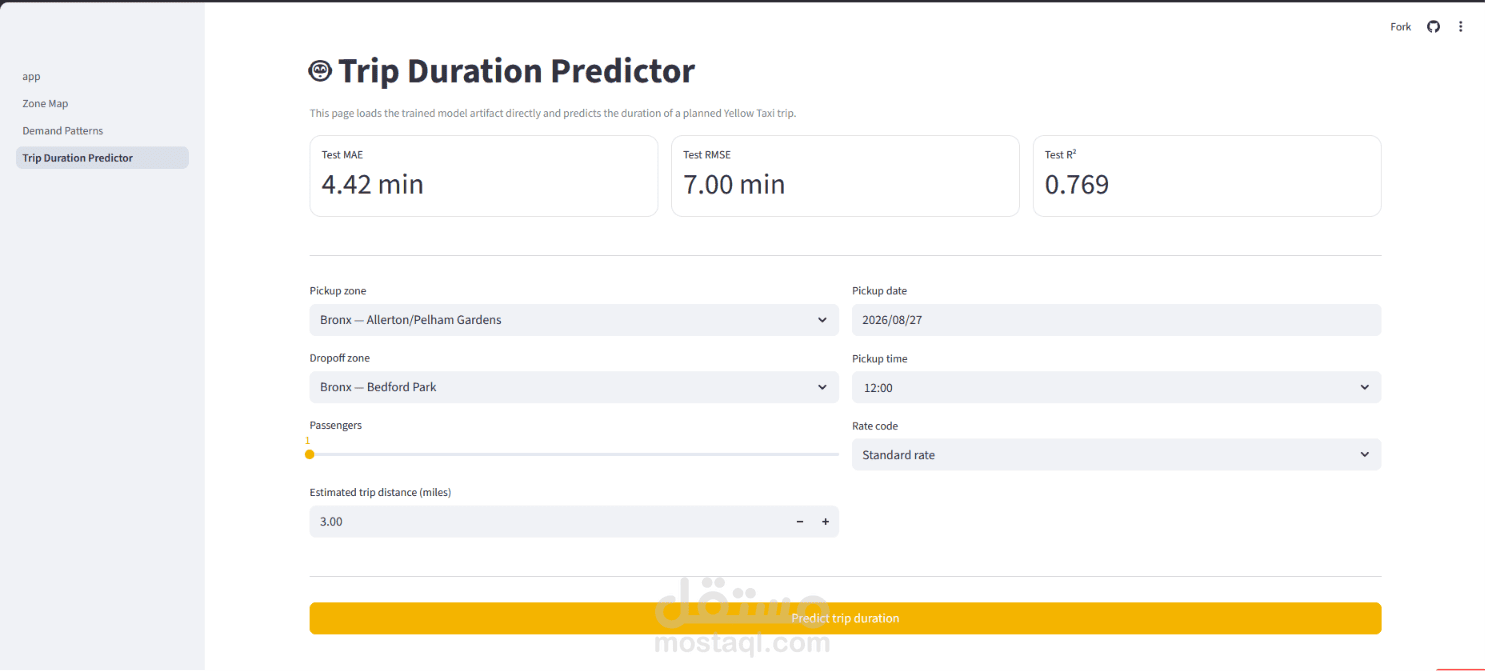
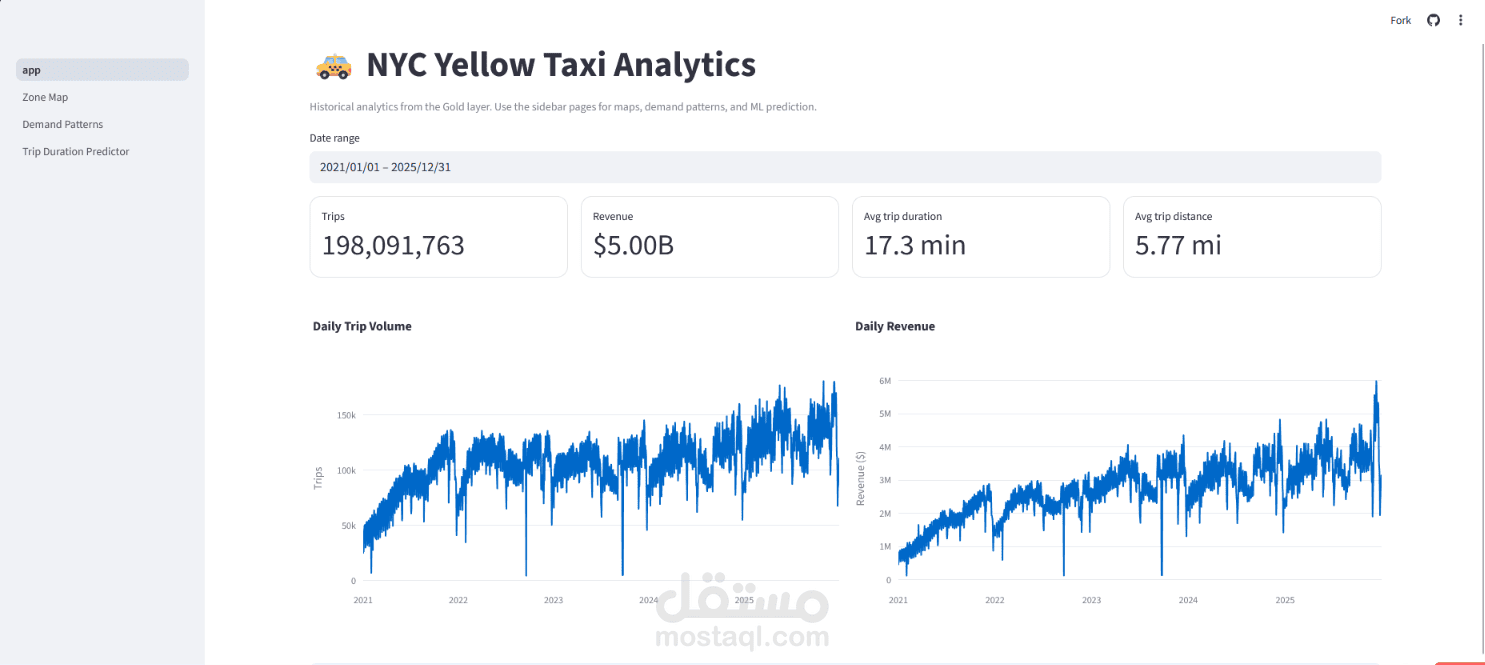
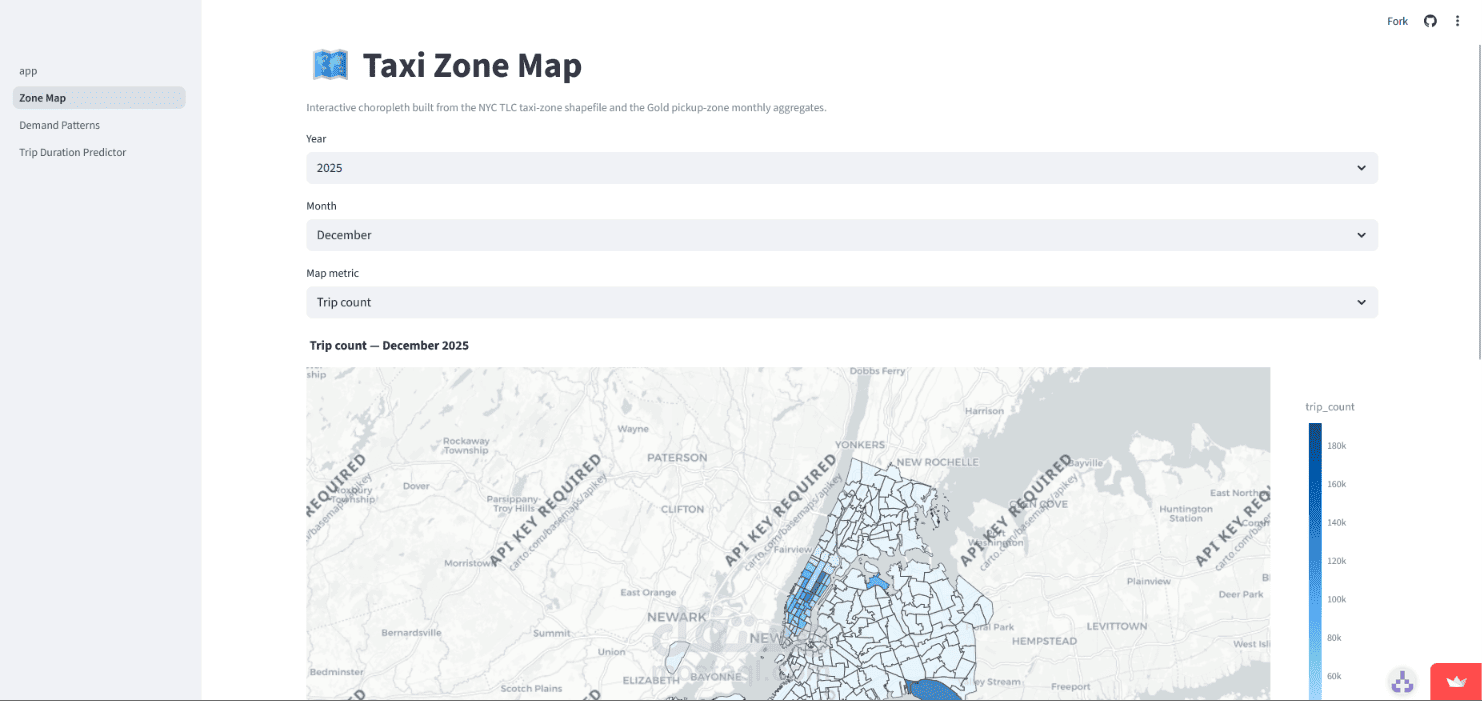
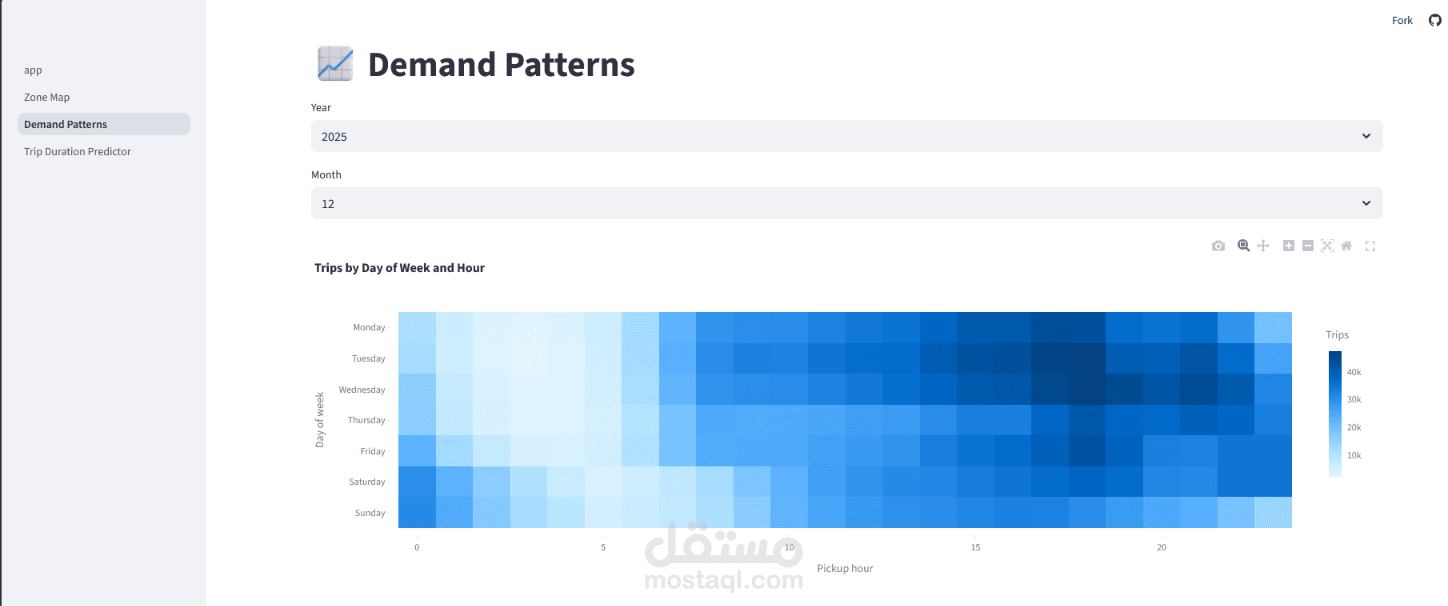
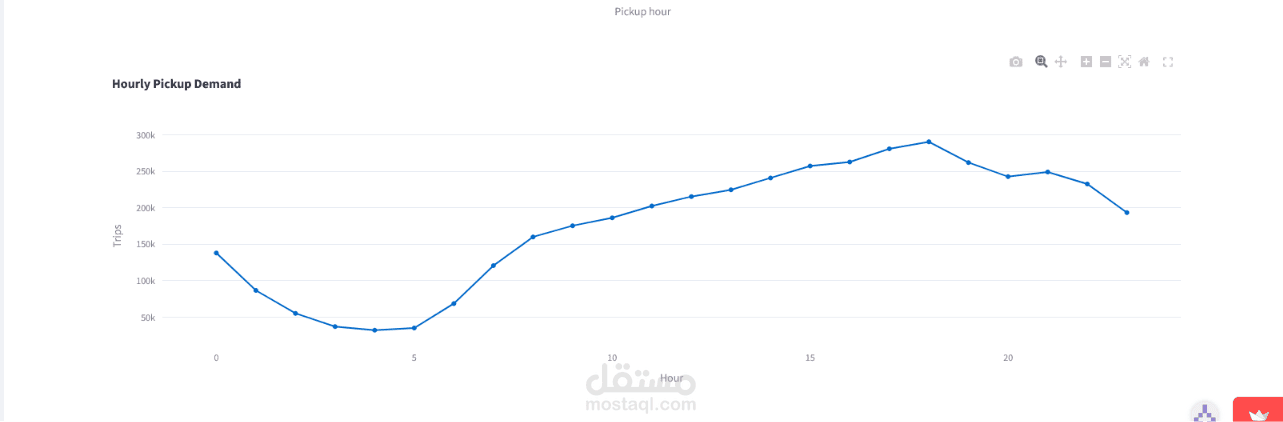
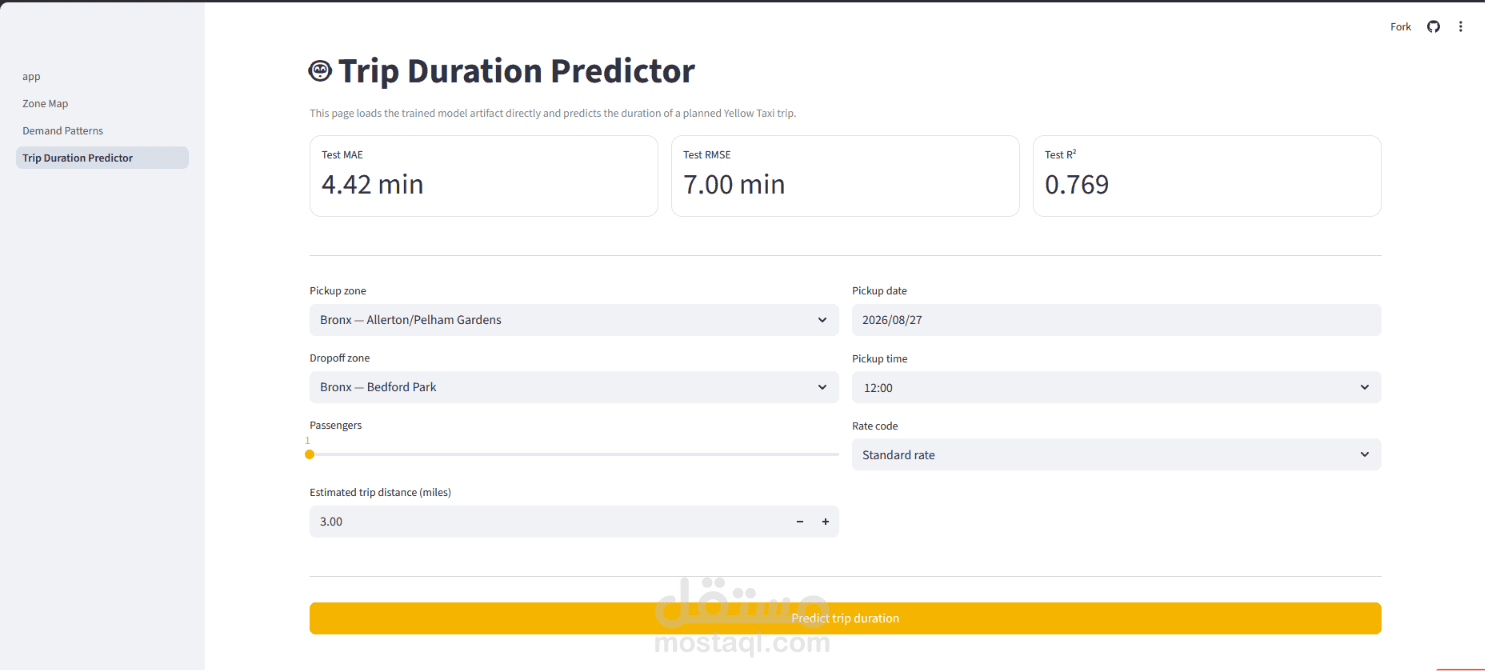
Data Source: ingested NYC Yellow Taxi monthly Parquet files spanning 2021-01 → 2025-12.
● Batch Pipeline: loaded 59 Batch Months into HDFS Bronze Batch.
● Streaming Pipeline: streamed the 2025-12 Streaming Month through a Kafka Producer → Kafka → Spark Structured
Streaming → HDFS Bronze Streaming.
● Bronze → Silver Processing: merged both Bronze branches in Spark Bronze → Silver, applying schema normalization,
conservative cleaning, batch/stream union, taxi-zone enrichment, and derived time/duration fields to produce HDFS
Silver Trips.
● Analytics Branch: built Spark Silver → Gold to generate Gold serving tables and a dashboard export.
● Machine Learning Branch: built an ML Dataset Builder, ran Spark model comparison, produced an ML train/test export,
and packaged a portable .pkl model.
● Final Application: combined the dashboard export and the portable .pkl model into a Streamlit app delivering analytics,
map visualization, and ML prediction.