Automated Data Cleaning, Transformation & Validation Pipeline in Python
تفاصيل العمل
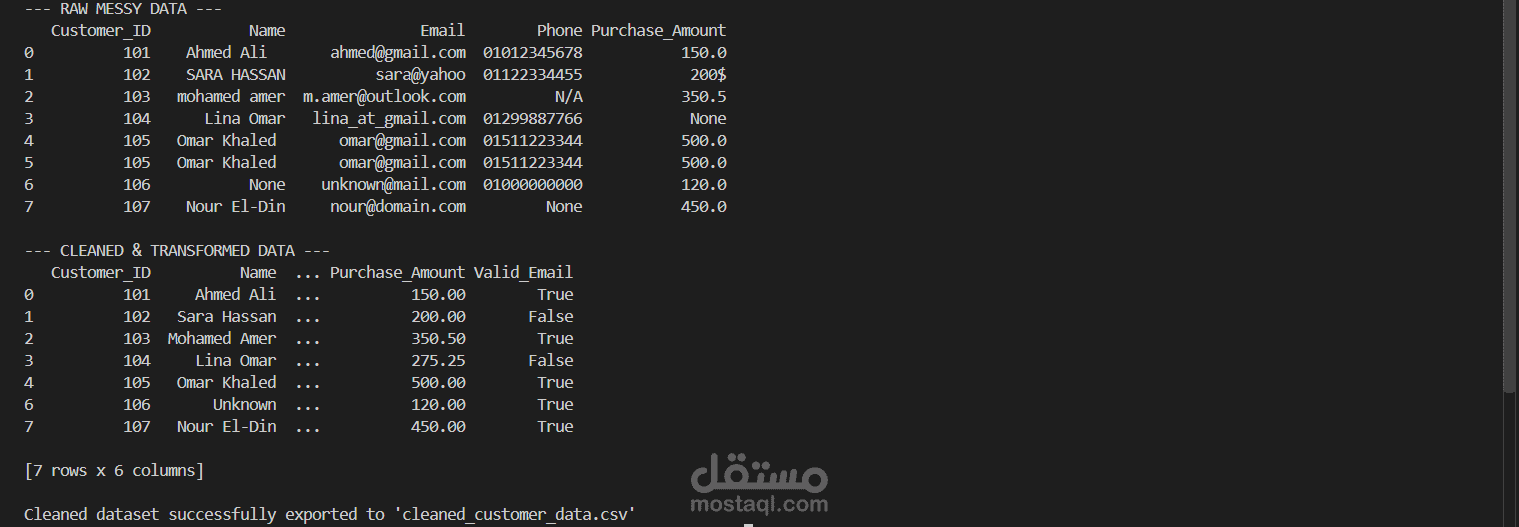
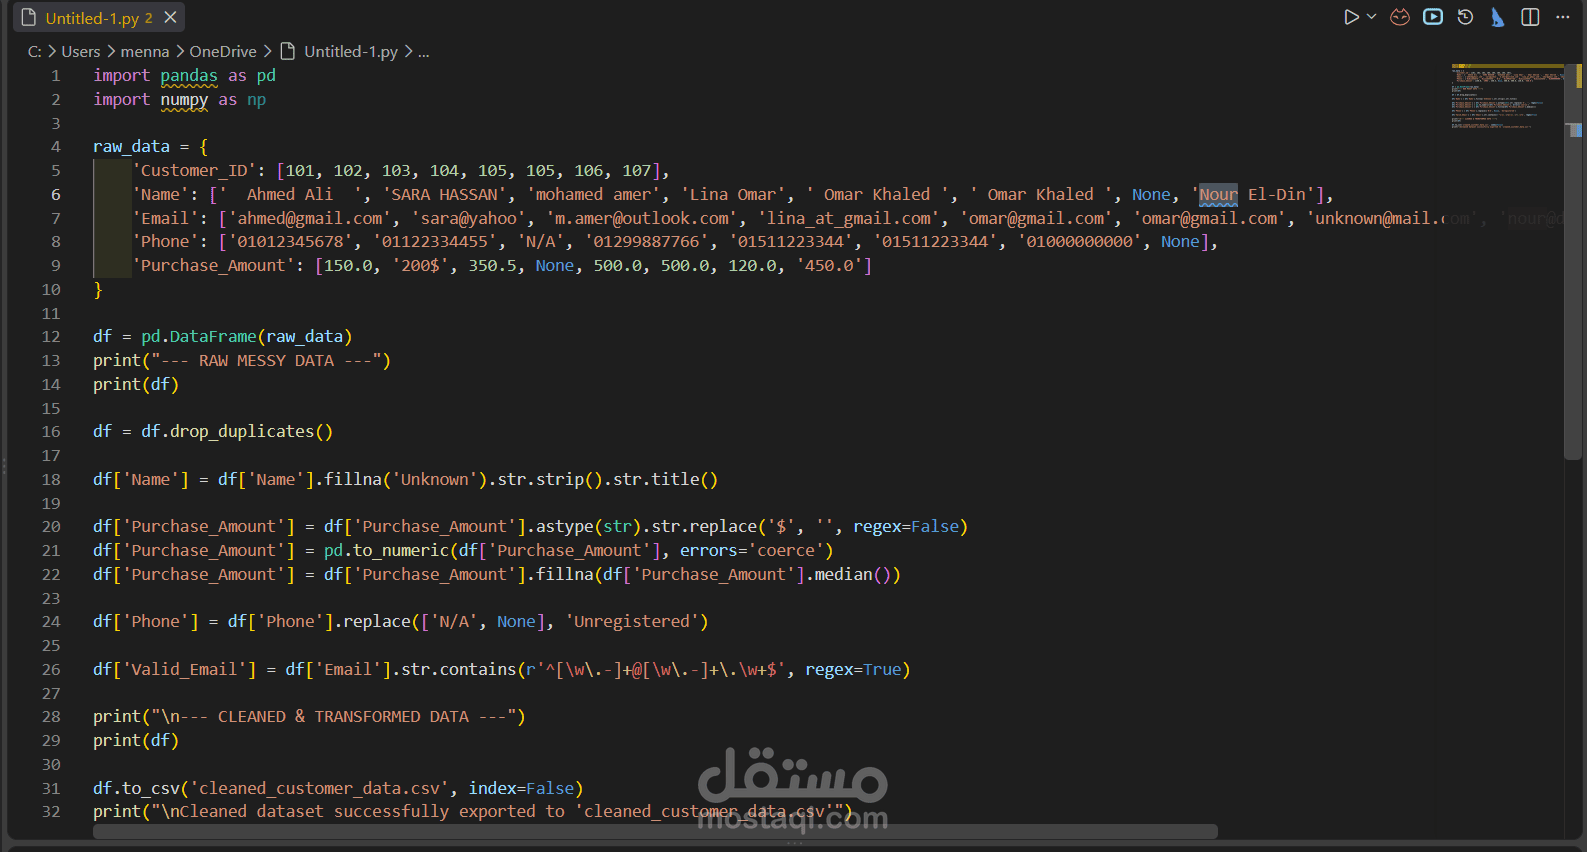
Engineered an automated Python data processing pipeline using Pandas to clean, validate, and standardize raw business datasets:
Deduplication & String Standardization: Stripped whitespace, corrected capitalization, and removed duplicate customer records automatically.
Data Type Casting & Value Imputation: Parsed messy string currencies into clean floating-point numbers and handled missing values using median statistical imputation.
Validation Checks: Implemented Regex pattern matching to identify and flag invalid email formats and missing contact numbers before exporting to CSV/Database.