End-to-End Machine Learning Pipeline & Predictive Analytics
تفاصيل العمل
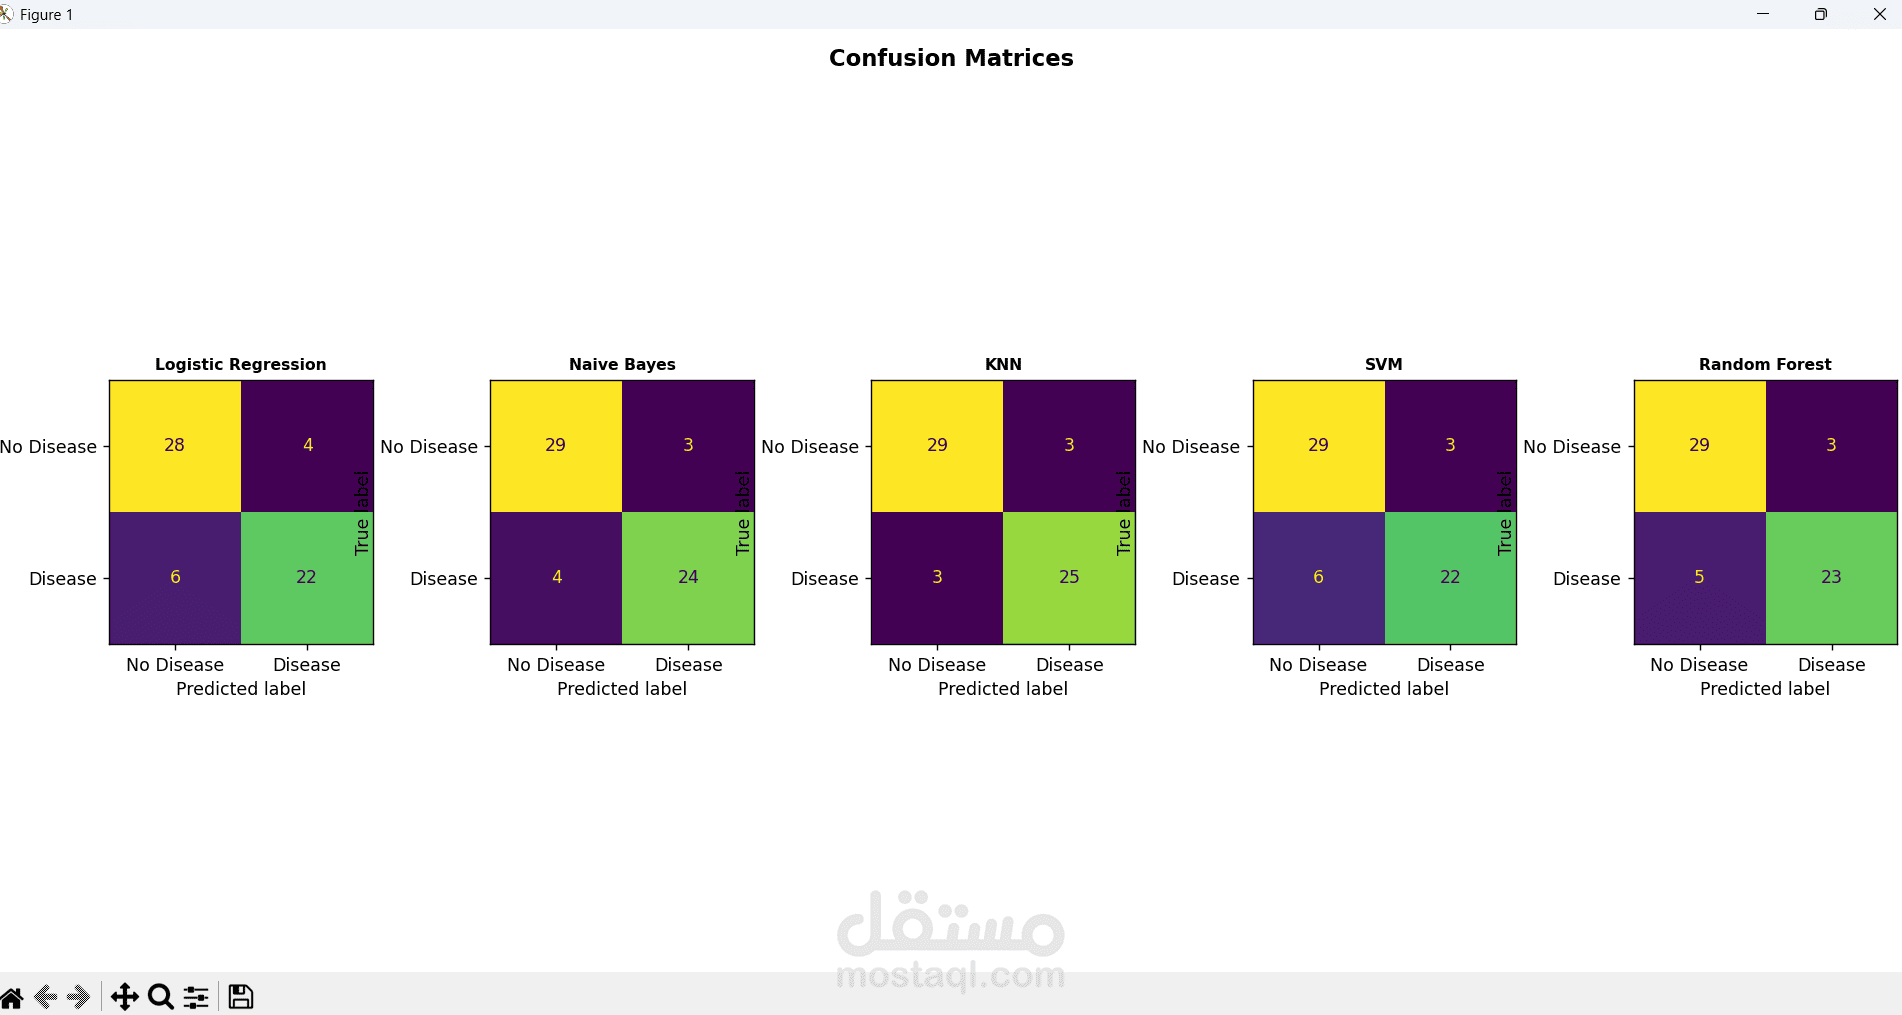
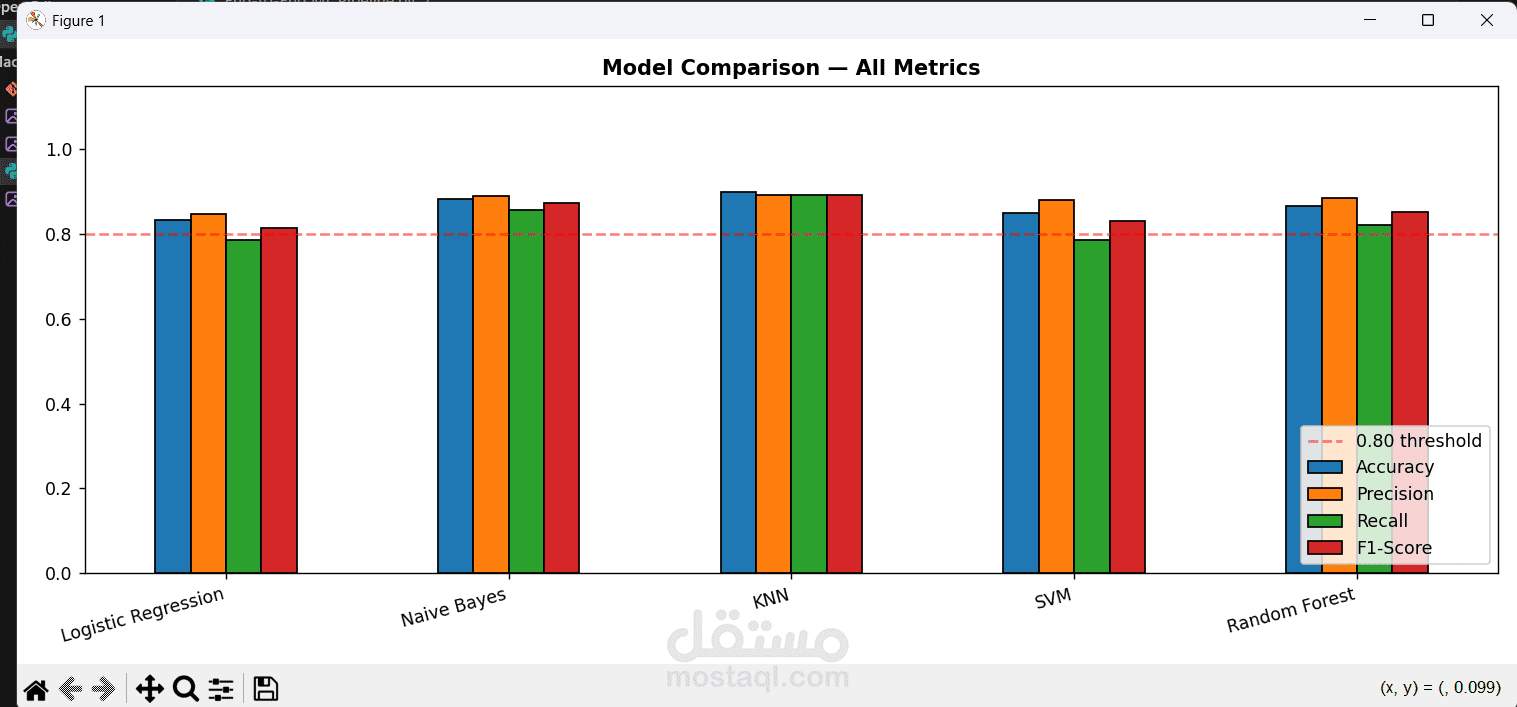
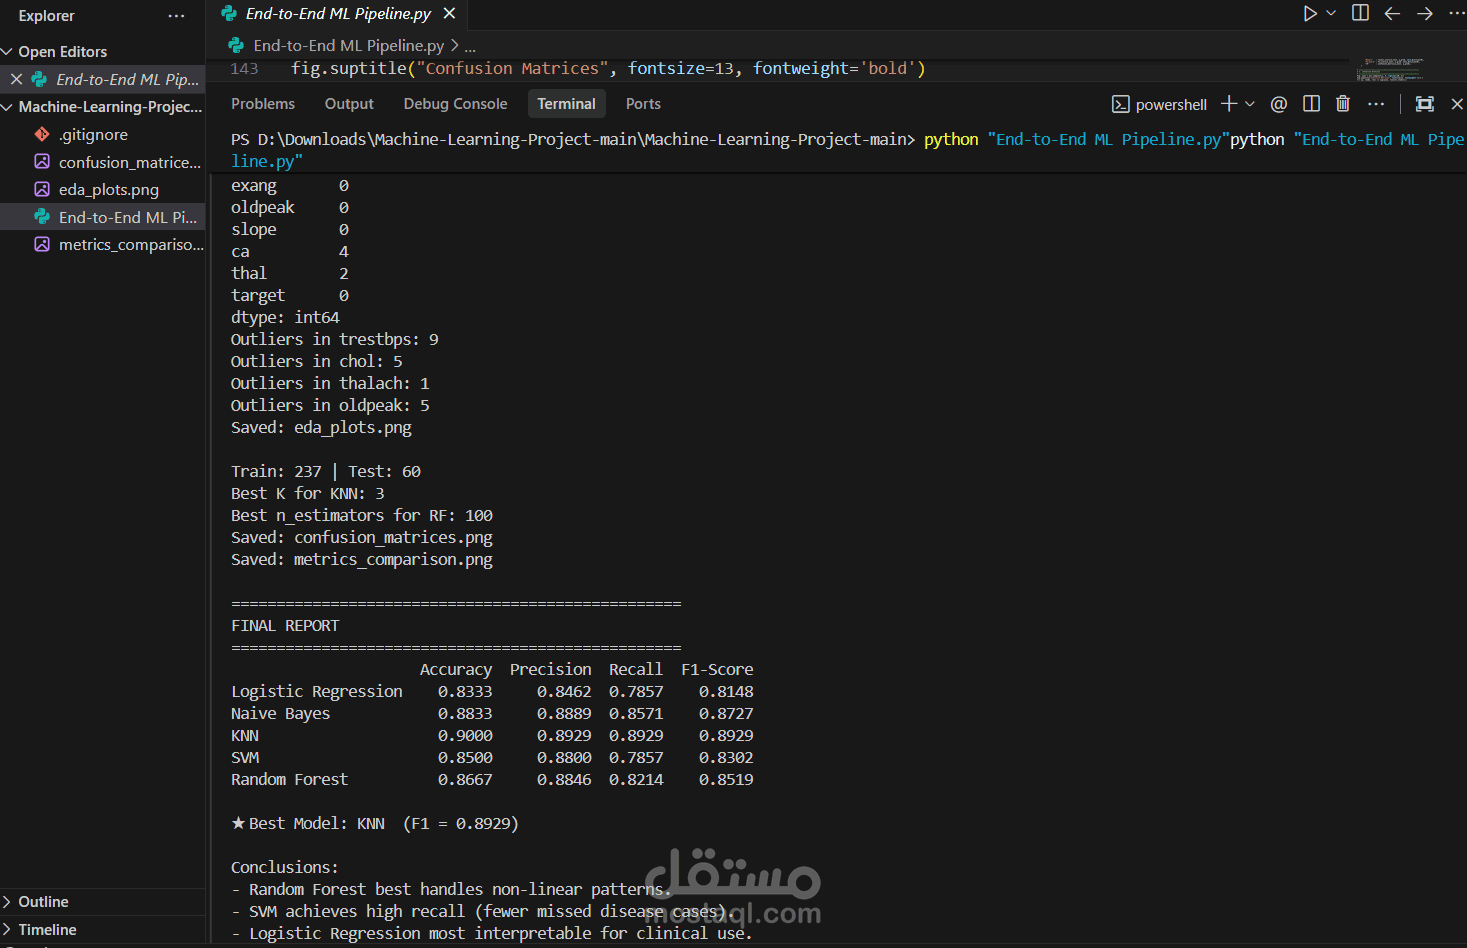
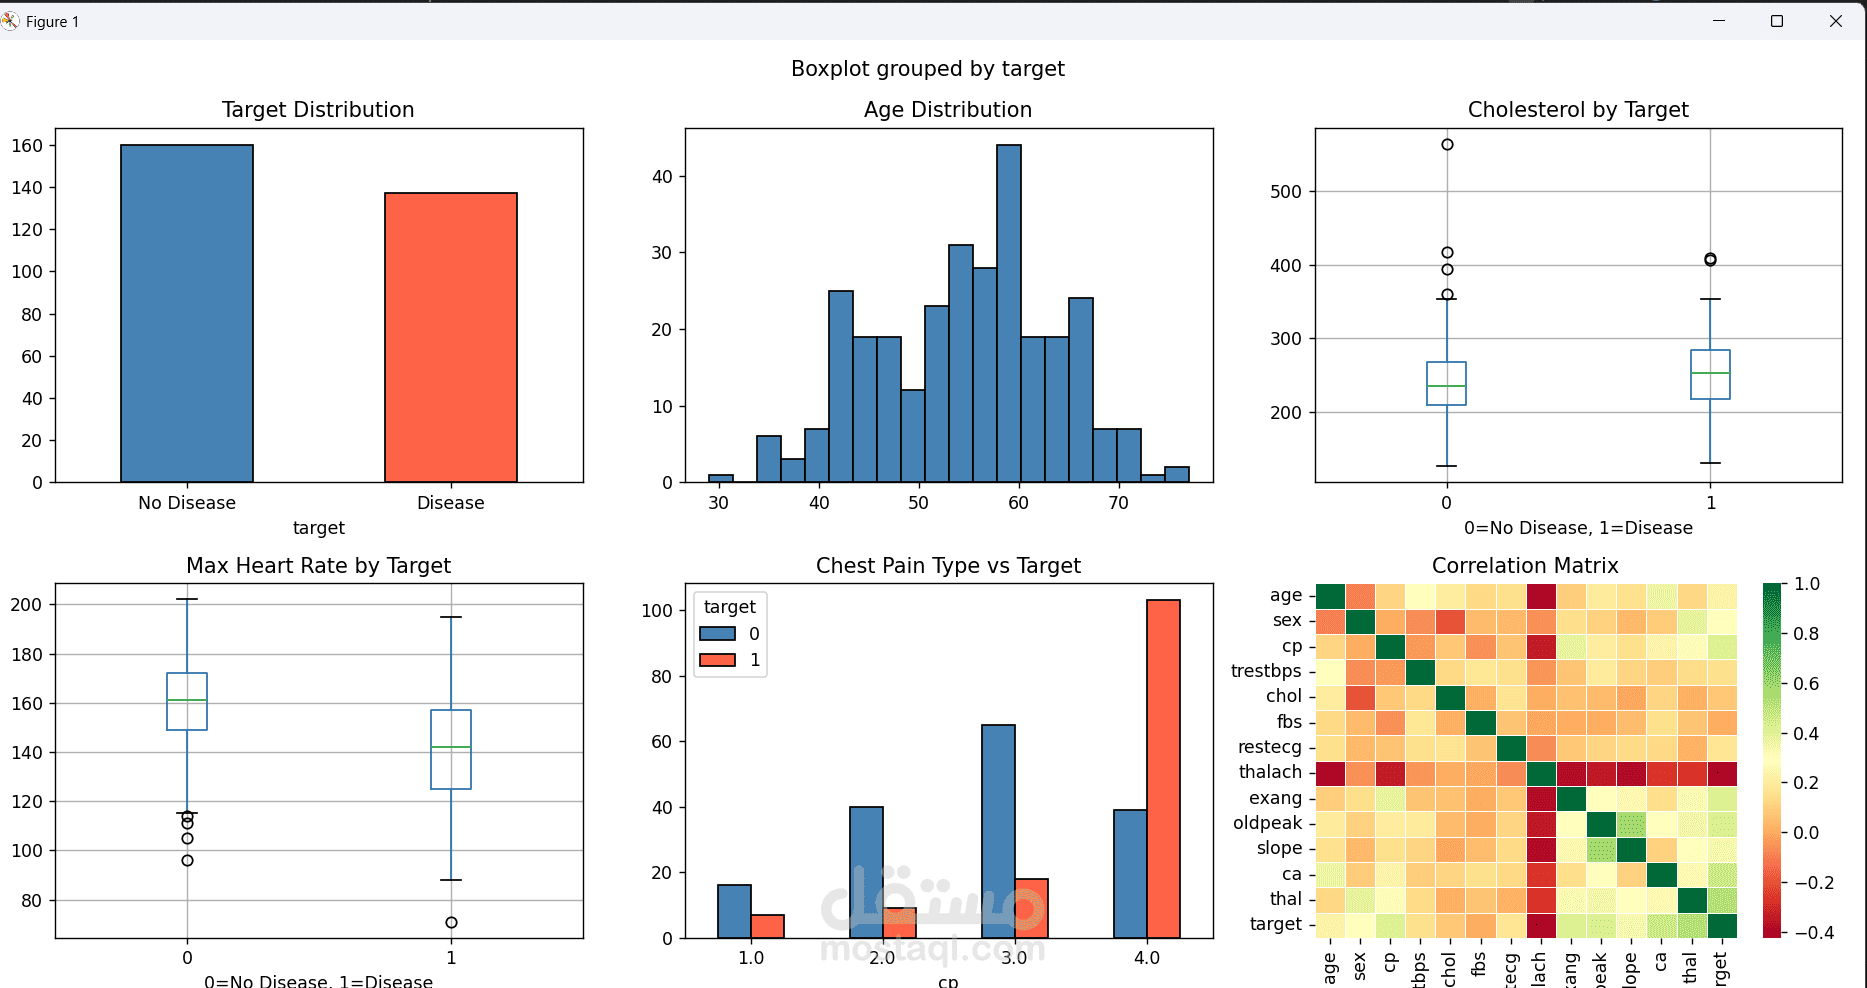
A comprehensive machine learning project engineered to build, evaluate, and deploy predictive models using industry-standard ML workflows and statistical data analysis. The project demonstrates strong mathematical foundations, feature engineering capabilities, and clean data processing pipelines.
Technical Highlights:
- Data Preprocessing & Exploratory Data Analysis (EDA): Cleaned, normalized, and handled missing values across complex datasets, utilizing statistical distributions and correlation matrices to extract actionable insights.
- Feature Engineering & Selection: Built optimized feature pipelines, handled categorical encodings, scaled numerical features, and applied dimensionality reduction techniques to maximize predictive power.
- Model Training & Evaluation: Implemented supervised learning algorithms, evaluated performance using industry metrics (Precision, Recall, F1-score, ROC-AUC, RMSE), and performed systematic hyperparameter tuning using cross-validation.
- Modular & Production-Ready Code: Structured the ML pipeline using clean object-oriented Python practices, ensuring modularity, reproducibility, and seamless integration with backend APIs and production environments.
Technologies & Tools Used:
Python, NumPy, Pandas, Scikit-Learn, Matplotlib, Seaborn, Machine Learning, Statistical Analysis, Data Preprocessing, Feature Engineering.