Automated Sentiment Analysis Pipeline (Database + ML)
تفاصيل العمل
Automated Sentiment Analysis Pipeline (Database + Machine Learning)
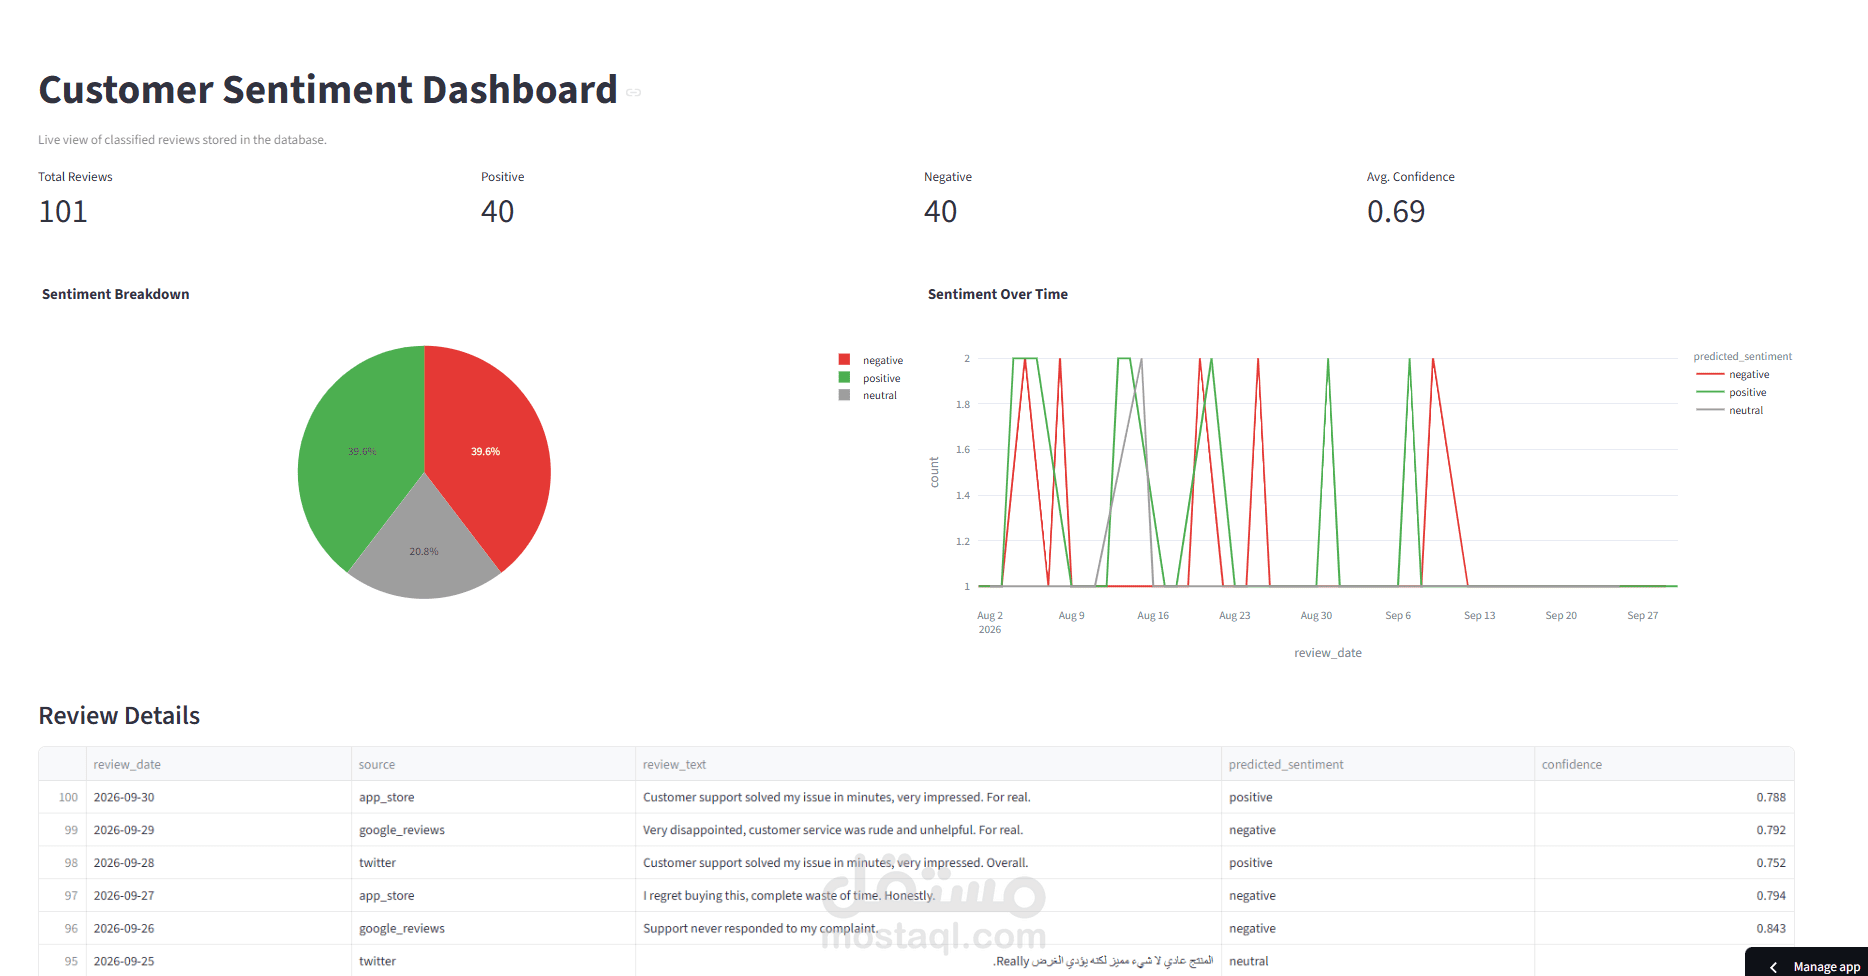
I built an end-to-end system that automatically reads customer reviews and comments and classifies them as positive, negative, or neutral — turning scattered, unstructured feedback into a searchable, data-driven view of customer sentiment.
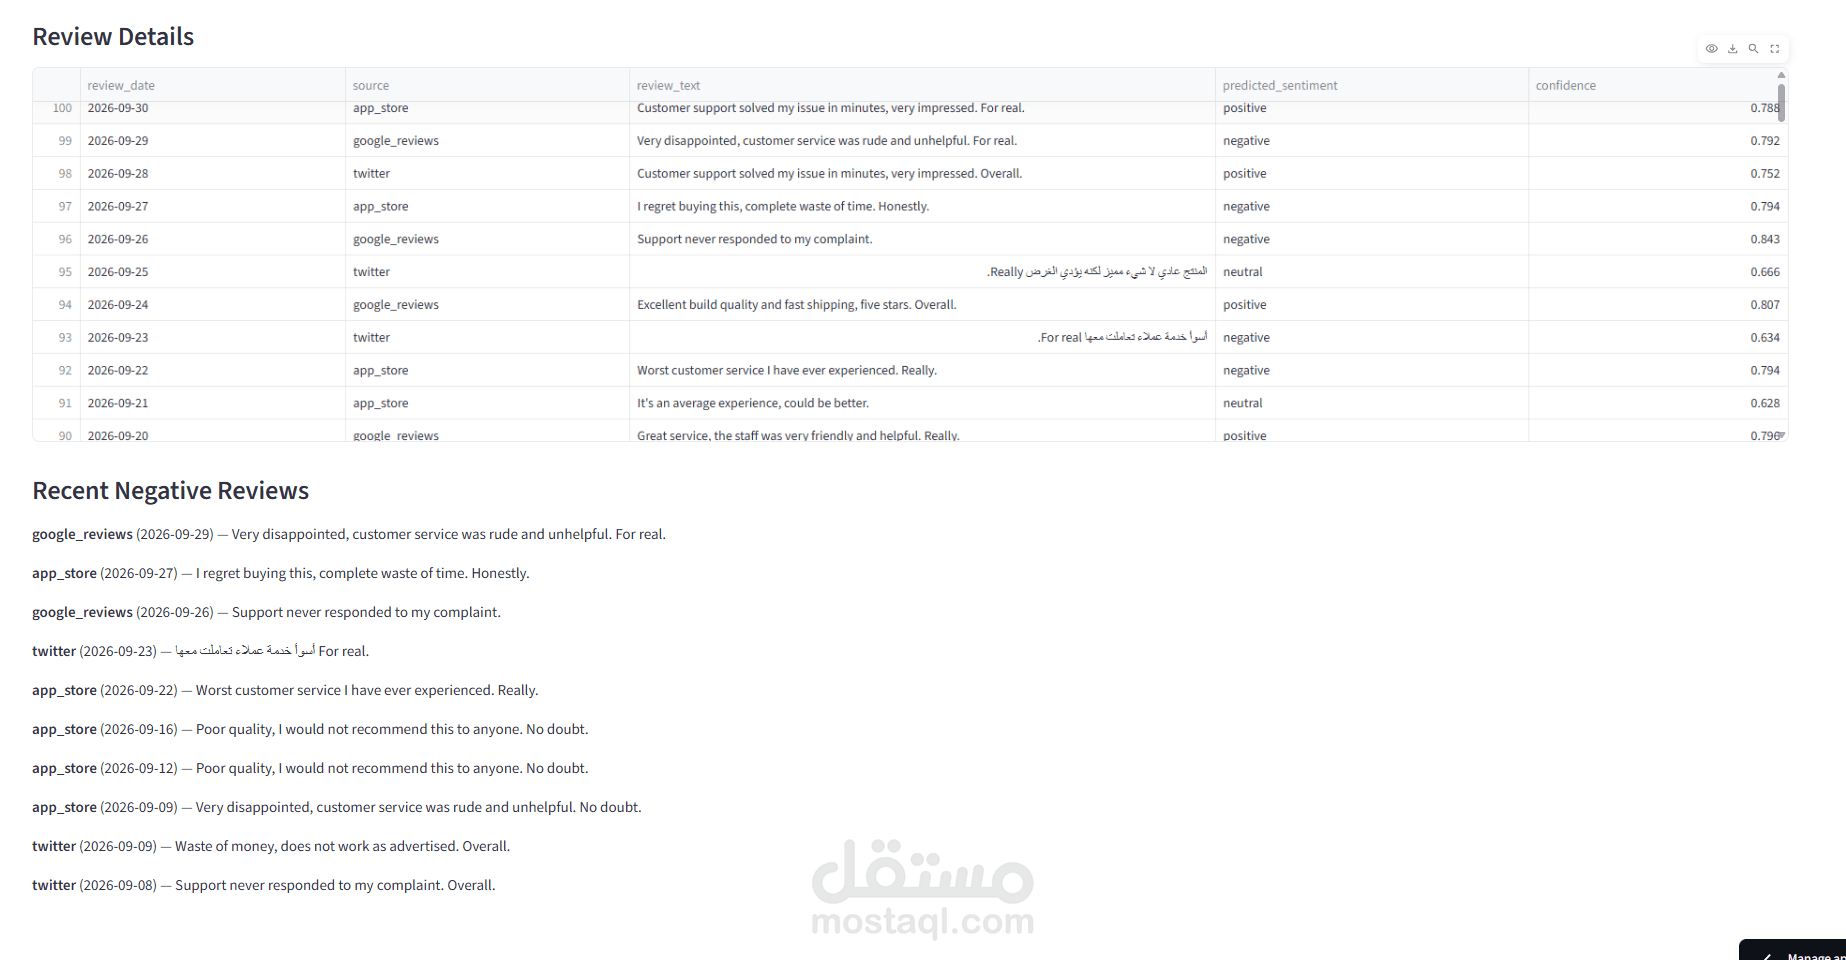
The pipeline collects reviews (from a CSV export, scraped source, or live API), cleans and processes the text, and runs it through a trained machine learning model (TF-IDF + Logistic Regression, achieving 95% accuracy in testing) to predict sentiment with a confidence score. Every review and its prediction are stored in a structured SQL database, making it easy to query trends over time, filter by source or date, and track how customer opinion shifts.
The system also generates an automatic report: a sentiment distribution chart and a breakdown of the most common keywords appearing in negative reviews — so businesses can immediately spot recurring complaints without reading every comment manually.
What's included:
Data cleaning and preprocessing pipeline
Trained ML sentiment classifier with evaluation report
Structured database schema for reviews and predictions
Automated classification of new incoming data
Visual report (sentiment trends + top complaint keywords)
Tech stack: Python, scikit-learn, SQL (PostgreSQL/MySQL/SQLite), Pandas, Matplotlib
This project can be scaled up with live data scraping, a scheduled automation job, an interactive dashboard, or Arabic-language sentiment support (AraBERT) for Arabic-speaking markets.