End-to-End Penguin Species Classification & Machine Learning Pipeline
تفاصيل العمل
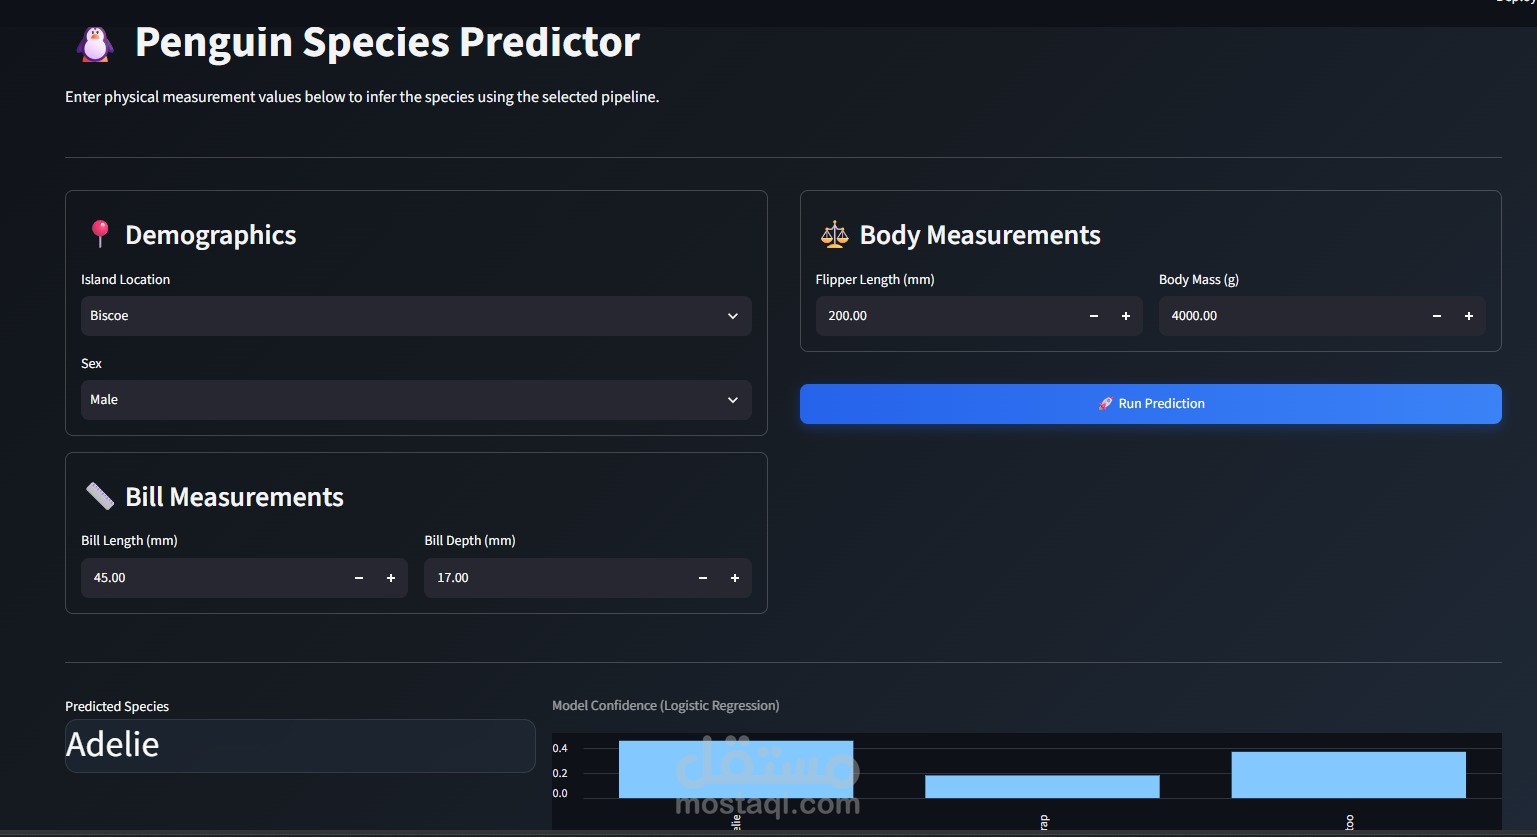
Developed a comprehensive end-to-end machine learning classification pipeline to predict and categorize penguin species based on morphological measurements and physical attributes.
Key Responsibilities & Workflow
Data Preprocessing & EDA: Performed rigorous data cleaning, exploratory data analysis, and feature handling on the penguin dataset (penguin_species_dataset.ipynb, penguin_species_dataset.xlsx) to ensure data integrity and prepare optimal features for model training.
Model Development & Training: Built and trained multiple classification models—including Logistic Regression, Random Forest, and Support Vector Machine (SVM)—packaged into robust deployment pipelines (logreg_pipeline.pkl, knn_pipeline.pkl, svc_pipeline.pkl).
Evaluation & Performance: Evaluated model efficacy utilizing detailed Confusion Matrices (confusion_matrix_logistic_regression.png, confusion_matrix_random_forest.png, confusion_matrix_support_vector_machine.png, three_confusion_matrices.png) to compare classification accuracy and error rates across algorithms.