Book Store Price & Availability Scraper (Python)
تفاصيل العمل
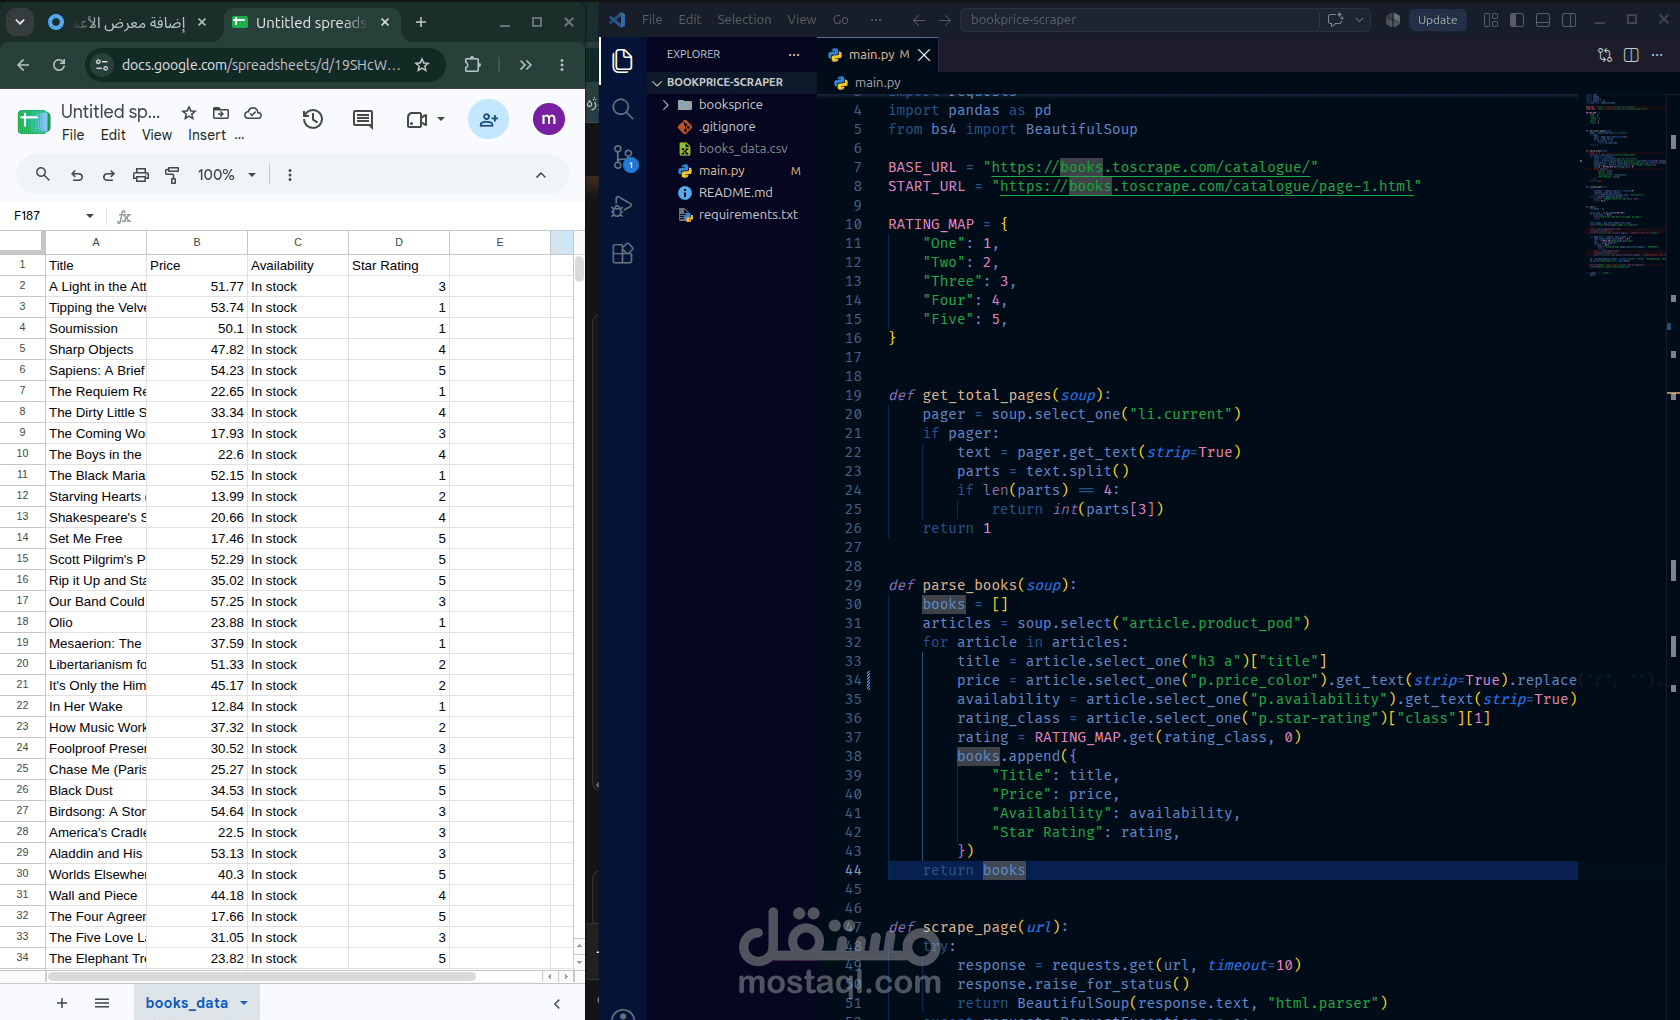
A Python web scraper that automatically extracts book data from an e-commerce demo site. It navigates through all 50 pages of the catalog, collecting the title, price, availability status, and star rating for each book, then saves everything into a clean, structured CSV file.
The scraper includes proper error handling — if a page fails to load due to a timeout or connection issue, it logs the error and continues with the next page instead of crashing, ensuring the process completes reliably even under unstable network conditions. A short randomized delay between requests is used to avoid overloading the target server.
Tech stack: Python, Requests, BeautifulSoup4, Pandas.