Dynamic Infinite-Scroll Scraper (Python, Playwright)
تفاصيل العمل
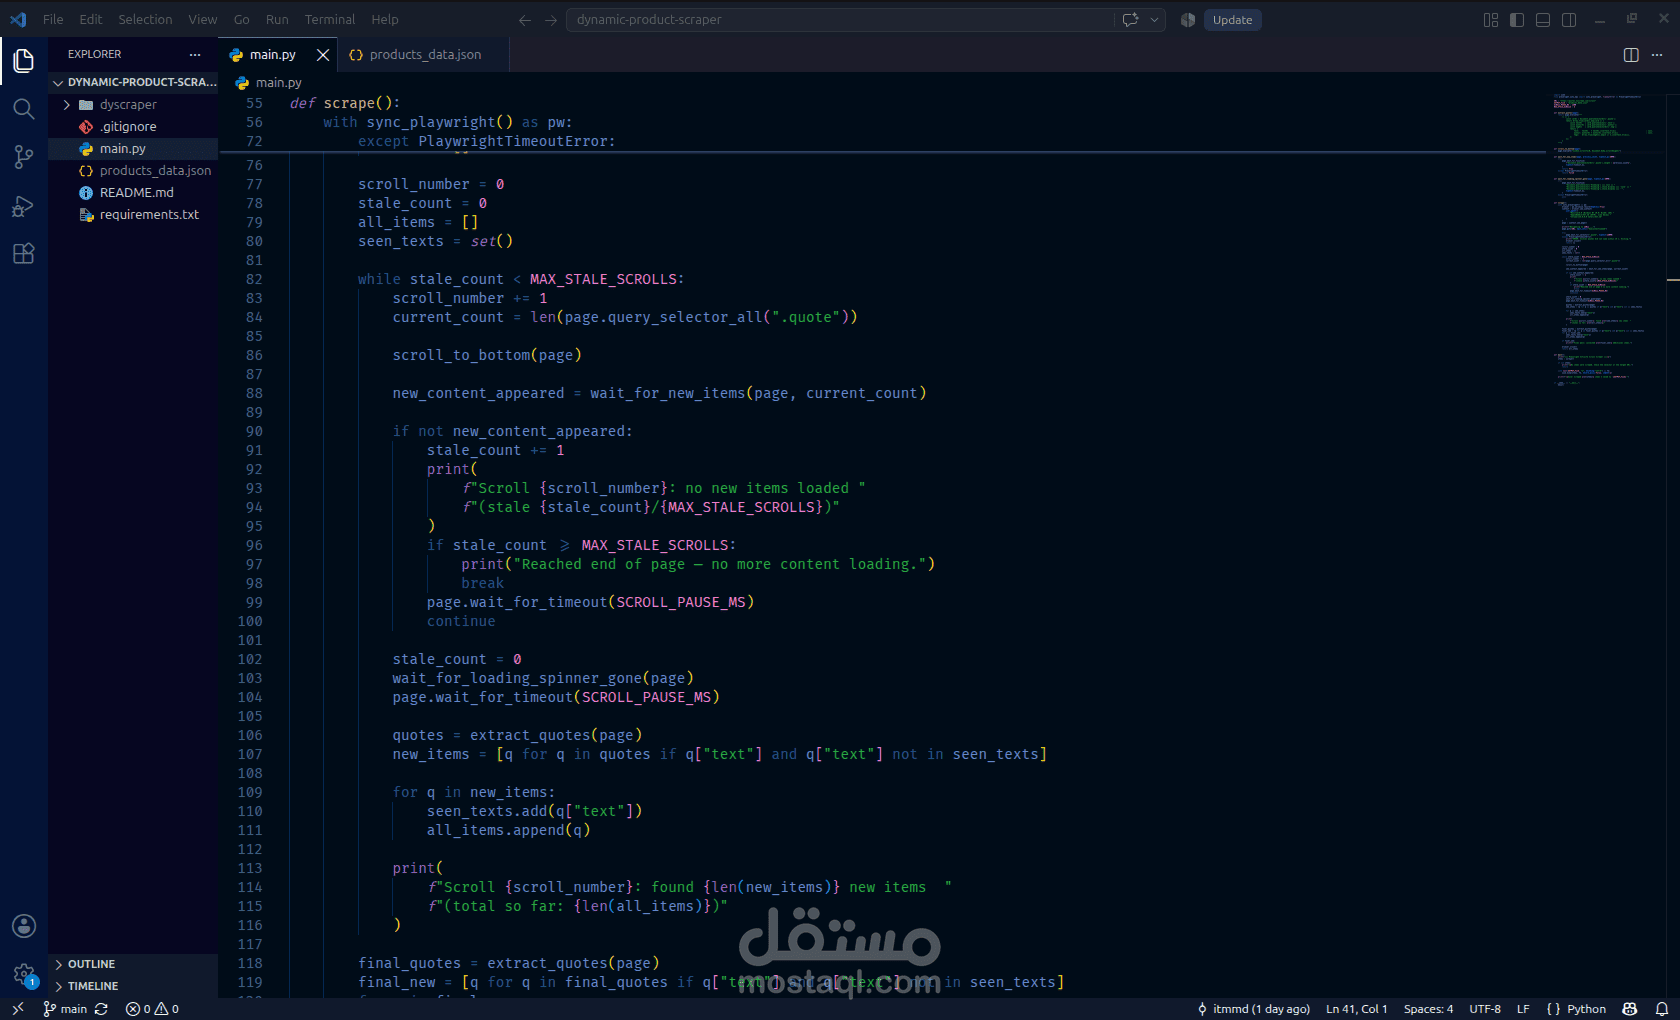
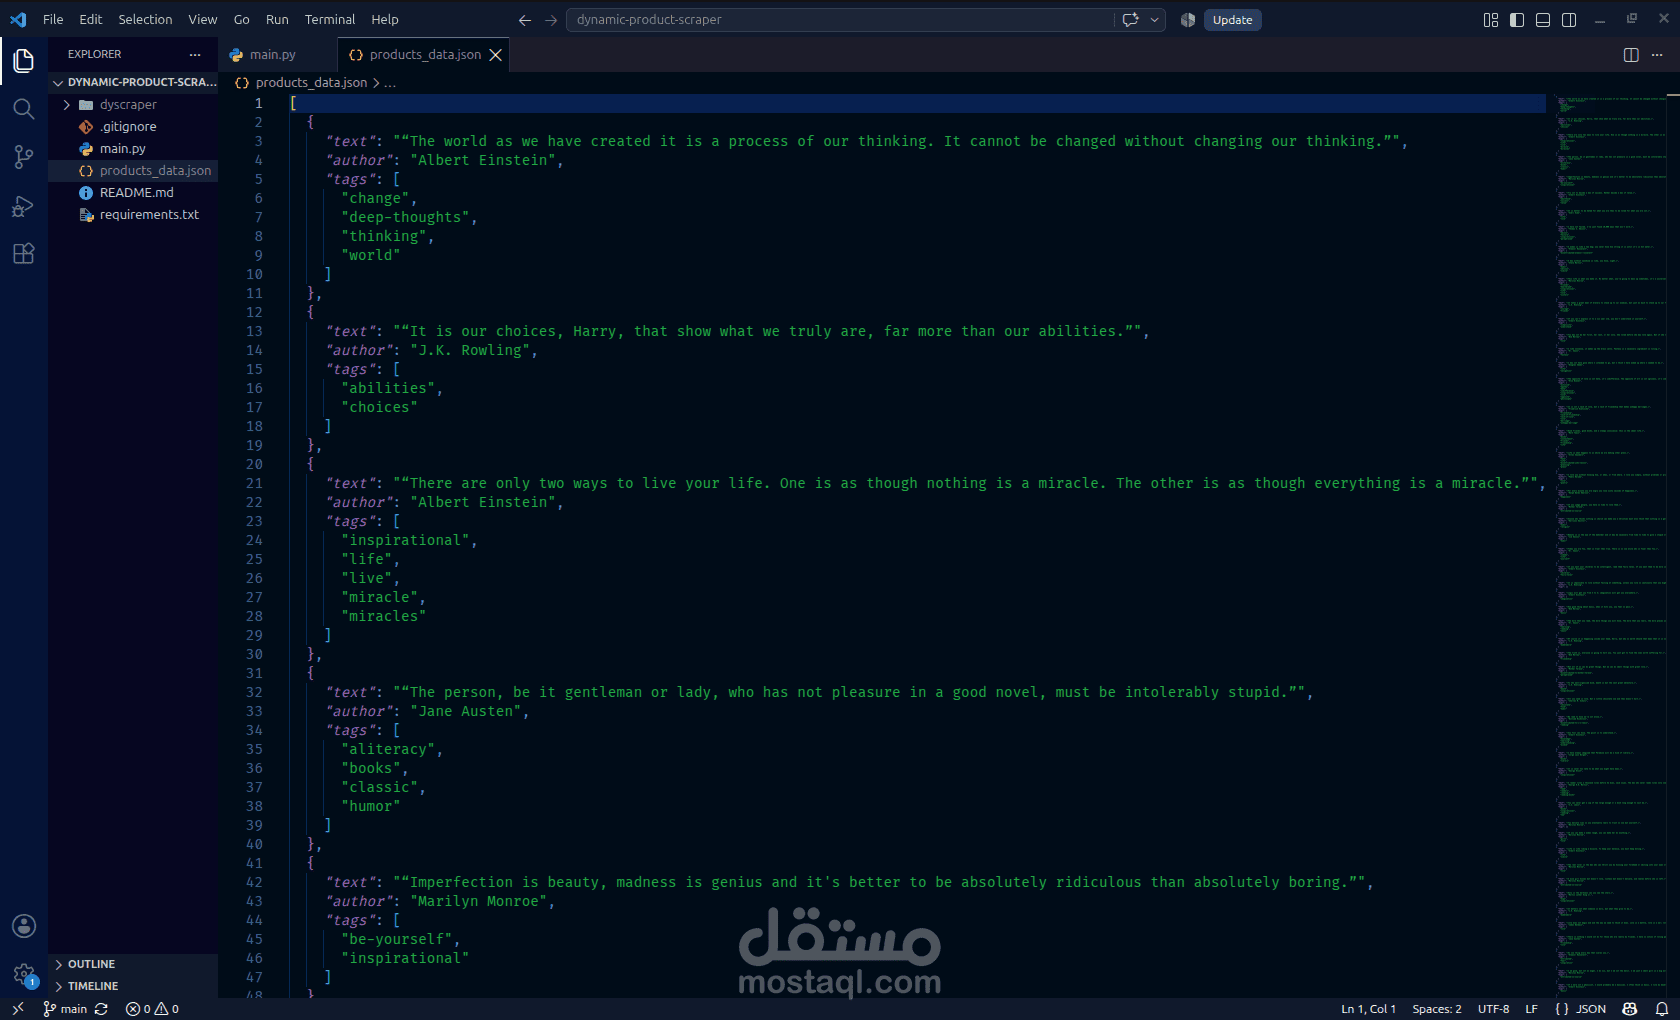
A Python scraper built with Playwright to extract data from a JavaScript-rendered page that loads content dynamically through infinite scroll. Since the content isn't available in the initial HTML, the scraper drives a real headless browser, scrolls the page, and waits for new elements to appear before extracting them.
It tracks previously seen items to avoid duplicates and automatically detects when it has reached the end of the page (no new content loading after several attempts). The collected data is saved as a structured JSON file.
Tech stack: Python, Playwright.