Scraped Data REST API (Python, FastAPI, SQLite)
تفاصيل العمل
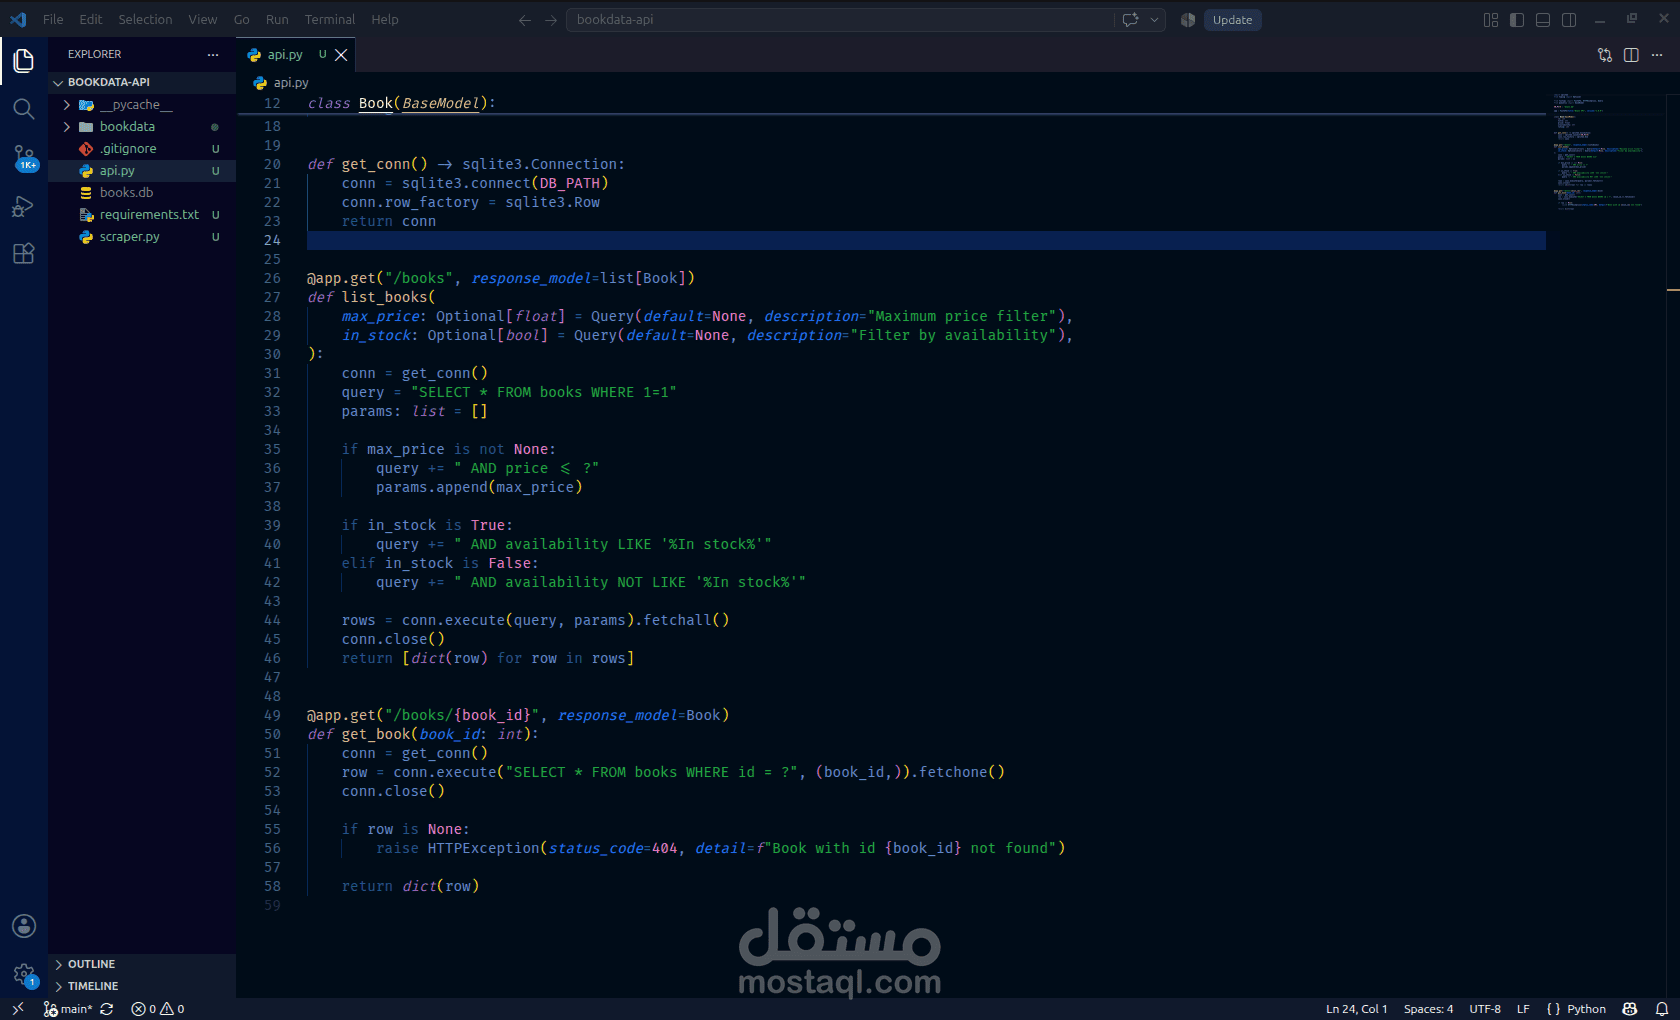
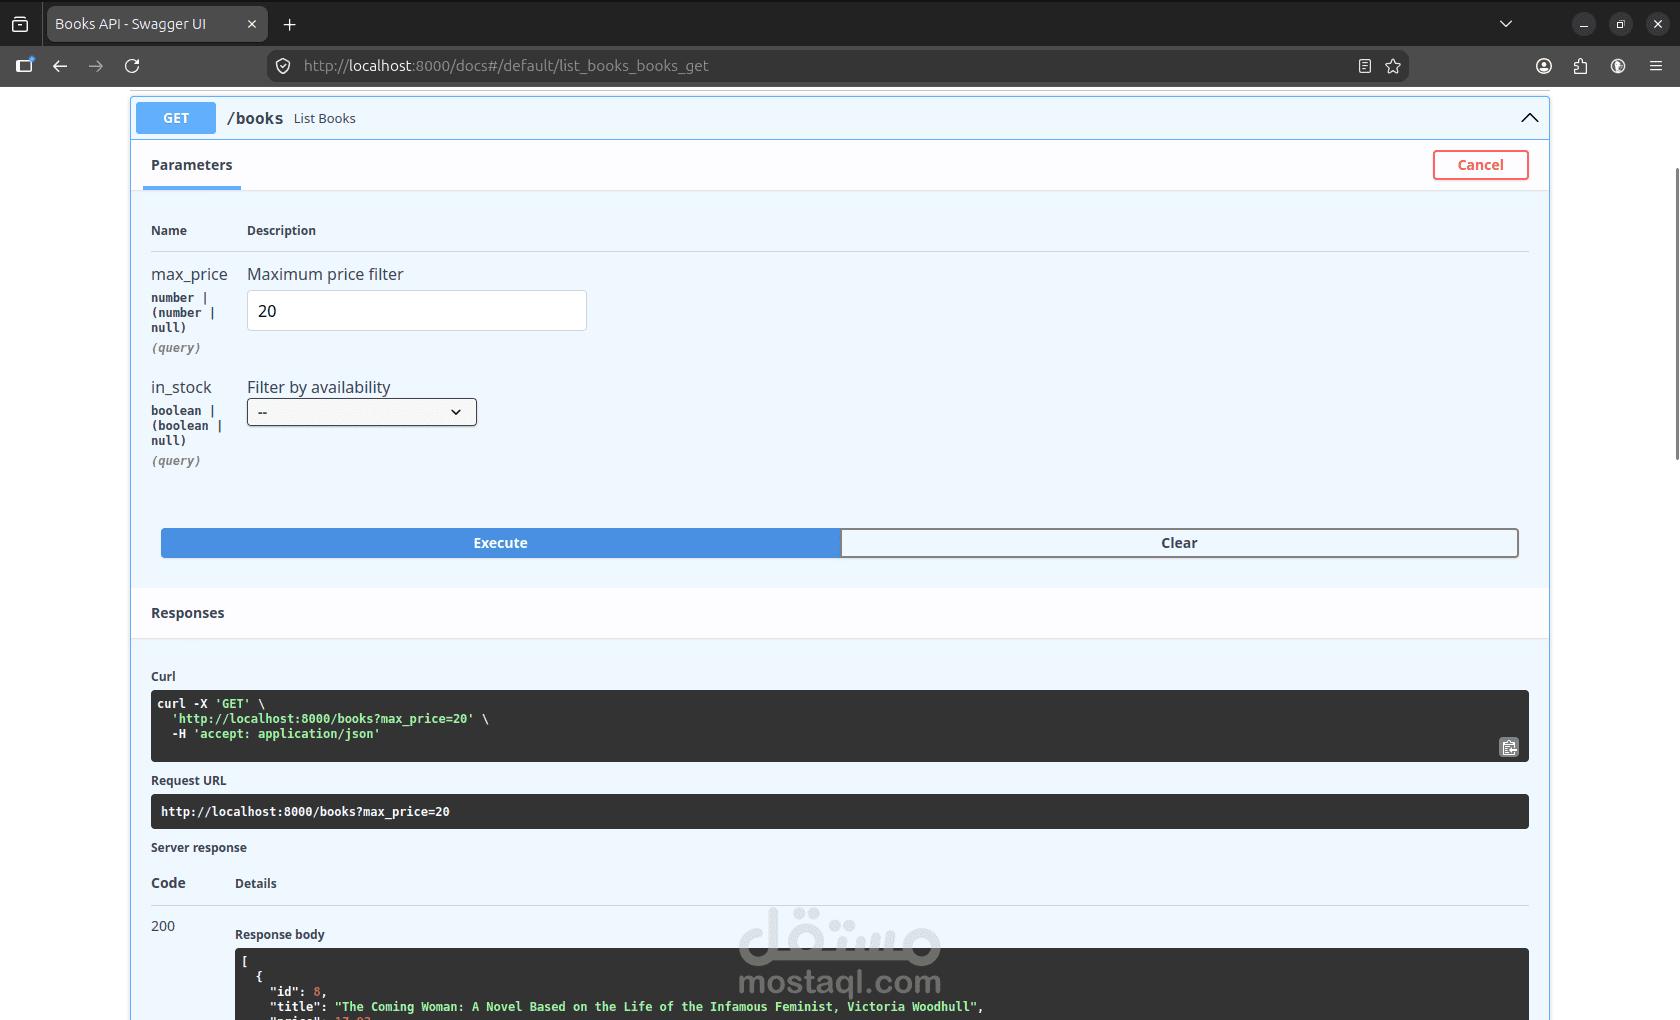
A complete data pipeline that goes beyond simple scraping: a Python scraper collects book data and stores it in a SQLite database, then a FastAPI application serves that data through a REST API with multiple endpoints — listing all records, fetching a single item by ID, and filtering by price or availability.
This demonstrates the full journey from raw data collection to a live, queryable service that other applications can consume, with interactive documentation automatically generated via Swagger UI.
Tech stack: Python, BeautifulSoup4, FastAPI, SQLite, Uvicorn.