Cloud-Based Malicious URL Detection Assistant
تفاصيل العمل
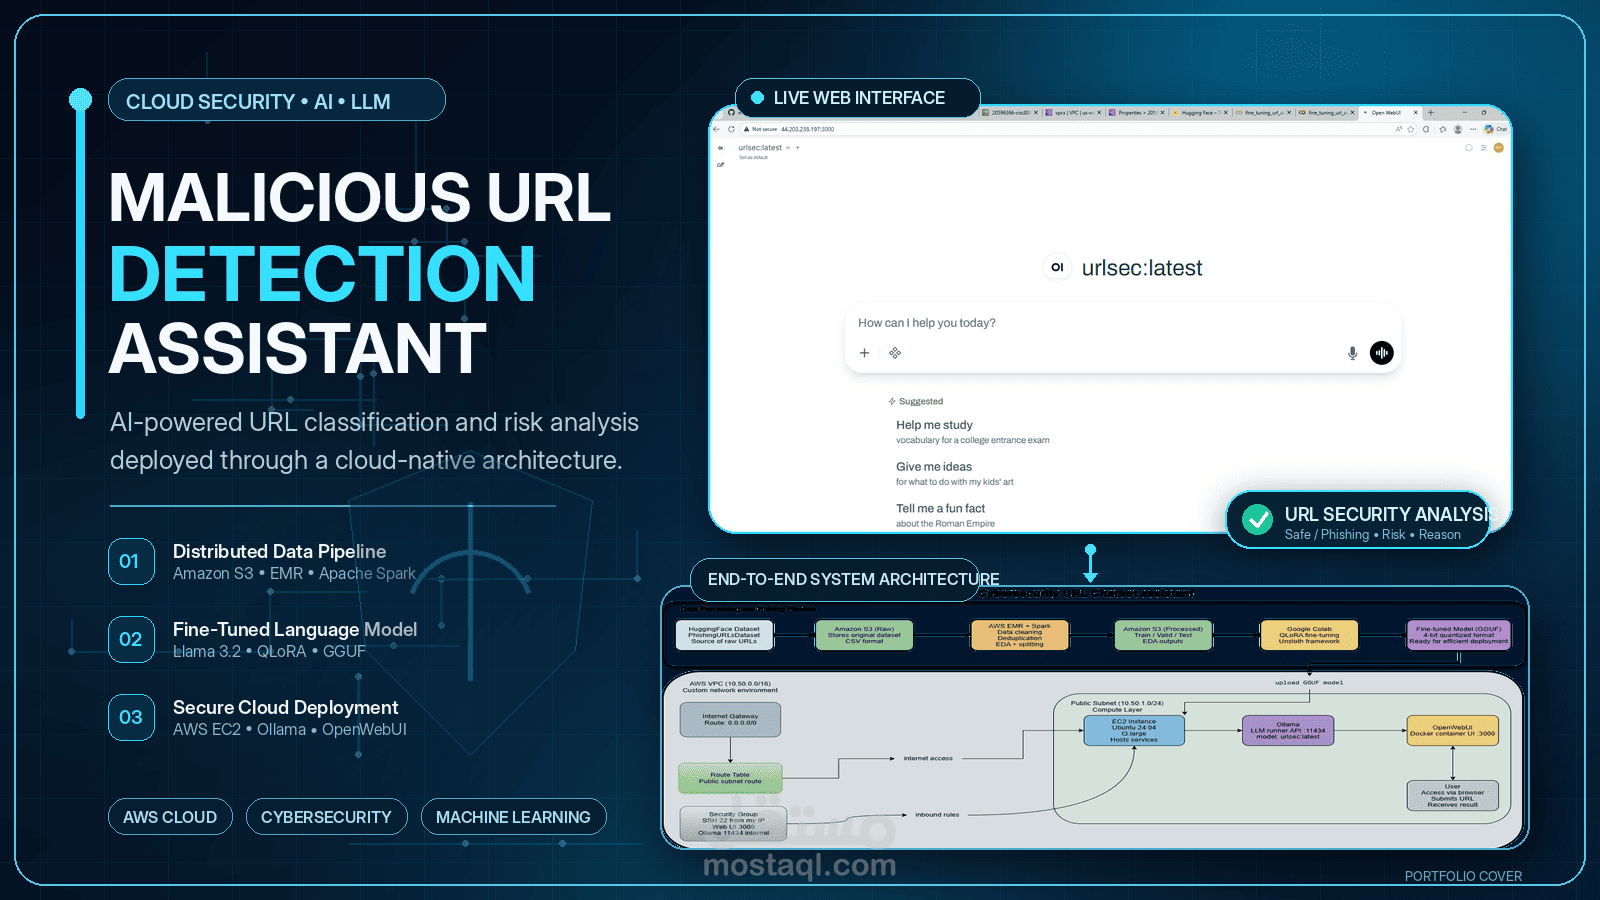
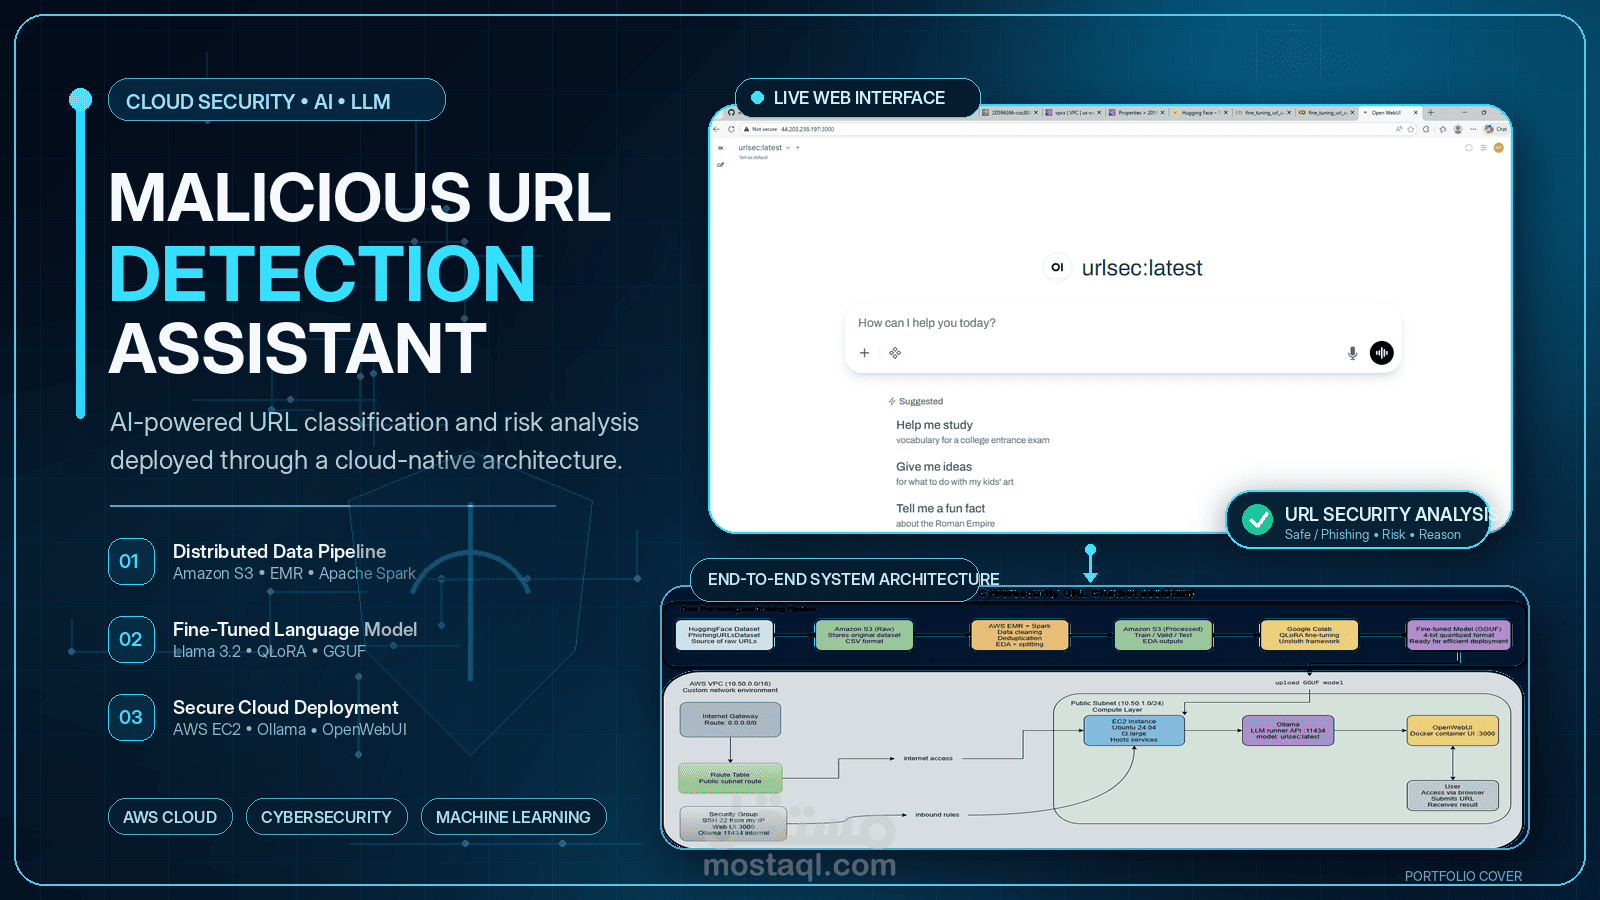
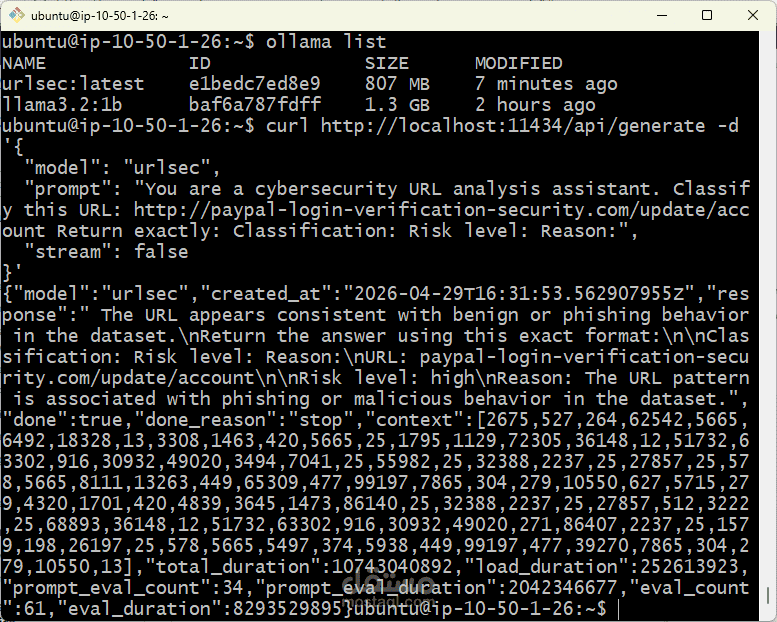
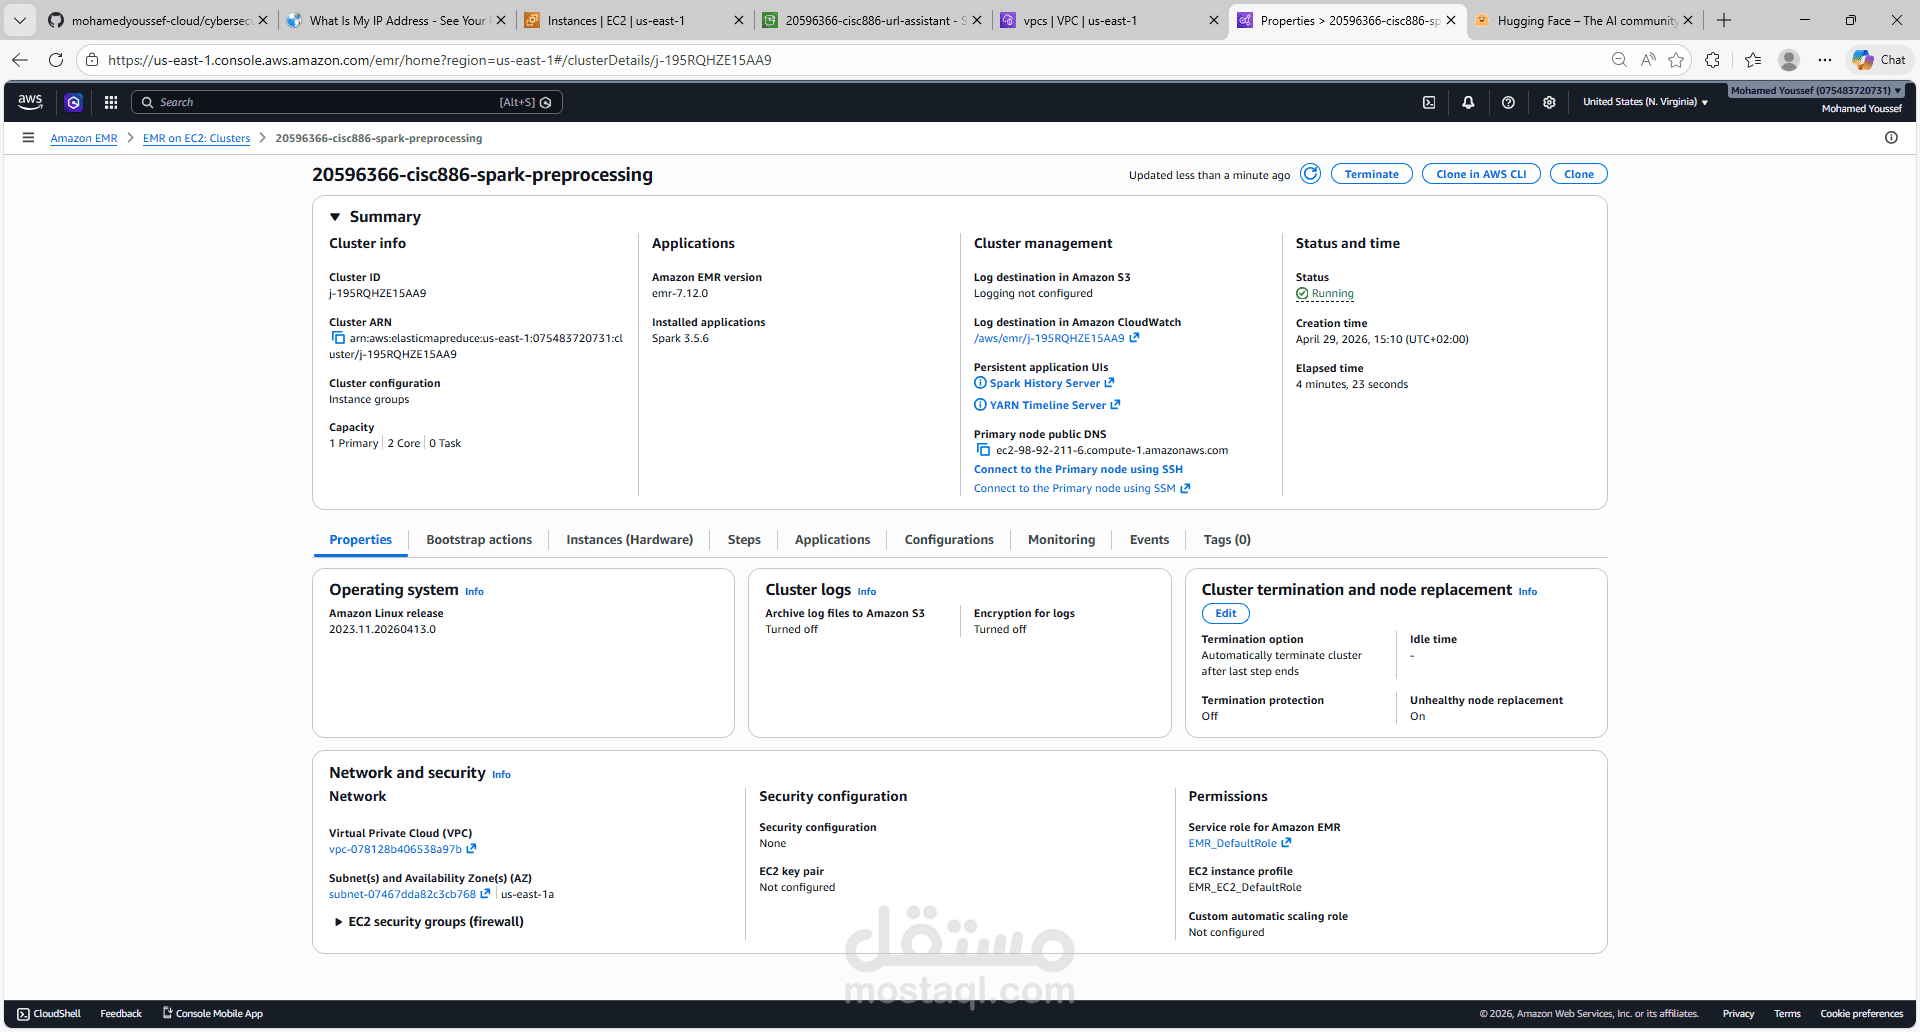
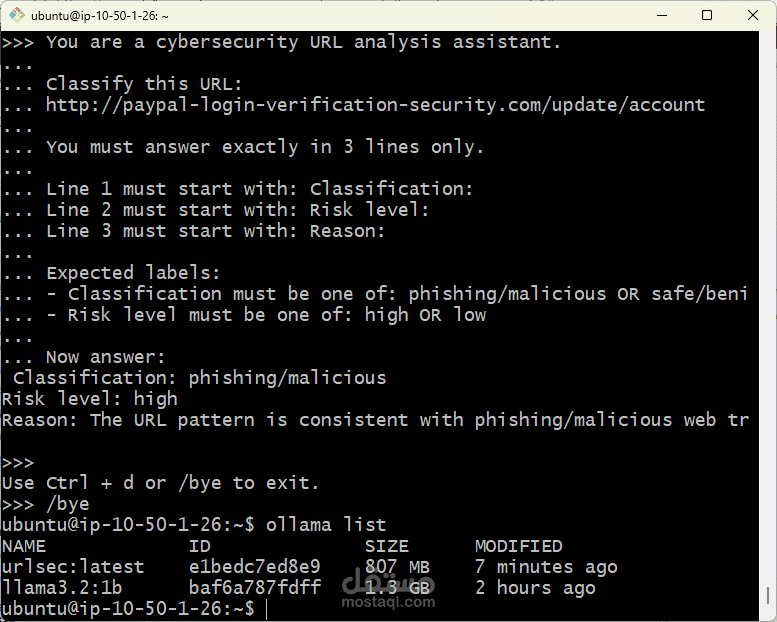
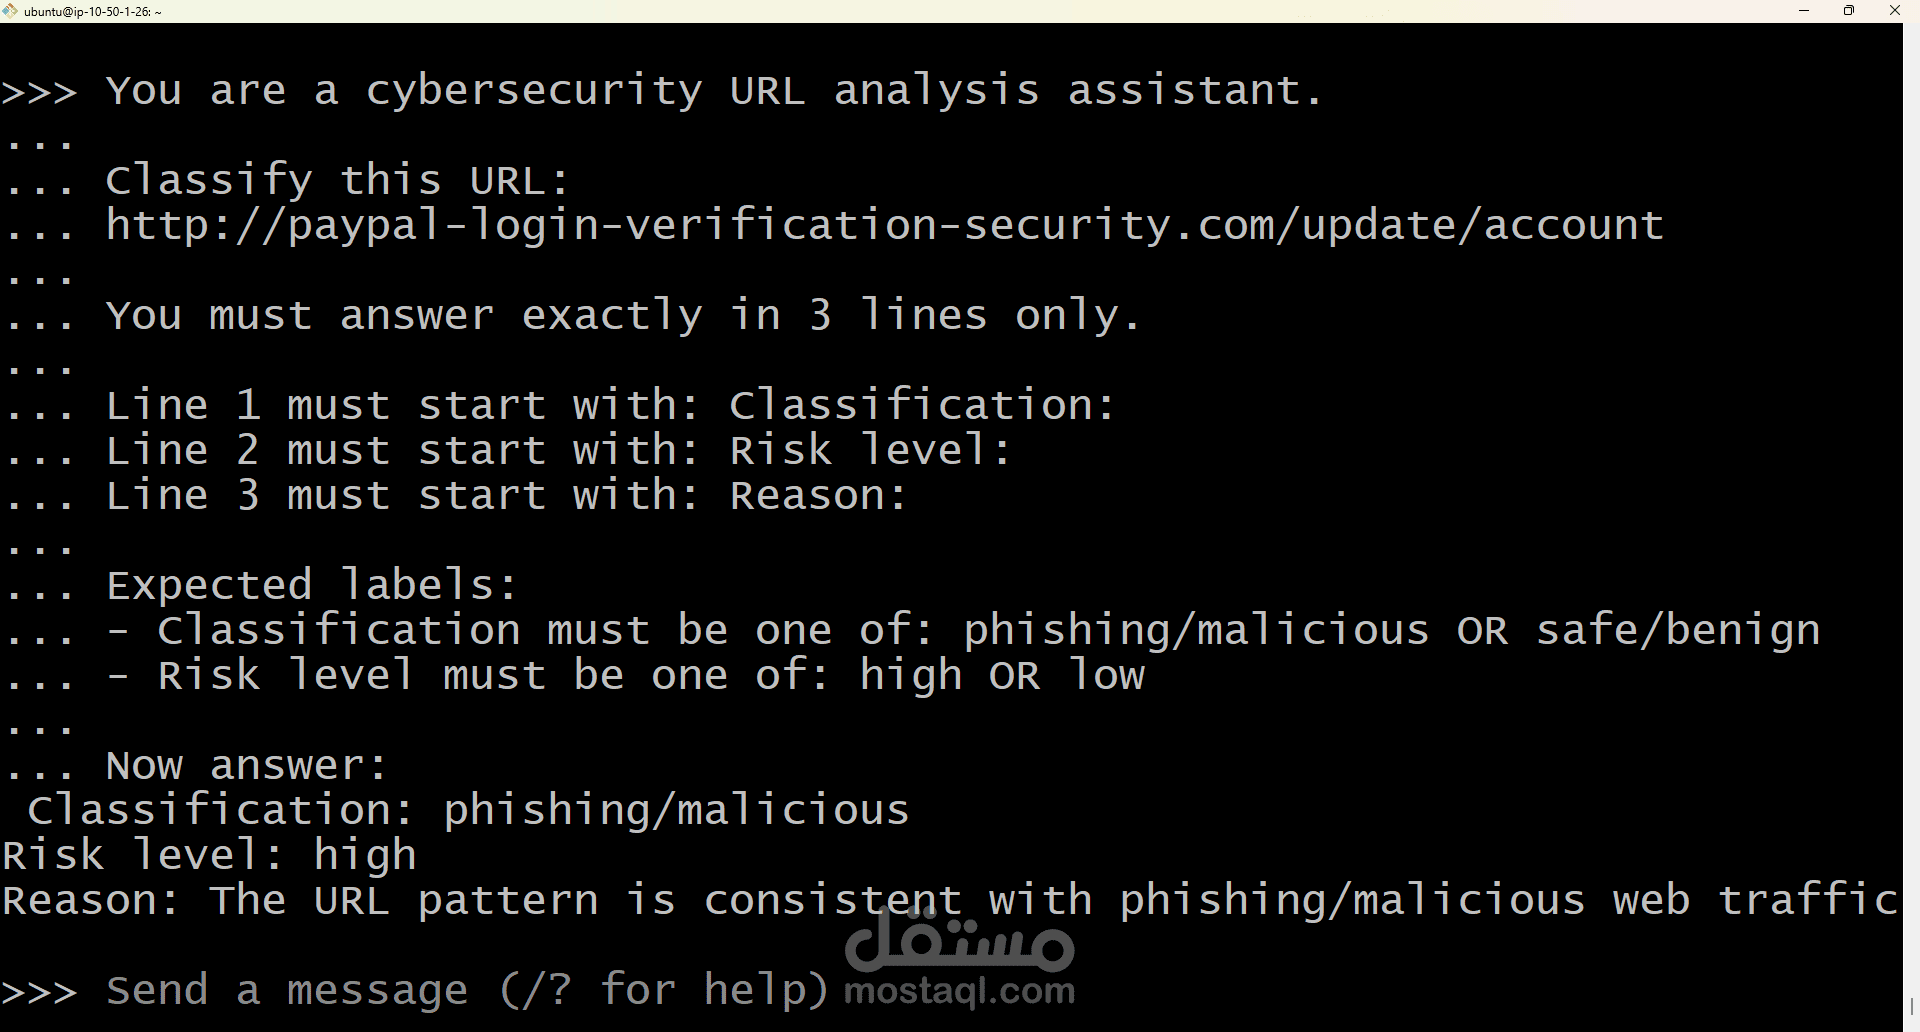
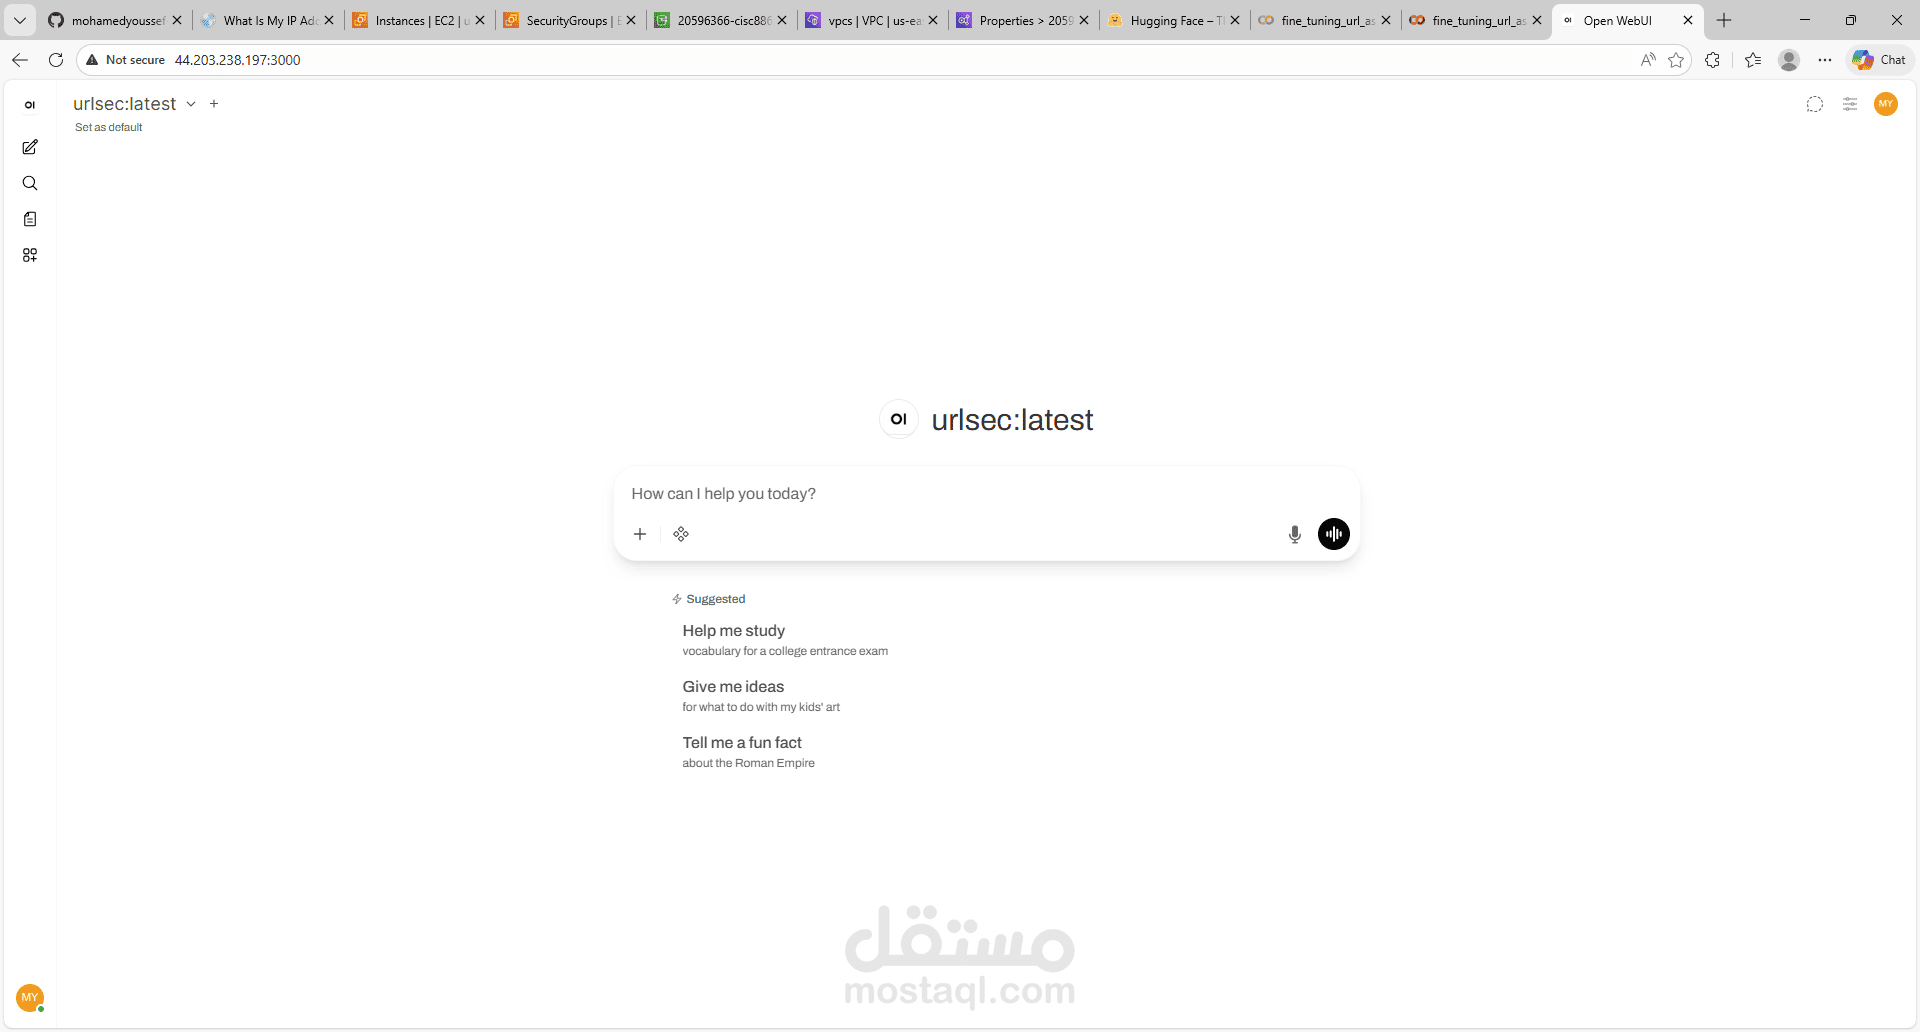
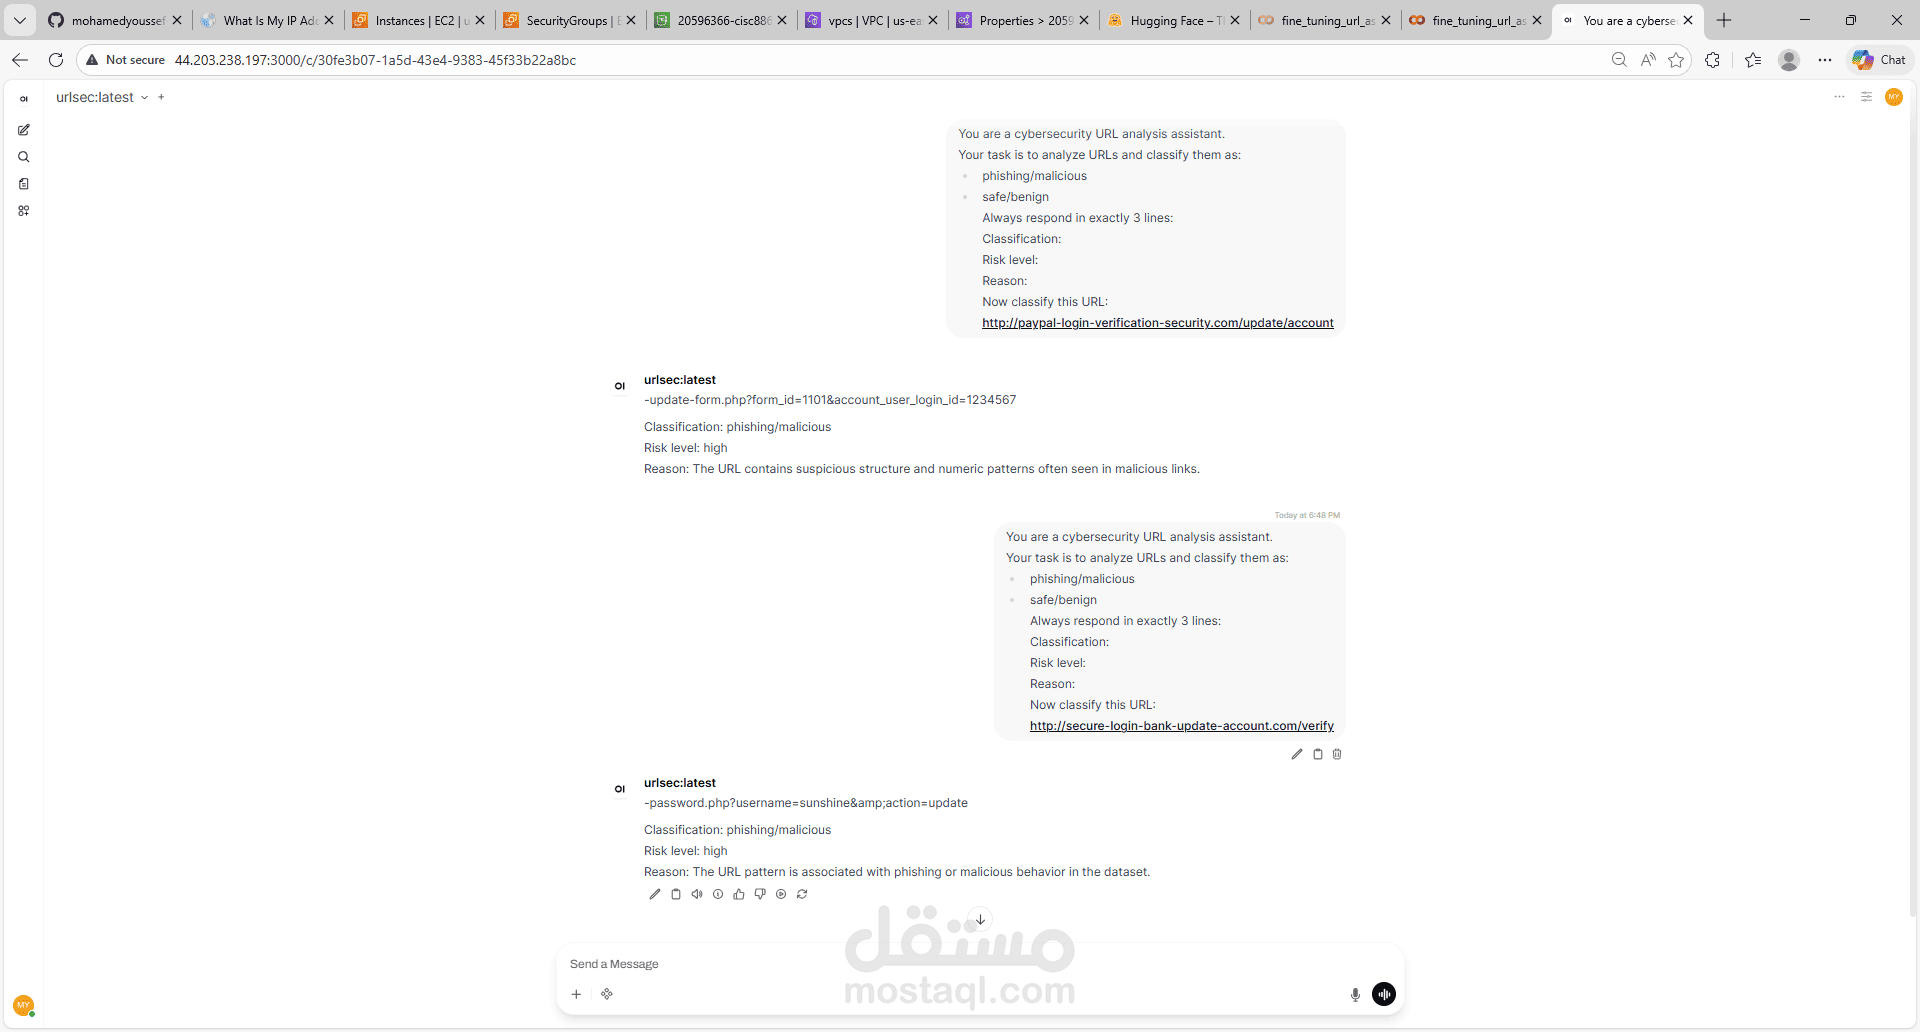
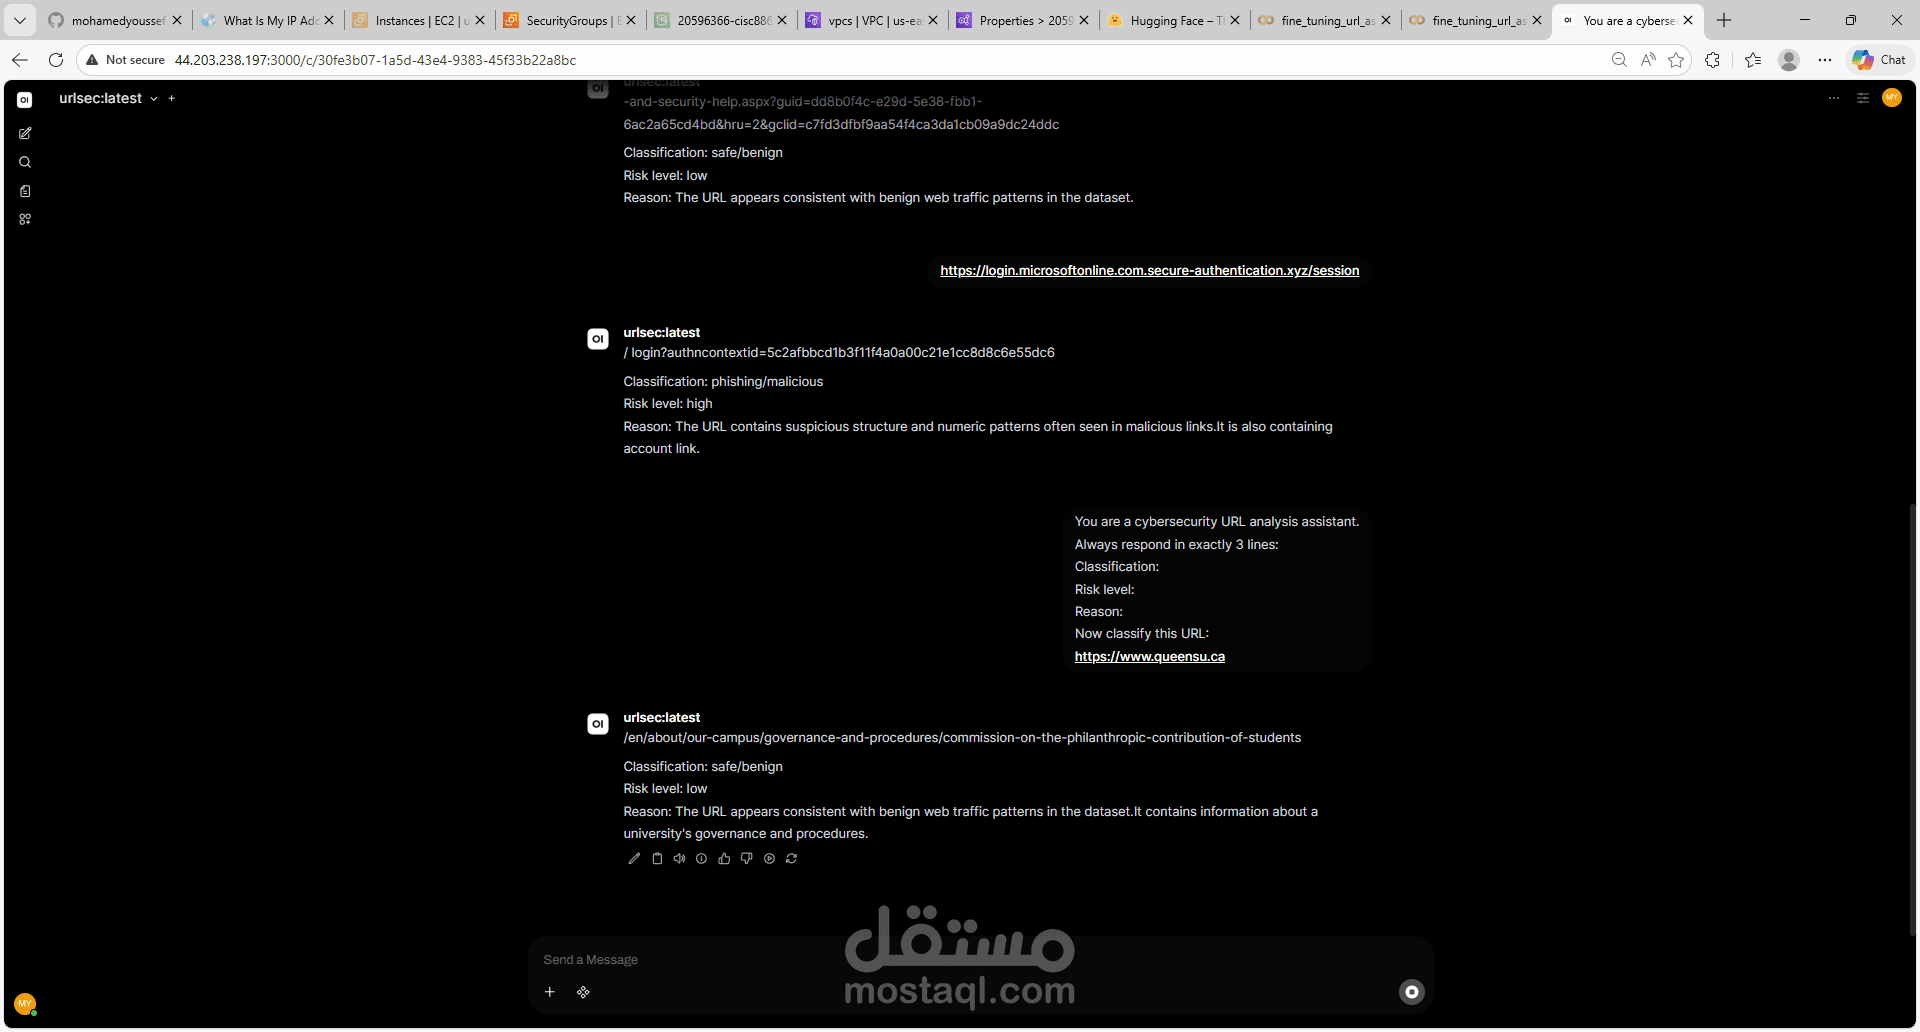
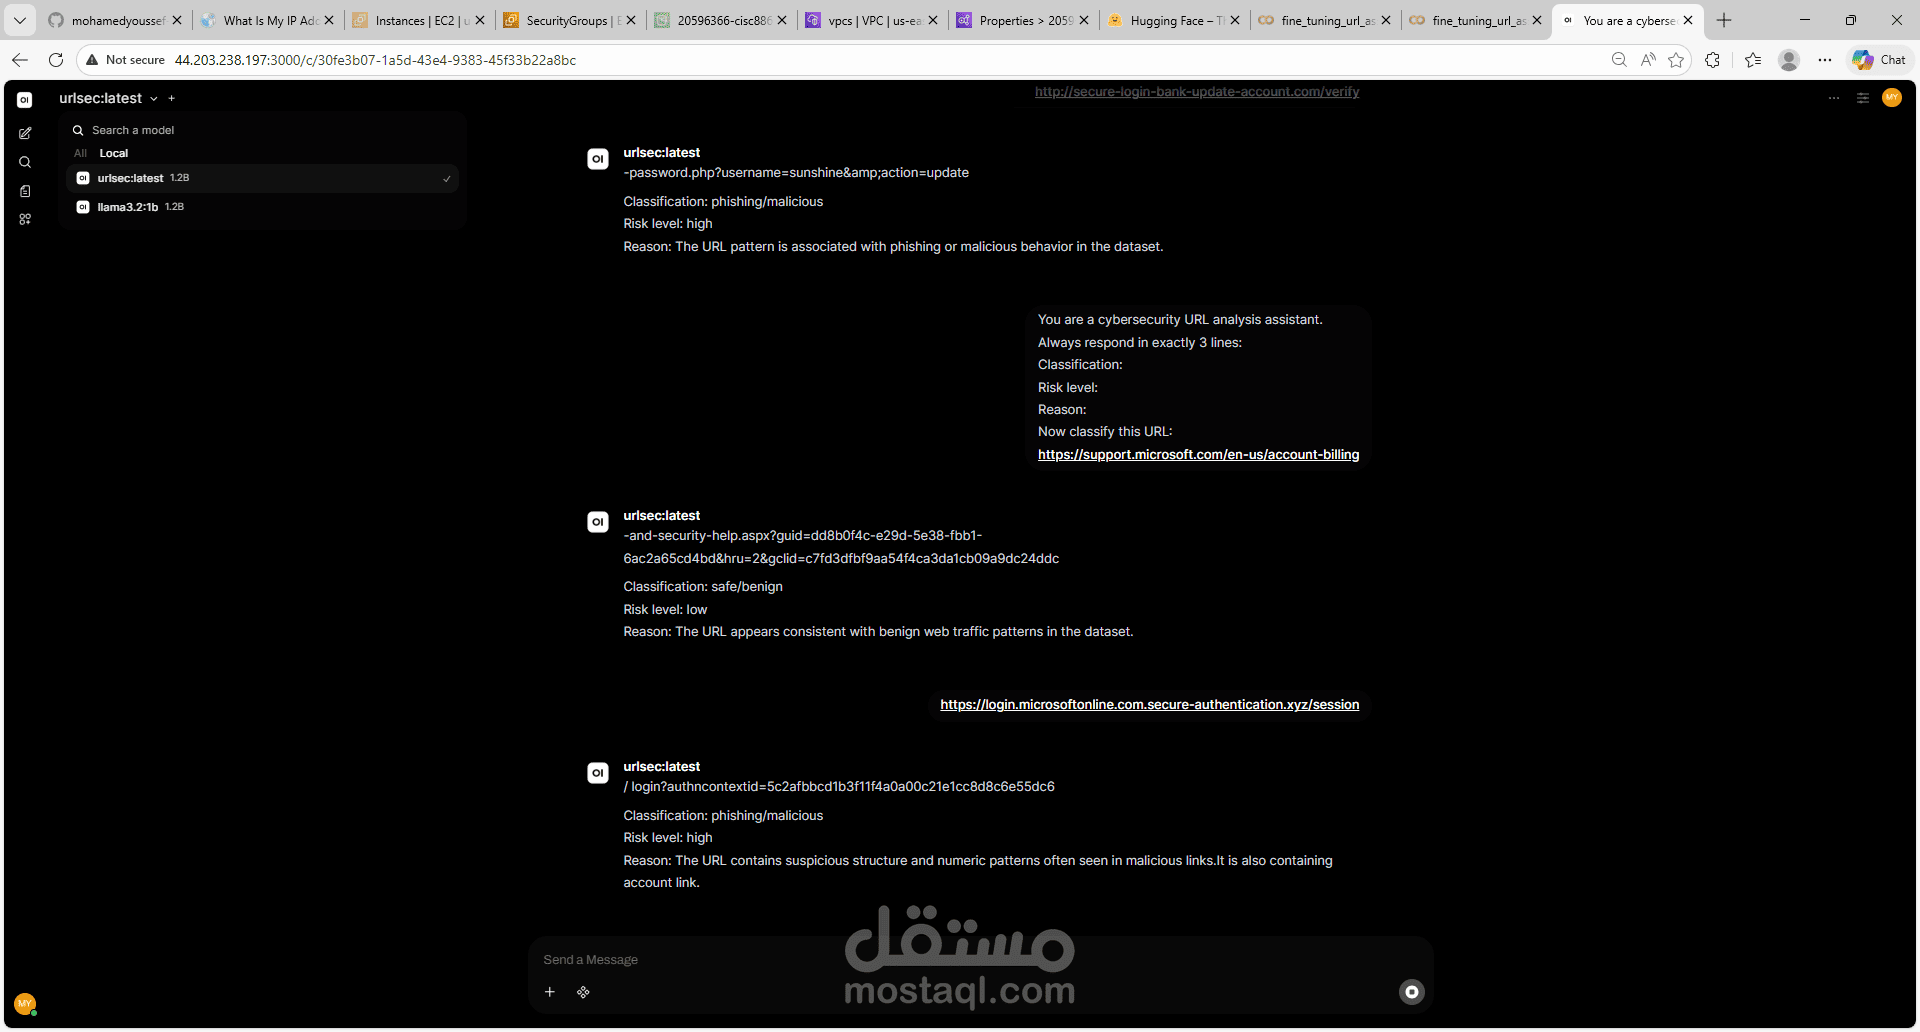
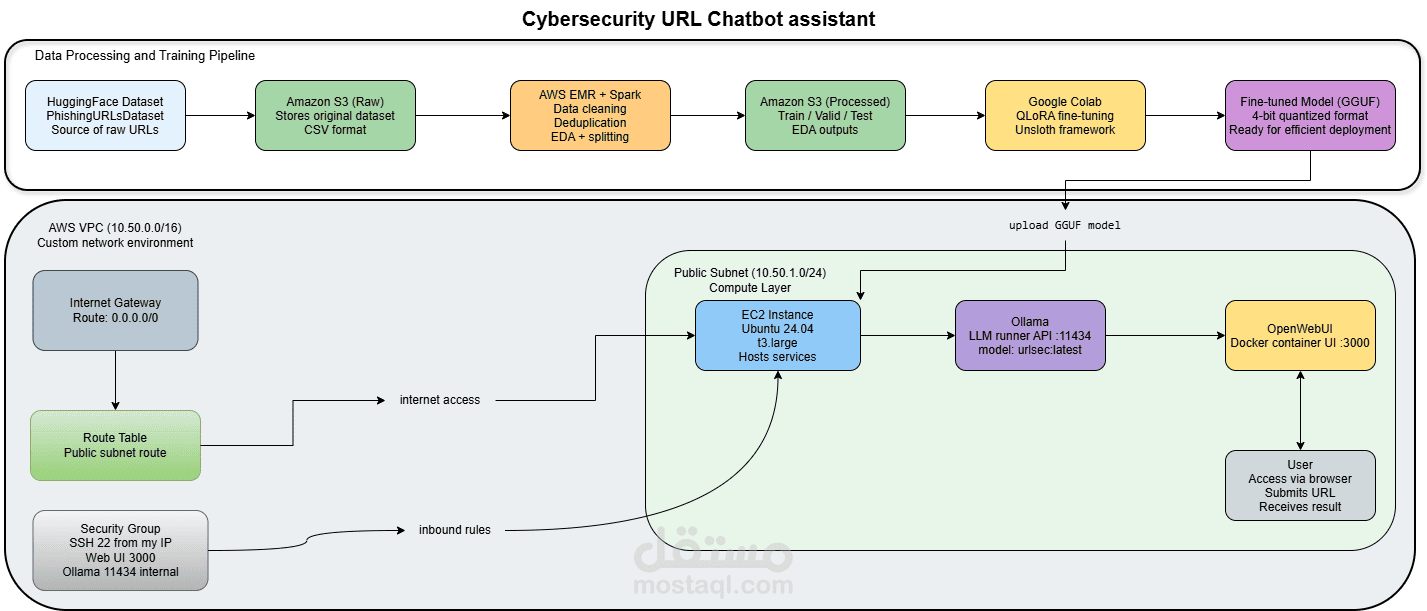
The system starts by storing the phishing URL dataset in Amazon S3. AWS EMR runs a PySpark preprocessing pipeline to clean the data, remove duplicate URLs, generate exploratory outputs, and create train/validation/test splits. The processed data is then used in Google Colab to fine-tune Llama-3.2-1B-Instruct using QLoRA. After training, the model is exported as a GGUF artifact and deployed on an AWS EC2 instance. Ollama serves the model locally, while OpenWebUI provides the browser-based chat interface.
The project is run locally.