تحليل المقالات ل 4 اصناف
تفاصيل العمل
Abstract:
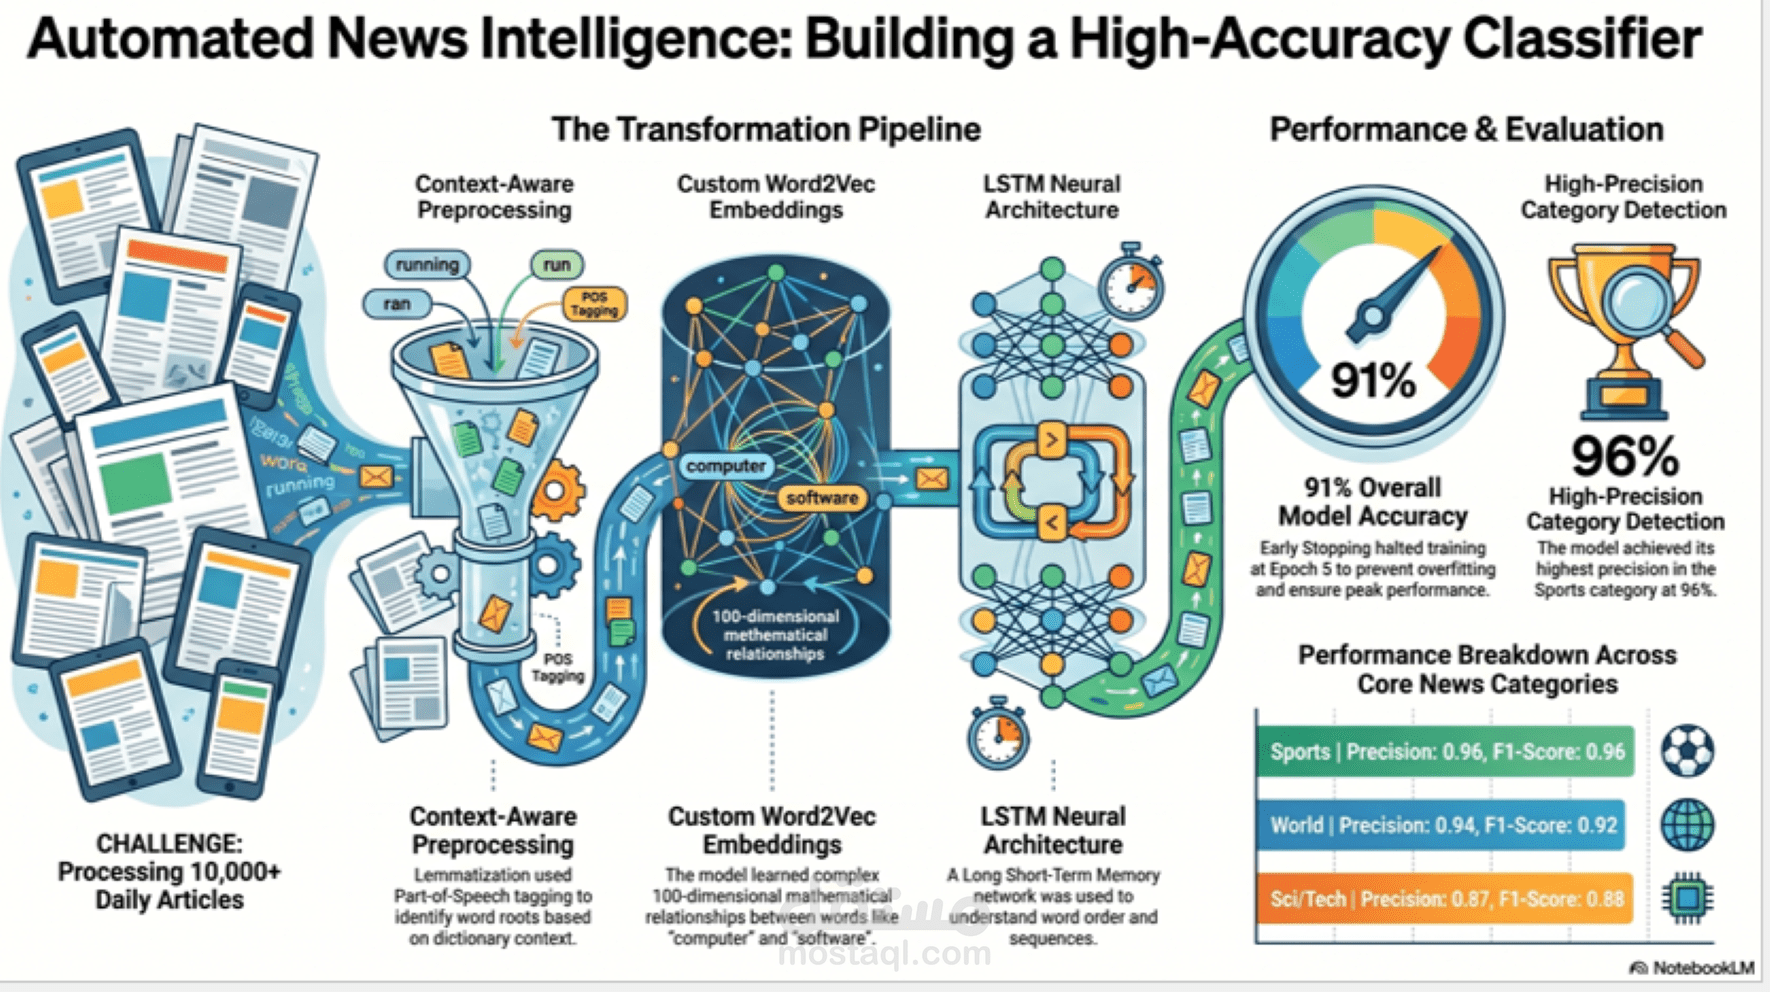
In the modern digital landscape, the exponential growth of unstructured text data presents a massive bottleneck for organizations attempting to process, route, and analyze information in real-time. This project presents an end-to-end Natural Language Processing (NLP) pipeline designed to automatically classify text into four distinct categories (World, Sports, Business, and Sci/Tech). By leveraging custom-trained Word2Vec embeddings and a Long Short-Term Memory (LSTM) neural network, the system successfully understands semantic context and sequential phrasing, achieving an accuracy of 91%. The model is deployed via a Streamlit web application, providing an accessible, real-time user interface for text analysis.